Author: Amber Colvin

  • Understanding Python’s newtype Functionality

    Understanding Python’s newtype Functionality

    Python’s newtype function, introduced in PEP 484, is a simple yet powerful tool for enhancing type safety in Python programming. It allows developers to create distinct types, without adding runtime overhead, which can be used for type checking and improving code readability. This article delves into newtype functionality, its benefits, and practical examples to effectively incorporate it into your projects.

    What is Python’s newtype Function?

    The newtype function is part of Python’s typing module, designed to help developers create custom types. It allows you to define a new type that is functionally equivalent to an existing type, but semantically distinct. This means that while the underlying data structure remains unchanged, the new type provides a way to communicate the unique intent or role of the variable within the code. This is particularly useful for documenting code and ensuring that functions receive the correct types of arguments.

    Why Use newtype in Your Python Code?

    Using newtype offers several benefits. Firstly, it enhances code clarity by providing descriptive names for variables, improving the overall readability and maintainability. It also serves as a tool for type checking during static analysis. By clearly defining expected argument types, developers can catch type errors early, before they lead to bugs in production. Additionally, newtype does not impact runtime performance, as it is purely a type hinting construct.

    How to Implement newtype: A Step-by-Step Guide

    1. Start by importing the newtype function from the typing module:
    2. from typing import newtype
    3. Define your new type by specifying a name and its underlying base type. For instance, to create a UserId type based on integers:
    4. UserId = newtype('UserId', int)
    5. Use the new type in function signatures to indicate the expected type of arguments and return values:
    6. def get_user_name(user_id: UserId) -> str:
    7. Assign values to the new type as you would with the base type:
    8. uid: UserId = UserId(123)

    Practical Examples of newtype in Action

    Consider a scenario where you’re dealing with User IDs and Product IDs, both represented as integers. Using newtype, you can define:

    
    UserId = newtype('UserId', int)
    ProductId = newtype('ProductId', int)
    

    This distinction prevents accidental misuse, such as passing a Product ID to a function that expects a User ID. Here’s how you might implement a function using these types:

    
    def fetch_user_data(user_id: UserId) -> dict:
        # Implementation to fetch user data
        pass
    
    def fetch_product_details(product_id: ProductId) -> dict:
        # Implementation to fetch product details
        pass
    

    By using newtype, any attempt to compile a function call with mismatched type arguments will trigger a type checker warning, helping to maintain type integrity across your codebase.

  • Understanding ** in Python: A Comprehensive Guide

    Understanding ** in Python: A Comprehensive Guide

    In Python, the ** operator serves critical functions that enhance the language’s flexibility and power. Understanding how to leverage this operator can significantly boost your programming capabilities. Its primary uses include performing exponentiation and unpacking dictionary elements, making it a versatile tool for developers.

    What Does ** Mean in Python?

    The ** operator in Python is primarily used for two operations: exponentiation and dictionary unpacking. Exponentiation allows you to raise numbers to a power, while dictionary unpacking helps in merging or expanding dictionary elements within functions. These operations form the foundation of many advanced programming tasks in Python.

    Using ** for Exponentiation

    Exponentiation is a mathematical operation that involves raising a number to the power of another. In Python, the ** operator facilitates this operation, making it easy to perform calculations involving powers.

    For example, to calculate 5 raised to the power of 3, you would write:

    result = 5 ** 3

    This statement will yield a result of 125, as it computes 5 * 5 * 5. The ** operator is both intuitive and efficient for mathematical computations, especially when dealing with large data sets or complex formulas.

    Another practical application could be calculating powers of ten, which is common in scientific calculations:

    ten_power_six = 10 ** 6

    This results in 1,000,000, demonstrating the operator’s utility in handling large numbers with ease.

    Using ** for Dictionary Unpacking

    The ** operator is also pivotal in dictionary unpacking, a feature that simplifies the process of combining dictionaries or passing them as keyword arguments in functions.

    Consider the following example of merging two dictionaries:

    dict1 = {'a': 1, 'b': 2}
    dict2 = {'b': 3, 'c': 4}
    merged_dict = {**dict1, **dict2}

    Here, merged_dict will be {'a': 1, 'b': 3, 'c': 4}. Notice that the value of ‘b’ from dict2 overwrites that from dict1 due to its later position. This behavior is essential when managing configuration data or updating settings dynamically.

    Another useful scenario is passing dictionary elements as arguments to a function:

    def print_values(a, b, c):
        print(a, b, c)
    
    values_dict = {'a': 10, 'b': 20, 'c': 30}
    print_values(**values_dict)

    This example demonstrates how the ** operator can seamlessly pass dictionary values to a function, maintaining clean and readable code. Such techniques are invaluable in scenarios where dynamic input handling is required.

    Mastering the ** operator for both exponentiation and dictionary unpacking not only simplifies code but also enhances its functionality, making it a crucial component in any Python programmer’s toolkit.

  • Understanding String Interpolation in Programming

    Understanding String Interpolation in Programming

    String interpolation is a powerful programming feature that allows developers to embed variables directly into strings, making code more readable and concise. This method is widely used across various programming languages, offering a dynamic way to handle string formatting without the need for cumbersome concatenations.

    What is String Interpolation?

    String interpolation refers to the process of inserting the value of variables or expressions directly into a string. This is typically achieved by using special syntax in the programming language to identify and replace placeholders with actual data values. By eliminating the need for explicit string concatenation, string interpolation simplifies the task of constructing complex strings.

    How Does String Interpolation Work?

    The mechanism of string interpolation varies between programming languages, but the core concept remains the same: placeholders within a string are replaced by the values of corresponding variables. For instance, in languages like Python, a common syntax uses f-strings, where each placeholder is preceded by a dollar symbol or enclosed within curly braces. The language’s interpreter evaluates the expression inside the placeholder and inserts the result into the final string.

    Examples of String Interpolation in Different Languages

    String interpolation is implemented differently across various programming languages, each offering unique syntax and capabilities:

    • Python: Uses f-strings. For example, name = "Alice"; greeting = f"Hello, {name}!" will result in Hello, Alice!.
    • JavaScript: Utilizes template literals with backticks. Example: const name = "Bob"; const greeting = `Hello, ${name}!`; results in Hello, Bob!.
    • Ruby: Employs the #{} syntax within double-quoted strings. For example, name = "Eve"; greeting = "Hello, #{name}!" yields Hello, Eve!.
    • Swift: Uses the backslash and parentheses syntax with strings. Example: let name = "Tom"; let greeting = "Hello, \\(name)!" gives Hello, Tom!.

    Benefits of Using String Interpolation

    String interpolation offers several advantages that enhance both the development process and the resulting code:

    • Readability: By reducing the clutter of concatenation operators, string interpolation makes code easier to read and understand.
    • Efficiency: Interpolation often leads to more efficient code execution, as it simplifies how strings are constructed and processed.
    • Maintenance: Code that uses interpolation is typically easier to maintain and less prone to errors, as variable values are inserted directly into the string.
    • Flexibility: Interpolation allows for the inclusion of complex expressions and calculations within strings, enhancing the flexibility of code.

    In summary, string interpolation is a valuable tool for developers, streamlining the process of creating dynamic and readable strings across various programming languages. By understanding and utilizing this feature, programmers can write cleaner, more efficient, and maintainable code.

  • HTML Include: Reuse a Shared Fragment Across Pages

    HTML Include: Reuse a Shared Fragment Across Pages

    To include a shared fragment of HTML, load a trusted file and place its contents into a designated element on each page. This HTML inclusion technique works on a static server with JavaScript. Plain HTML has no universal include statement; a server template or a build tool can assemble the page before it reaches the browser instead.

    Include HTML with a small static-site example

    Imagine a site with two pages that need the same navigation. Keep the links in one fragment, then let each page request it. The HTML include workflow below uses one script for both pages and checks the response before inserting anything.

    Create this layout in a directory named site:

    site/
      index.html
      about.html
      fragments/
        nav.html
      assets/
        include.js
    

    Put this in fragments/nav.html. It is a fragment, not a complete document:

    <nav aria-label="Primary">
      <a href="/index.html">Home</a>
      <a href="/about.html">About</a>
    </nav>
    

    Put the following in index.html. Create about.html with the same contents, changing the heading to About. Both pages contain a placeholder for the navigation and refer to the same script.

    <!doctype html>
    <html lang="en">
    <head>
      <meta charset="utf-8">
      <title>Example site</title>
      <script src="/assets/include.js" defer></script>
    </head>
    <body>
      <div id="site-nav"></div>
      <main><h1>Home</h1><p>Welcome to the site.</p></main>
    </body>
    </html>
    

    Put this code in assets/include.js:

    async function loadNavigation() {
      const target = document.getElementById("site-nav");
      try {
        const response = await fetch("/fragments/nav.html");
        if (!response.ok) throw new Error(`HTTP ${response.status}`);
        target.innerHTML = await response.text();
      } catch (error) {
        console.error("Navigation could not be loaded:", error);
        target.textContent = "Navigation is unavailable.";
      }
    }
    loadNavigation();
    

    From inside site, run python -m http.server 8000, then open http://localhost:8000/index.html and http://localhost:8000/about.html. Both pages should display the same two links. To load the shared markup into another page, add the same placeholder and script reference there. Change the fragment, refresh each page, and both menus should reflect the edit. This local server is for development; use a suitable web server or hosting service for deployment.

    Follow the request and the paths

    The deferred script runs after the document has been parsed, so the placeholder is available when loadNavigation looks it up. The browser requests the fragment separately, reads the response as text, and parses it into the placeholder. The rest of the page can appear while the request is in progress. Opening the files directly with a file:// URL can encounter browser restrictions, so serve them over HTTP for this exercise. When adding the fragment to a page, keep its expected placeholder in the document; otherwise the script has nowhere to put the result. The Fetch API documentation explains that an HTTP error response still resolves the promise, which is why the example checks response.ok.

    Each path beginning with / is relative to the origin’s root. For the local server, /fragments/nav.html means http://localhost:8000/fragments/nav.html, regardless of which example page requested it. The same applies to the links inside the inserted fragment. If you deploy under a subdirectory such as /demo/, adjust the script URL, fragment URL, and navigation links to include that prefix. A root-relative path does not automatically inherit the page’s deployment folder.

    By contrast, fragments/nav.html is resolved against the page’s base URL, not the script file’s folder. A <base> element can change that base. Relative links inserted from the fragment are also resolved in the containing document, not automatically relative to the fragment file. MDN’s URL guide shows how relative references are resolved. Keeping paths deliberate prevents a shared menu from working on the home page and failing on a nested page.

    Decide when to assemble the page

    A client-side HTML include keeps the source files simple, but the menu appears only after JavaScript runs and the request succeeds. A visitor with JavaScript disabled will see the fallback page content but no menu in this example. For navigation that must be present immediately, assemble the shared markup on the server or during a build instead.

    With a server template, a template engine combines a page and a partial when serving a request. With a static-site generator, the build process combines them ahead of time and publishes complete pages. Both approaches can reuse a single maintained fragment while delivering the navigation in the initial response. This reuse of page markup leaves the source fragment editable in one place, while the generated files each contain their own copy. Their exact syntax and path rules depend on the chosen tool; configure and test that tool rather than expecting the browser to interpret its directives.

    If you include HTML on the client, budget for an extra request and decide how failures should appear. A build-time HTML include avoids that browser request for the fragment, though rebuilding and redeploying is necessary after an edit. The right choice depends on whether you already have a build pipeline and whether the content must be available before scripts execute.

    Keep the fragment trustworthy

    You can include HTML from your own controlled files in this example, but do not insert arbitrary user-submitted markup with innerHTML. It parses the string as markup and can introduce cross-site scripting through malicious attributes or other content. MDN’s security guidance explains the risk. For plain user text, use textContent; for untrusted rich content, use an appropriate, maintained sanitizer and a security policy.

    A reusable page fragment should also have stable IDs and accessible labels. If it appears more than once on one page, duplicate IDs can break references. Keep one navigation landmark here, and test its links with a keyboard after loading. If the response comes from another origin, that server must permit the request through CORS; the same-origin example avoids that configuration.

    Diagnose a missing menu

    When you include HTML and the menu does not appear, the most likely cause is a wrong path. Open developer tools, select the Network panel, reload the page, and find the request for nav.html. A 404 points to a missing file at the requested URL: compare that URL with your server’s document root, file names, and any deployment prefix. Fix the path, reload, and confirm a successful response contains the expected fragment. If the request is absent, check the Console for a script error and verify that the script URL and placeholder ID match the example.
  • Understanding the While Loop in Programming

    Understanding the While Loop in Programming

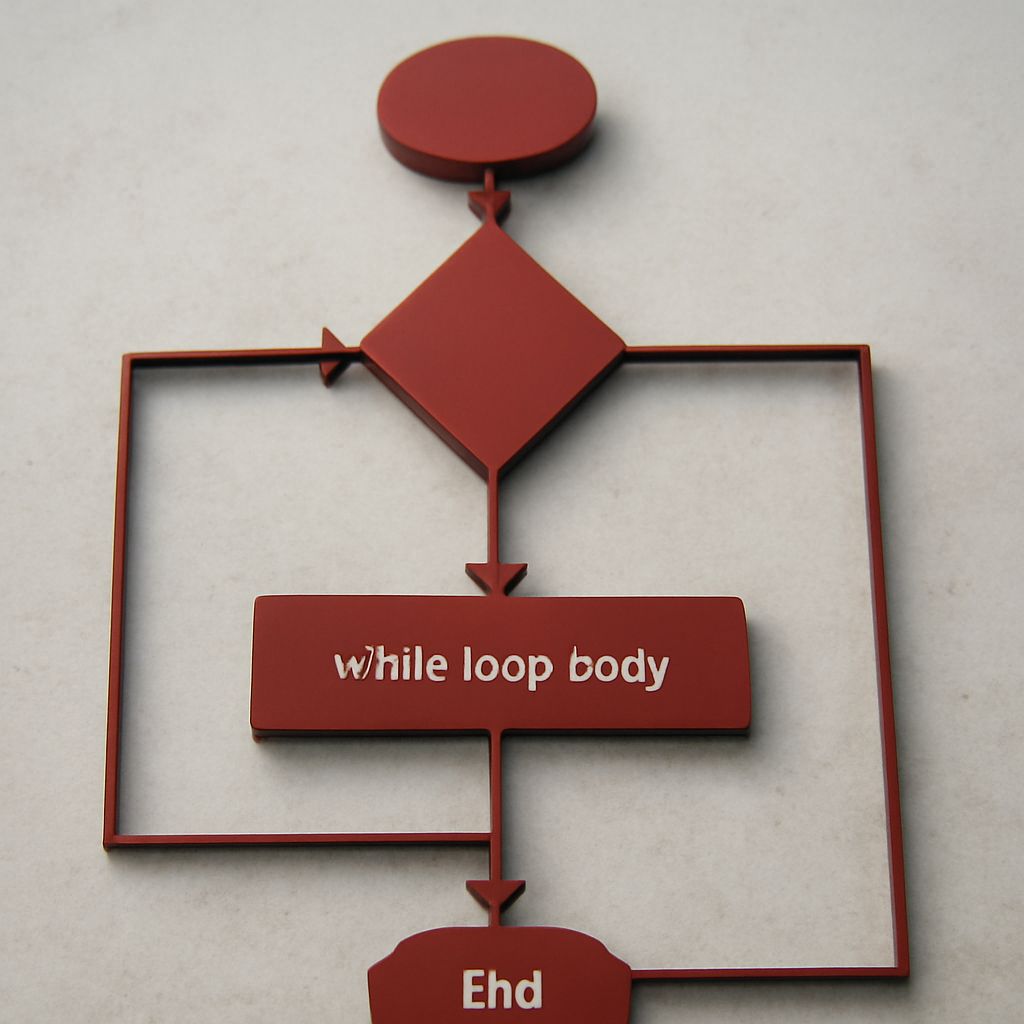
    The while loop is an essential programming construct that allows code to be executed repeatedly based on a given Boolean condition. It’s a fundamental tool for creating dynamic and responsive programs, enabling developers to automate repetitive tasks and manage control flow in their applications. By understanding the syntax, use cases, and best practices associated with while loops, programmers can enhance their coding efficiency and problem-solving skills.

    What is a While Loop?

    A while loop is a control flow statement that repeatedly executes a block of code as long as a specified condition evaluates to true. The condition is checked before each iteration, allowing the loop to continue running until the condition becomes false. This makes while loops particularly useful for scenarios where the number of iterations is not predetermined.

    How to Use a While Loop: Syntax and Examples

    The basic syntax of a while loop in many programming languages is straightforward. Here is a typical structure:

    
    while (condition) {
        // Code to be executed
    }


    In this structure, the condition is evaluated before each iteration. If it returns true, the code within the loop executes. Here is an example in Python:

    
    count = 0
    while count < 5:
        print("Count is:", count)
        count += 1


    This Python code snippet will print the current value of count until it reaches 5, demonstrating how the loop continues while the condition count < 5 is true.

    Common Use Cases for While Loops

    While loops are versatile and can be applied in various programming scenarios. Some common use cases include:

    • Processing Input Until a Certain Condition is Met: While loops are ideal for reading data until a specific input is received. For example, continuously asking a user for input until they provide a valid response.
    • Simulating Real-World Processes: Many simulations require loops that run until a condition changes, such as simulating the movement of objects until they reach a particular position or state.
    • Polling or Monitoring Tasks: While loops can be used to repeatedly check the status of a system or task until a certain condition is satisfied, such as waiting for a file to download or a server response.

    Best Practices for Using While Loops

    To maximize the effectiveness and efficiency of while loops, consider these best practices:

    • Ensure the Condition Will Eventually Become False: Always make sure that the loop condition will eventually evaluate to false. Infinite loops can occur if the condition is always true, which can cause the program to hang.
    • Avoid Complex Conditions: Simplify the loop's condition for better readability and maintainability. Complex conditions can make the code difficult to understand and debug.
    • Monitor Performance: While loops can consume significant processing power if not carefully managed. Consider the performance implications, especially in resource-intensive applications.
    • Use Break Statements Sparingly: While break statements can be useful for exiting a loop early, overuse can lead to code that's hard to follow. Strive for clarity by keeping loop logic straightforward.

    By adhering to these best practices, programmers can effectively utilize while loops to create efficient, scalable, and maintainable code.

  • Understanding Python Attributes in Programming

    Understanding Python Attributes in Programming

    In the world of programming, Python stands out for its simplicity and versatility. A fundamental aspect of Python programming is understanding its attributes, which play a crucial role in object-oriented programming. Attributes in Python are essentially variables that belong to an object or class, and they hold data related to the object or class. This article delves into what Python attributes are, their types, and how to use them effectively in programming.

    What Are Python Attributes?

    Python attributes are characteristics or properties associated with Python objects. They are defined within classes and are accessed using the dot (.) notation. Attributes can store data that belongs to an instance of a class, and they help in defining the state or quality of that instance. In essence, attributes facilitate the creation of objects with specific traits.

    Types of Python Attributes

    Python attributes can be broadly categorized into two types: instance attributes and class attributes.

    • Instance Attributes: These are variables that are specific to an instance of a class. Each object or instance created from a class has its own separate set of instance attributes. For example, if you have a class Car, each object of this class can have its own color and model instance attributes.
    • Class Attributes: These are variables that are shared across all instances of a class. Class attributes are defined within a class but outside any instance methods. They are useful for storing constants or default values that apply to all instances. For instance, if all cars have four wheels, a class attribute named wheels with a value of 4 can be used.

    How to Use Python Attributes Effectively

    Effectively using Python attributes involves understanding their scope and lifetime. Here are some best practices for leveraging Python attributes in your programming:

    • Initialization: Always initialize instance attributes within the __init__ method. This ensures each object starts with a clean state or specific default values.
    • Encapsulation: To protect the integrity of data, consider using private attributes. In Python, prefixing an attribute name with an underscore (e.g., _attribute) is a convention to indicate that it should be treated as non-public.
    • Access and Modification: Use getter and setter methods to access and modify private attributes. These methods provide a layer of abstraction and flexibility to change the internal implementation without affecting external code.
    • Consistency: Maintain consistency between class and instance attributes. If a value needs to be shared among all instances, use a class attribute. Otherwise, rely on instance attributes for unique object properties.

    Understanding and effectively using Python attributes can significantly enhance your programming skills. By distinguishing between instance and class attributes, and applying best practices for their use, you can write more efficient and organized code. Attributes not only define the properties of objects but also contribute to the structural integrity and functionality of your programs.

  • Understanding JSON.stringify in JavaScript

    Understanding JSON.stringify in JavaScript

    In JavaScript development, the JSON.stringify function serves a fundamental role by transforming JavaScript objects into JSON strings. This process is essential for data serialization, enabling data exchange between client and server or storing structured data in text format. Mastering JSON.stringify can streamline data handling and improve web applications’ performance.

    What is JSON.stringify and Why Use It?

    JSON.stringify is a built-in JavaScript method that converts a JavaScript object or array into a JSON string. This conversion is crucial for sending data as a text string over the internet. JSON, or JavaScript Object Notation, is a lightweight format for data interchange that is easy for humans to read and write, and easy for machines to parse and generate.

    Using JSON.stringify, developers can serialize complex data structures, enabling efficient data transmission. This is particularly useful when working with APIs or storing data in a format that can be easily retrieved and manipulated.

    How Does JSON.stringify Work?

    The JSON.stringify function takes one to three parameters. The primary parameter is the object to be converted. Optionally, you can use a replacer function or array to filter properties and a space argument to add indentation for readability:

    • Object: The JavaScript object you want to convert into a JSON string.
    • Replacer (optional): A function or array that acts as a filter for selecting properties to include in the JSON string.
    • Space (optional): A number or string used to control spacing in the JSON output, enhancing readability.

    By default, JSON.stringify processes all enumerable properties of the object. However, with a replacer function, you can customize which properties are included or transform the values during serialization.

    Practical Examples of Using JSON.stringify

    Consider a basic example where you have a JavaScript object representing a user profile:

    const user = {
      name: "John Doe",
      age: 30,
      profession: "Developer"
    };

    By applying JSON.stringify, you can convert this object into a JSON string:

    const jsonString = JSON.stringify(user);
    console.log(jsonString); // Output: {"name":"John Doe","age":30,"profession":"Developer"}

    For a more advanced use case, employing a replacer function allows specific properties to be included. For example, to exclude the age property:

    const jsonStringFiltered = JSON.stringify(user, (key, value) => {
      if (key === "age") return undefined;
      return value;
    });
    console.log(jsonStringFiltered); // Output: {"name":"John Doe","profession":"Developer"}

    Furthermore, using the space parameter for formatted output, you can enhance readability:

    const jsonStringFormatted = JSON.stringify(user, null, 2);
    console.log(jsonStringFormatted);
    /* Output:
    {
      "name": "John Doe",
      "age": 30,
      "profession": "Developer"
    }
    */

    Common Pitfalls and How to Avoid Them

    While JSON.stringify is robust, there are some common pitfalls. One issue is the inability to convert objects with circular references, leading to a TypeError. To circumvent this, ensure your objects are free of circular references before serialization.

    Another limitation is that JSON.stringify does not serialize functions or special objects like Date. For example, converting a Date object results in a string representation rather than a JSON date. Handling this requires custom serialization logic, such as converting dates to ISO strings manually:

    const data = {
      event: "Meeting",
      date: new Date().toISOString()
    };
    const jsonStringWithDate = JSON.stringify(data);
    console.log(jsonStringWithDate); // Output: {"event":"Meeting","date":"2023-10-15T12:00:00.000Z"}

    By understanding JSON.stringify and its intricacies, developers can effectively manage data serialization, crucial for building efficient and reliable web applications.

  • Exploring WebGL Fluid Simulation for Web Projects

    Exploring WebGL Fluid Simulation for Web Projects

    WebGL fluid simulation is transforming how web developers create interactive and visually dynamic web projects. By leveraging the power of WebGL—a JavaScript API for rendering 2D and 3D graphics within any compatible web browser—developers can design engaging experiences that captivate users. This article explores the concept of WebGL fluid simulation, guides you on how to implement it, showcases practical examples, and highlights its benefits.

    What is WebGL Fluid Simulation?

    WebGL fluid simulation is a technique used to mimic the behavior of fluids, such as water or smoke, within a web environment. It harnesses the computational power of the user’s GPU through WebGL to render complex fluid dynamics in real-time. This simulation involves solving mathematical equations that describe fluid motion, providing a realistic depiction of fluid behaviors.

    At its core, WebGL fluid simulation involves particle systems, shaders, and physics calculations. Developers use these elements to simulate properties like viscosity, density, and turbulence, creating an interactive visual experience that mimics real-world fluid behaviors.

    How to Implement WebGL Fluid Simulation in Your Project

    Implementing WebGL fluid simulation can be an enriching process. Start by familiarizing yourself with the basics of HTML5 and JavaScript, as these technologies are fundamental to working with WebGL. Here’s a concise guide to get you started:

    1. Set Up the Environment: Ensure that your development environment supports WebGL. Modern browsers like Chrome, Firefox, and Safari are typically compatible.
    2. Leverage Libraries: Use libraries such as Three.js or Babylon.js to simplify WebGL programming. These libraries offer abstraction layers, making it easier to handle complex graphics tasks.
    3. Define Shaders: Write vertex and fragment shaders to determine how each pixel is rendered. Shaders are crucial for defining the appearance and behavior of your fluid simulation.
    4. Integrate Physics: Incorporate physics engines like Ammo.js to simulate fluid dynamics. This step involves setting parameters for fluid viscosity, density, and other characteristics.
    5. Optimize Performance: Fluid simulations can be computationally intensive. Optimize your code by reducing the number of particles or using level of detail (LOD) techniques to maintain performance.
    6. Test and Iterate: Continuously test your simulation across different devices and browsers to ensure compatibility and refine the user experience.

    Practical Examples of WebGL Fluid Simulation

    WebGL fluid simulation is widely used in various web projects to enhance interactivity and visual appeal. Here are a few practical examples:

    • Interactive Art Installations: Artists use WebGL fluid simulations to create immersive online art experiences, allowing viewers to interact with flowing digital paint or smoke.
    • Game Development: Developers incorporate fluid simulations in games to simulate realistic water, lava, or magical effects, enhancing the gaming experience.
    • Educational Tools: Educators use fluid simulations to demonstrate scientific concepts such as fluid dynamics and thermodynamics, making learning more engaging.
    • Virtual Product Demos: Companies showcase products that interact with fluids, like waterproof electronics, by using fluid simulations to demonstrate function and design.

    Benefits of Using WebGL Fluid Simulation

    Integrating WebGL fluid simulation into web projects offers numerous benefits:

    • Enhanced Interactivity: Fluid simulations allow users to interact with digital content in a more dynamic and responsive way, boosting engagement.
    • Visual Appeal: The realistic depiction of fluid motion creates visually stunning effects that can capture and retain user attention.
    • Cross-Platform Compatibility: Since WebGL is supported by most modern browsers, fluid simulations can run on a variety of devices without additional software installations.
    • Resource Efficiency: Leveraging the GPU for rendering allows for efficient use of computational resources, enabling complex simulations without overloading the CPU.

    By exploring the possibilities of WebGL fluid simulation, developers can create innovative web experiences that push the boundaries of interactivity and visual design.

  • Semantic HTML: Give Your Page a Structure People Can Navigate

    Semantic HTML: Give Your Page a Structure People Can Navigate

    Start by identifying the main content, navigation, and page heading before choosing containers. HTML with meaningful structure gives browsers and assistive technology clues about what each part does. HTML5’s structural tags let you express those roles directly in the markup.

    What the markup communicates

    What is semantic markup? It is markup that describes the purpose of content through the elements chosen for it. A <nav> identifies a navigation region; a <button> identifies an action. A generic <div> can group either one, but its tag alone does not say what the group is for.

    Semantic HTML gives the same source document a structure that different tools can interpret. A browser can apply familiar behavior to a button, while a screen reader can expose a navigation landmark. CSS can still control how those elements look. The meaning comes from the element and its context, not from the size or color of its text. In HTML, meaningful markup lets that structure travel with the content. HTML markup with meaning helps a browser distinguish a list from unrelated lines of text.

    When choosing semantic elements, HTML offers several levels of specificity. Use <p> for a paragraph, <ul> and <li> for a list, and an <a> with an href for a link to a destination. Use a button for an action such as opening a menu. These choices help users recognize and operate the interface with the controls they expect.

    HTML5 semantic elements in a small page

    Consider a site with a guide to growing herbs. Its major regions can be expressed like this:

    <body>
      <a href="#main-content">Skip to content</a>
      <header>
        <a href="/">Garden Notes</a>
        <nav aria-label="Primary">
          <a href="/guides">Guides</a>
          <a href="/about">About</a>
        </nav>
      </header>
      <main id="main-content">
        <article>
          <h1>Growing basil indoors</h1>
          <p>Give basil a sunny window and well-drained soil.</p>
          <h2>Choose a container</h2>
          <p>Use a pot with drainage holes.</p>
          <h2>Care for the plant</h2>
          <h3>Watering</h3>
          <p>Water when the top of the soil feels dry.</p>
        </article>
        <aside aria-labelledby="related-heading">
          <h2 id="related-heading">Related guide</h2>
          <a href="/mint">Growing mint</a>
        </aside>
      </main>
      <footer><p>Garden Notes</p></footer>
    </body>
    

    The page-level header contains the site identity and primary navigation. The main region holds this page’s unique content; the article is a self-contained guide, and the aside offers related material. The footer closes the page with site information. The skip link gives keyboard users a direct route past repeated navigation to the main content.

    These HTML5 semantic elements convey different jobs. If a page has two navigation regions, give them distinct accessible labels, such as “Primary” and “Footer,” so a landmark list makes sense. A single navigation region does not need a label just to repeat its role. The W3C page regions guide explains how these regions are exposed and why context matters.

    Build a heading path

    Read the example’s headings as a table of contents: “Growing basil indoors” is the page topic, the two h2 headings divide it into subjects, and “Watering” is part of the care section. Heading levels describe relationships; use CSS, rather than a different heading level, to change visual size.

    This meaningful structure in HTML also helps someone navigating by headings jump to the desired part without listening to every paragraph. The MDN guide to headings recommends logical levels and explains how assistive technologies use them. Give headings descriptive text and avoid skipping from h2 to h4 merely for styling.

    This is one practical answer to what semantic markup is: the source tells a reader’s tools that “Watering” is a subsection, not just bold text. The meaning of the markup remains understandable even when styles are changed or removed. HTML’s meaningful markup also gives a developer a clearer map when updating the guide months later. For instance, meaningful HTML markup identifies a list, and a screen reader can announce how many items it contains.

    Choose by purpose, then add styling

    Suppose the same page used <div class="nav"> for its navigation and <div class="main"> for its content. Those class names can guide CSS, but they do not automatically create navigation and main landmarks. Replacing the wrappers with <nav> and <main> makes those roles available through native HTML. You can keep classes on the new elements for styling.

    HTML5 structural tags express the purpose of regions; generic containers remain useful too. A generic container still has a job: group cards into a grid, wrap an icon and label, or provide a styling hook when no more specific element fits. For example, choose <section> for a thematic grouping, usually with a heading, and <article> for content that could stand on its own. A layout wrapper does not need to become a section just because it encloses several children. HTML5 page landmarks work best when their purpose matches the content, not the visual layout.

    This distinction makes semantic HTML a design decision, not a rule to remove every <div>. Start with the content’s purpose, then choose a tag and style it. The MDN document-structure guide describes these choices in more detail.

    Know what structure can and cannot do

    Semantically meaningful HTML provides useful defaults, but it cannot supply missing content or repair broken behavior. A button still needs an understandable name; an image conveying information needs appropriate alternative text; a menu opened by a button must be operable and expose its state. Test the actual interaction with a keyboard and screen reader rather than judging it from the tags alone.

    Similarly, HTML5’s elements for page structure do not all become landmarks in every context. A top-level <header> can represent the page banner, while a header inside an article describes that article and is not the page banner. A named <section> may become a region landmark; creating a landmark for every small group can make navigation noisy. W3C’s landmark guidance explains how to keep regions meaningful.

    A quick page check

    Before shipping, inspect your page in this order:

    1. Find the unique content and place it in one visible <main>; identify major navigation and page-level header and footer.
    2. Read the headings in order. Confirm that each level reflects the relationship between topics and that the wording identifies the content below it.
    3. Inspect links, buttons, images, and forms for meaningful names and appropriate native elements. Try every control with a keyboard.
    4. Open a screen reader’s landmark and heading lists. Check that the names and sequence help you reach the intended content; then test the page itself.

    Treat semantic HTML as a map to maintain alongside the visible design. When the page changes, update the map so its signposts still lead to the right places.

  • JavaScript Latest Version: What the Standard Means for Your Code

    JavaScript Latest Version: What the Standard Means for Your Code

    As of November 2026, the latest version of JavaScript’s underlying language standard is ECMAScript 2026, the 17th edition of ECMA-262. Ecma approved it on June 30, 2026. JavaScript’s present standard edition describes what implementations should do; whether your browser or Node.js runtime supports a particular feature is a separate question.

    Current JavaScript version and the published standard

    The Ecma International publication page identifies ECMAScript 2026 as the 17th edition and provides its normative HTML text. The approval announcement records the June 30 decision. ECMAScript is the language specified by ECMA-262; JavaScript is the familiar name for implementations used in browsers and other environments.

    The latest JavaScript version in the sense of the published language specification is therefore ES2026. You may also see “ES2026,” “ECMAScript 2026,” or “ECMA-262, 17th edition” used for this same annual snapshot. The latest ECMAScript edition follows ECMAScript 2025, the 16th edition. The numbering describes editions of a specification, not a download that upgrades every installation at once.

    A current JavaScript version in a runtime is a less precise idea: a particular engine can implement some features from one edition and others from later work. The current version of JavaScript, as defined in ECMA-262, gives you a consistent reference for language behavior, while your actual deployment targets determine what code can run there today.

    A standard is not an engine

    An ECMAScript edition defines language syntax, built-in objects, and their behavior. JavaScript, latest version included, needs an implementation to execute code. Browser engines include V8 in Chrome, SpiderMonkey in Firefox, and JavaScriptCore in Safari. Node.js also uses V8, but it is a runtime with its own release cycle and APIs.

    For example, Array.prototype.map belongs to the language’s built-in capabilities, while document.querySelector is a browser DOM API. Node.js provides APIs such as node:fs for server-side work. A language edition alone does not tell you whether the DOM or a Node-specific module exists in your environment. Check the host API separately from the language feature.

    The current ECMAScript edition is a useful reference when reading what a feature is supposed to do. But implementation work arrives feature by feature. A browser may ship a feature ahead of formal publication, and an older browser may never receive it. A Node release embeds a particular V8 build and may differ from a browser release even though both use that engine. Check the exact targets rather than translating a year into a universal compatibility promise.

    Published editions and proposals

    TC39 develops changes through a proposal process. The finished proposals list identifies Stage 4 proposals and their expected publication years. Reaching that stage means the work is finished for the process and is, or soon will be, in the draft; the expected year still matters when deciding which annual snapshot contains it.

    The TC39 working draft can include finished proposals intended for the next annual snapshot. That makes the draft valuable for following development, but a feature visible there is not automatically part of the newest published ECMAScript edition. Check the current edition of ECMA-262 itself when you need to establish the status of a feature. A proposal at an earlier stage may change, and an experimental implementation does not settle its final form.

    For instance, TC39’s finished list places Temporal in the expected 2027 publication year. A runtime may offer it, but that alone does not make it an ES2026 feature. Record both the proposal’s status and the particular engine’s support before relying on it.

    Check a feature in practice

    Suppose you want to use RegExp.escape to turn user-supplied text into a literal part of a regular expression. The published specification identifies it as an ES2025 addition. Its presence in the standard is useful context; support in the browsers and Node versions you actually deploy is the deciding factor.

    Start with the MDN reference and compatibility table, then compare the listed versions with your supported browser matrix. In Node, run node --version and node -p "process.versions.v8" in the same environment that runs your application. Node’s process documentation describes those version properties. A local laptop’s result may differ from a production container’s.

    For a quick runtime check, evaluate:

    console.log(typeof RegExp.escape === "function");
    

    A true result shows that a function is present in that environment. Follow it with a small behavior test using representative input, including punctuation, and run your application tests on each supported target. Feature detection for a method does not prove that every edge case behaves correctly. Record the result alongside the exact runtime version so another developer can reproduce the check later.

    The JavaScript version currently in use is only one part of that investigation. JavaScript, latest version or earlier, can run in environments with different host APIs and engine builds. When a target lacks a method, consider a maintained polyfill that implements the required behavior, or choose an alternative compatible with your support policy. Test the fallback as well as the native path. For newer syntax, an older engine may fail to parse the file before a feature check executes; a build step can transform supported syntax for older targets, but cannot automatically supply every missing API.

    Choose your next check

    Use the newest JavaScript version as a standard to understand the language contract, and use compatibility data and tests to decide what to ship. The currently published ECMAScript specification tells you which rules to consult; your deployed runtime tells you which rules it implements.

    Pick one feature your project needs. List the oldest browser and Node versions you support, check that feature’s compatibility for each, then run a focused test in those actual environments. If one target fails, decide whether to update the target, provide a tested fallback, or use another approach.