Category: Data & Systems

  • Understanding the Flood Fill Algorithm

    Understanding the Flood Fill Algorithm

    The flood fill algorithm is a fundamental concept in computer graphics and image processing. It serves as the backbone for operations that require region filling, such as painting tools in graphic editors and game development. By understanding this algorithm, programmers and developers can effectively manipulate images and design interactive applications.

    What is the Flood Fill Algorithm?

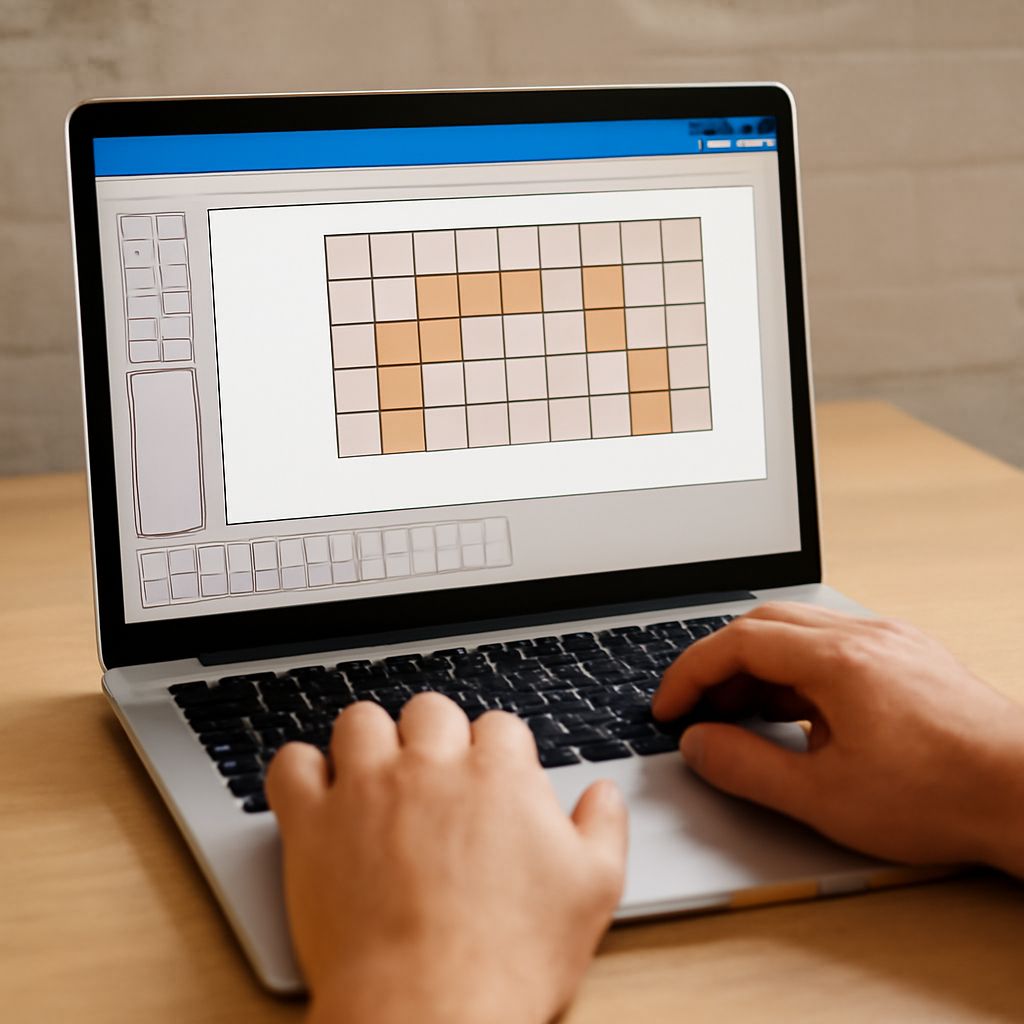
    The flood fill algorithm is a method used to determine and fill contiguous areas of a grid or matrix. It identifies connected pixels or nodes that share the same set of attributes, such as color. Essentially, this algorithm is responsible for changing the attribute of a target area to a new value, uniformly.

    Flood fill is often invoked when there is a need to alter the appearance of a region in an image or to detect boundaries. In simpler terms, it’s what happens when you use a paint bucket tool in a digital painting application to change the color of a whole area.

    How Does the Flood Fill Algorithm Work?

    The workings of the flood fill algorithm can be visualized with a simple analogy: think of it as filling an enclosed area with water. Starting from a seed point, the algorithm spreads to adjacent areas in all possible directions (up, down, left, and right) until it covers the entire connected region.

    There are two main approaches for implementing flood fill:

    • Recursive Approach: This method uses recursion to navigate and fill the grid. It can be easier to implement but may lead to stack overflow issues with large datasets due to deep recursive calls.
    • Iterative Approach: Utilizes a queue or stack to manage the pixels or nodes to visit. This method is more memory-efficient and better handles larger areas without risk of overflow.

    Applications of the Flood Fill Algorithm

    The flood fill algorithm shines in several applications, primarily in the realms of computer graphics and image processing:

    • Paint and Drawing Programs: Used in tools like the paint bucket to fill areas with a specific color.
    • Game Development: Assists in map generation and terrain analysis by filling areas to identify distinct regions or patterns.
    • Image Segmentation: Plays a critical role in dividing an image into regions for analysis or object recognition tasks.
    • Pattern Recognition: Facilitates the identification and isolation of specific patterns in a dataset.

    Implementing the Flood Fill Algorithm

    To implement the flood fill algorithm, the following steps can be followed using either the recursive or iterative method:

    1. Identify the starting point or seed pixel.
    2. Check if the starting pixel is already the target color. If it is, terminate the process.
    3. Use a stack (for iterative) or recursive calls to explore all connected neighbors of the same initial color.
    4. Change the color or attribute of the current pixel or node to the desired new color.
    5. Repeat the process for each neighboring pixel until the entire region is filled.

    Here is a simple pseudo-code for the iterative approach:

    
    function floodFill(image, x, y, newColor):
        initialColor = image[x][y]
        if initialColor == newColor:
            return
        stack = [(x, y)]
        while stack is not empty:
            currentX, currentY = stack.pop()
            if image[currentX][currentY] == initialColor:
                image[currentX][currentY] = newColor
                for each (neighborX, neighborY) in neighbors(currentX, currentY):
                    stack.push((neighborX, neighborY))


    This pseudo-code provides a starting point, ensuring that the flood fill algorithm works efficiently across varied applications. By adapting the flood fill algorithm to suit specific needs, developers can harness its power for numerous tasks in graphics and beyond.
  • Understanding Forward Chaining in Algorithms

    Understanding Forward Chaining in Algorithms

    Forward chaining is a method used in rule-based systems and expert systems to derive conclusions from a set of known facts. It is a data-driven approach that starts with the available data and uses inference rules to extract more data until a goal is reached. This approach is often utilized in artificial intelligence for applications such as automated reasoning and decision-making. In contrast, backward chaining starts with a goal and works backward to determine the facts that support it.

    What is Forward Chaining?

    Forward chaining operates by applying inference rules to known facts to generate new information. The process continues until a specific goal is achieved or no more rules can be applied. It is particularly effective in scenarios where all data is available at the outset, and the goal is to explore the entire implication of that data.

    In the context of algorithms, forward chaining evaluates each rule in sequence. If the conditions of a rule are satisfied by the current data, the rule is triggered, and its consequent is added to the set of known data. This continues iteratively, expanding the set of facts, until the system arrives at a conclusion or exhausts all possibilities.

    Applications of Forward Chaining

    Forward chaining is widely applied in various domains. In artificial intelligence, it is used within expert systems to simulate the decision-making ability of a human expert. For example, in medical diagnosis systems, forward chaining can help determine a diagnosis by applying medical knowledge rules to patient data.

    Other applications include automated control systems where forward chaining is used to decide on actions based on sensory data. Additionally, it finds use in data verification processes, where the method aids in ensuring that data conforms to established rules and standards before being processed further.

    Forward Chaining vs. Backward Chaining

    The primary difference between forward chaining and backward chaining lies in their approach to reaching conclusions. Forward chaining is data-driven, beginning with known facts and applying rules to extract further information. It is advantageous in situations where complete data is present and the goal is to explore the comprehensive implications of that data.

    In contrast, backward chaining is goal-driven. It starts with a hypothesis or a goal and works backward, asking what conditions must be met for the goal to be true. This method is typically used in diagnostic systems where the end goal is known, and the task is to ascertain the conditions or factors that lead to that goal.

    Each method has its strengths depending on the context. Forward chaining is suitable for systems needing to process a large amount of available data to reach various conclusions. Backward chaining is more efficient for problems where the objective is clearly defined, and the main task is to find supporting evidence or conditions.

    Ultimately, the choice between forward chaining and backward chaining depends on the specific requirements of the system being designed and the nature of the problem at hand.

  • Understanding ORA-00904: Invalid Identifier Error in SQL

    Understanding ORA-00904: Invalid Identifier Error in SQL

    The ORA-00904: invalid identifier error in SQL is a common stumbling block for database developers working with Oracle databases. This error arises when an SQL statement refers to an invalid column name or identifier. Understanding the causes and solutions for this error is crucial for ensuring smooth database operations.

    What is ORA-00904: Invalid Identifier?

    The ORA-00904 error signifies that an SQL query is attempting to access a column or identifier that does not exist, or is improperly named in the database schema. This error commonly occurs when there is a typo in the column name, or when the column does not exist in the table. The error message typically specifies which identifier is invalid, helping to narrow down the issue.

    Common Causes of ORA-00904 Error

    Several factors can lead to the ORA-00904 error. Understanding these can help in diagnosing and resolving the issue quickly:

    • Typographical Errors: A simple typo in the column name, such as a missing or extra character, can trigger the ORA-00904 error.
    • Case Sensitivity: Oracle databases are case-sensitive by default. If the column name in the query does not match the case of the column name in the database, this error may occur.
    • Incorrect Quotation Marks: Using incorrect quotation marks around identifier names can lead to this error. For example, using single quotes instead of double quotes for identifiers.
    • Non-Existent Columns: Attempting to access a column that does not exist in the specified table will result in this error.
    • Reserved Words: Using SQL reserved words as column names without proper handling (such as using double quotes) can cause the ORA-00904 error.

    How to Fix ORA-00904: Invalid Identifier

    Resolving the ORA-00904 error involves checking the SQL query and database schema for errors. Here’s how you can fix it:

    • Verify Column Names: Double-check the spelling and case of the column names in your query against the database schema. Ensuring they match exactly is crucial.
    • Correct Quotation Usage: Use double quotes for identifiers if they are case-sensitive or contain special characters. For example, write "EmployeeName" instead of 'EmployeeName'.
    • Check for Reserved Words: If you are using a reserved word as an identifier, ensure it is enclosed in double quotes.
    • Ensure Column Existence: Verify that all referenced columns exist within the specified tables. You can use SQL developer tools or queries to list the columns of a table.
    • Update Database Schema: If necessary, update the database schema to include the missing columns.

    Preventing ORA-00904 Errors in Your SQL Code

    Preventing ORA-00904 errors requires a proactive approach to SQL coding and database management:

    • Use Consistent Naming Conventions: Adopting a consistent naming convention for columns and tables can reduce the risk of typographical errors.
    • Leverage SQL Development Tools: Use tools like SQL Developer or Toad that offer syntax highlighting and auto-complete features to minimize errors in your SQL code.
    • Regularly Review Database Schemas: Keep your database documentation up-to-date and periodically review it to ensure schema integrity.
    • Implement Thorough Testing: Test SQL queries in a development environment before deployment to production to catch errors early.
    • Educate Team Members: Train team members on common SQL pitfalls and how to avoid them, ensuring everyone is aware of best practices.

    By understanding and applying these solutions, you can effectively manage and prevent ORA-00904: invalid identifier errors in your SQL databases, leading to more efficient and error-free database operations.

  • Understanding the OR Symbol in Binary Logic

    Understanding the OR Symbol in Binary Logic

    In the realm of binary logic, the OR symbol plays a crucial role in facilitating decision-making processes within digital systems. This symbol, often represented by a plus sign (+) or a vertical line (|), is integral to understanding how data is processed in computer systems. By examining the OR symbol’s function, one can gain insight into its applications in logic gates and its impact on computing technologies.

    What is the OR Symbol in Binary Logic?

    The OR symbol is a fundamental operator in binary logic used to perform logical disjunctions. In its simplest form, the OR operation takes two binary inputs and yields a true result if at least one of the inputs is true. Represented in binary terms, this means that for inputs A and B, the OR operation outputs a 1 if either A, B, or both are 1. This property makes the OR operator essential in various logic operations, especially in the design and functioning of computer processors and digital circuits.

    How Does the OR Symbol Work in Logic Gates?

    Logic gates are the building blocks of digital circuits, and the OR gate is one of the most fundamental among them. The OR gate functions by outputting a high signal (1) when one or more of its inputs are high. For instance, if an OR gate receives input signals of 0 and 1, it will output a 1, illustrating how the OR operation reflects flexibility in computing operations.

    OR gates are crucial in creating more complex logic circuits, serving as essential components in arithmetic logic units (ALUs) and various digital systems. Their ability to combine multiple conditions into a single logical output makes them invaluable in computational processes, playing a pivotal role in executing logical operations efficiently. By integrating OR gates with other types of gates, such as AND and NOT gates, more intricate operations can be performed, enabling advanced computing functionalities.

    Applications of the OR Sign in Computer Systems

    The OR sign finds numerous applications in computer systems, contributing significantly to their operational efficiency and logic processing capabilities. One common application is in condition checking within programming, where the OR operation determines the truth of compound conditions. This is particularly useful in decision-making processes where multiple conditions may lead to the same outcome.

    In digital electronics, the OR symbol is used in multiplexers, which select data from multiple inputs to a single output line. This capability is crucial in data routing and processing tasks, allowing for more flexible and efficient data management.

    Furthermore, OR operations are extensively utilized in network routing algorithms, where the determination of optimal paths often depends on multi-condition evaluations. The ability to simplify these evaluations into a single logical operation enhances both the speed and accuracy of network communications.

    Overall, the OR symbol and its associated logic operations form the backbone of modern computing, underscoring the importance of understanding its functionality and applications in digital systems. The OR symbol’s simplicity yet powerful application in decision-making processes serves as a cornerstone in the development and evolution of technology.

  • Mastering Python GroupBy for Data Analysis

    Mastering Python GroupBy for Data Analysis

    The Python GroupBy function is a powerful tool in the realm of data analysis, enabling users to segment and summarize data efficiently. Whether you are working with large datasets or need to perform complex operations, mastering GroupBy can significantly enhance your data processing capabilities. This article will guide you through using Python’s GroupBy with practical insights into df.groupby and pd groupby, along with optimization tips.

    What is the Python GroupBy Function?

    Python GroupBy is a method in the Pandas library that allows you to group data based on certain criteria. This function is essential for performing split-apply-combine operations on datasets. When you apply GroupBy, the data is divided into groups based on values of specific keys. Subsequently, you can apply functions to each group, transforming the data into a more meaningful form.

    GroupBy operations can greatly simplify statistical analysis tasks, such as calculating mean, sum, or other aggregations based on groupings. Whether you are filtering, aggregating, or pivoting data, Python GroupBy provides a streamlined approach to managing this process.

    How to Use df.groupby in Pandas?

    The df.groupby function is a cornerstone of data manipulation in Pandas. To utilize this function, first import Pandas and read your dataset into a DataFrame:

    import pandas as pd
    df = pd.read_csv('your_dataset.csv')

    You can then group data using df.groupby(). Here’s a basic example of grouping:

    grouped = df.groupby('column_name')

    This command groups the DataFrame by the values in ‘column_name’. Once grouped, you can apply aggregation functions like mean(), sum(), or count() to the grouped object:

    grouped_agg = grouped.mean()

    This flexibility allows you to derive insights from your data efficiently. By using df.groupby, complex data operations become manageable, enabling you to focus on analyzing the results.

    Practical Examples with pd GroupBy

    To illustrate pd groupby in action, consider a DataFrame containing sales data:

    data = {'Product': ['A', 'B', 'A', 'B'],
            'Sales': [100, 200, 150, 250],
            'Region': ['North', 'South', 'South', 'North']}
    df = pd.DataFrame(data)

    You can group this data by ‘Product’ and calculate the total sales per product:

    product_sales = df.groupby('Product')['Sales'].sum()

    This operation will output the total sales for each product, providing valuable insights into sales performance. Similarly, you can group by ‘Region’ to analyze sales trends across different regions:

    region_sales = df.groupby('Region')['Sales'].sum()

    These examples demonstrate how pd groupby can be leveraged to perform targeted analysis on datasets, extracting specific insights that drive business decisions.

    Tips for Optimizing GroupBy Operations

    While GroupBy is a powerful feature, optimizing its usage can help in managing large datasets more efficiently. Here are some tips:

    • Pre-processing Data: Clean and format your data before applying GroupBy. This can include handling missing values or converting data types.
    • Using Aggregation Functions: Apply aggregation functions directly after grouping to reduce the memory footprint and processing time.
    • Column Selection: Limit the number of columns you group by to streamline operations and reduce complexity.
    • Leveraging MultiIndex: When dealing with hierarchical data, use MultiIndex to structure your DataFrame effectively.

    By following these tips, you can ensure that your GroupBy operations are not only effective but also efficient, optimizing both performance and resource usage in your data analysis tasks.

  • Understanding SQL WITH Clauses

    Understanding SQL WITH Clauses

    The SQL WITH clause, also known as a Common Table Expression (CTE), is a powerful SQL feature that allows for improved organization and readability of complex queries. It enables the creation of temporary result sets that can be referenced within a SELECT, INSERT, UPDATE, or DELETE statement. By using the WITH clause, SQL developers can simplify their code, making it easier to manage and understand.

    What is a SQL WITH Clause?

    The SQL WITH clause is essentially a temporary named result set that exists only during the execution of a query. Unlike traditional subqueries, CTEs are defined at the beginning of a query and can be referenced multiple times within the main SQL statement. This feature is particularly useful for breaking down large queries into more manageable sections, simplifying debugging and maintenance.

    How to Use WITH AS in SQL

    To use the WITH clause in SQL, you start by defining the CTE with the keyword WITH, followed by the name of the CTE and the AS keyword. Inside parentheses, you define the query that generates the result set for the CTE. This CTE can then be referenced as if it were a table or view in the main query. Here is a simple syntax example:

    WITH cte_name AS (
      SELECT column1, column2
      FROM table_name
      WHERE condition
    )
    SELECT column1, column2
    FROM cte_name;

    In this example, cte_name is a CTE that extracts column1 and column2 from table_name based on a specified condition. The main query then selects data from cte_name.

    Benefits of Using SQL WITH Clauses

    There are several advantages to using SQL WITH clauses:

    • Improved Readability: By breaking down complex queries into smaller, named components, CTEs make SQL statements easier to read and understand.
    • Reusability: A CTE can be referenced multiple times within the same query, reducing redundancy and potential errors.
    • Modularity: CTEs promote a modular approach to query building, allowing developers to isolate specific parts of the query logic.
    • Debugging Ease: Since CTEs can be individually tested and modified, they simplify the process of diagnosing and fixing errors within complex queries.
    • Recursion Support: Recursive CTEs enable complex hierarchical data retrieval, such as organizational charts or file systems, straightforwardly.

    Examples of SQL WITH Clauses in Practice

    Consider a scenario where you need to calculate sales growth between two years for different products. Using a CTE, you can simplify the task:

    WITH sales_cte AS (
      SELECT product_id, year, SUM(sales) AS total_sales
      FROM sales_data
      GROUP BY product_id, year
    )
    SELECT a.product_id, 
           a.total_sales - b.total_sales AS sales_growth
    FROM sales_cte a
    JOIN sales_cte b ON a.product_id = b.product_id
    WHERE a.year = 2023 AND b.year = 2022;

    In this example, the CTE sales_cte aggregates sales data by product and year. The main query then calculates the sales growth by joining the CTE on product IDs and comparing sales between 2022 and 2023.

    By using the SQL WITH clause, developers can create organized, efficient, and easily maintainable SQL queries that improve overall code quality and reduce the complexity associated with large datasets.

  • Understanding Heapify and Priority Queue in Python

    Understanding Heapify and Priority Queue in Python

    Heapify is a crucial concept in Python programming, especially when dealing with heap data structures. It enables efficient management of priority queues, a type of data structure that allows elements to be processed based on priority levels. Python offers robust libraries that facilitate the implementation of heapify and priority queues, making it easier for developers to manage tasks where order is paramount.

    What is Heapify in Python?

    In Python, heapify is a function provided by the heapq module that converts a list into a binary heap. A binary heap is a tree-like data structure, where each parent node is ordered with respect to its children according to a specific heap property: min-heap or max-heap. In a min-heap, the parent node is always smaller than the child nodes, while in a max-heap, the parent node is larger.

    Heapify helps maintain the heap property after changes like insertion or deletion of elements. The heapq.heapify(list) function mutates an existing list into a heap in-place, providing an efficient way to prepare a list for operations that require priority ordering.

    How to Implement a Priority Queue in Python

    A priority queue in Python can be implemented using the heapq module. This module provides a set of functions to manipulate heaps, enabling priority-based task management. Here’s a straightforward way to implement a priority queue:

    • Import the heapq module: import heapq.
    • Create an empty list that will serve as the priority queue.
    • Use heapq.heappush(queue, item) to add elements. This function maintains the heap property by inserting the new item at the correct position.
    • Retrieve the highest-priority element using heapq.heappop(queue), which removes and returns the smallest item.

    Here’s an example:

    
    import heapq
    
    priority_queue = []
    heapq.heappush(priority_queue, (2, 'Task 2'))
    heapq.heappush(priority_queue, (1, 'Task 1'))
    heapq.heappush(priority_queue, (3, 'Task 3'))
    
    while priority_queue:
        print(heapq.heappop(priority_queue))
    

    In this example, the tasks are processed in order of priority, determined by the integer values. Task 1 is processed first because it has the highest priority (smallest number).

    Common Use Cases for Heapify and Priority Queues

    Heapify and priority queues are utilized in various scenarios where task ordering is essential. Here are some common use cases:

    • Task Scheduling: Priority queues help in scheduling tasks based on urgency or importance, ensuring critical tasks are executed first.
    • Event Management: In simulations or real-time systems, events can be managed efficiently using priority queues to handle occurrences based on their scheduled times.
    • Dijkstra’s Algorithm: This shortest path algorithm uses priority queues to efficiently select the next node to process.
    • Pathfinding Algorithms: Algorithms like A* require efficient state management, which is facilitated by priority queues.

    Understanding heapify and priority queues in Python empowers developers to implement efficient data structures for complex scenarios requiring ordered processing. Utilizing the heapq module, programmers can streamline their code to handle tasks efficiently and with minimal overhead.

  • How to Use the SQL INSERT INTO Statement

    How to Use the SQL INSERT INTO Statement

    The SQL INSERT INTO statement is a critical component of SQL database management that allows users to add new data entries into a table. This function is fundamental for updating databases with fresh data, ensuring that information is both current and accurate. Mastering the use of the INSERT statement in SQL not only enhances your database management skills but also allows for efficient data manipulation.

    What is the SQL INSERT INTO Statement?

    The SQL INSERT INTO statement is used to insert new rows of data into a table. It specifies the target table and the data values to be inserted. This is critical in a relational database for adding new records that facilitate data tracking and manipulation. The statement can be utilized for single-row or multiple-row insertion, depending on the needs of the database transaction.

    How to Write an INSERT INTO Statement

    To construct an INSERT INTO statement, you begin by specifying the table into which you want to insert data. Then, you list the columns for which you are providing values, followed by the actual values to be inserted. Here’s a basic syntax:

    
    INSERT INTO table_name (column1, column2, column3, ...)
    VALUES (value1, value2, value3, ...);
    

    For example, if you want to insert a new record into a table named employees, with columns first_name, last_name, and email, the statement would look like this:

    
    INSERT INTO employees (first_name, last_name, email)
    VALUES ('John', 'Doe', '[email protected]');
    

    Note that the data types of the values must match the data types defined in the table schema for each column.

    Common INSERT INTO Statement Examples

    The INSERT query in SQL offers flexibility to handle various data insertion scenarios:

    • Basic Single Row Insert: Adds one row at a time, as shown in the earlier example.
    • Multiple Rows Insert: To insert multiple rows with a single query, use a comma to separate the value sets:
    
    INSERT INTO employees (first_name, last_name, email)
    VALUES 
    ('Jane', 'Smith', '[email protected]'),
    ('Robert', 'Brown', '[email protected]');
    
    • Insert Based on a Subquery: You can populate a table with the results of a query:
    
    INSERT INTO employees (first_name, last_name, email)
    SELECT first_name, last_name, email FROM temp_employees;
    

    This is particularly useful when transferring data between tables.

    Troubleshooting Common Errors

    While using the INSERT INTO statement, users may encounter some common errors:

    • Data Type Mismatch: Ensure that the data types of the values you are inserting match those defined in the table schema.
    • Missing Values for NOT NULL Columns: If a column is set to NOT NULL, ensure you provide a value for it in the INSERT statement.
    • Violating Unique Constraints: Check for unique constraints in your table that might prevent duplicate data entries.

    Address these errors by verifying your data types, ensuring no required fields are left empty, and respecting table constraints such as unique keys.

  • Understanding Different Sorting Algorithms

    Understanding Different Sorting Algorithms

    Sorting algorithms are vital tools in computer science that arrange data in a specific order, often numerical or lexicographical. These algorithms are fundamental in optimizing the performance of other algorithms that require sorted data to function efficiently. By organizing information, sorting algorithms make data processing tasks more manageable and improve the speed of data retrieval.

    What Are Sorting Algorithms?

    Sorting algorithms are a set of instructions that arrange data in a particular sequence. These sequences can be ascending, descending, or according to a specific criterion. Sorting is crucial for various applications, including database management and search algorithms, as it enhances the efficiency of data handling and retrieval. Commonly, sorting operations are implemented in everyday computational tasks to ensure data is organized logically and can be accessed quickly. The performance of sorting algorithms is vital, as it often impacts the overall efficiency of software applications.

    Key Types of Sorting Algorithms

    There are several types of sorting algorithms, each with unique characteristics suited to different kinds of data and applications. The most common types include:

    • Bubble Sort: This simple algorithm repeatedly steps through the list to be sorted, compares adjacent elements, and swaps them if they are in the wrong order. It continues to pass through the list until no swaps are needed, indicating that the list is sorted.
    • Selection Sort: This algorithm divides the input list into two parts: a sorted sublist of items which is built up from left to right at the front of the list, and a sublist of the remaining unsorted items. It repeatedly selects the smallest (or largest) element from the unsorted sublist, swapping it with the leftmost unsorted element.
    • Insertion Sort: Similar to sorting playing cards in your hands, this algorithm builds the sorted array one item at a time. It takes each element from the unsorted list and inserts it into the correct position within the sorted list.
    • Merge Sort: A more complex algorithm, merge sort uses the divide-and-conquer technique. It splits the list into halves, recursively sorts each half, and then merges the sorted halves back together.
    • Quick Sort: Another divide-and-conquer algorithm, quick sort picks an element as a pivot and partitions the array into two sub-arrays. The sub-arrays are then sorted recursively.

    How Do Different Sorting Algorithms Work?

    Understanding how different sorting algorithms work helps in selecting the appropriate one for specific scenarios. Here’s a closer look at their mechanics and use cases:

    • Bubble Sort: Ideal for small datasets due to its simplicity. It works by repeatedly stepping through the list, comparing adjacent pairs of elements, and swapping them if they are in the wrong order. Despite its simplicity, bubble sort is inefficient on larger datasets, with a time complexity of O(n²).
    • Selection Sort: While it is inefficient for large lists (O(n²) time complexity), selection sort is better suited for situations where memory write operations are costly, as it minimizes writes.
    • Insertion Sort: Efficient for small datasets or lists that are already partially sorted. Its average and worst-case time complexity is O(n²), but it performs better than bubble sort in practice.
    • Merge Sort: Suitable for large datasets due to its O(n log n) time complexity. It is stable and efficient for linked lists and external sorting but requires additional space for the temporary arrays.
    • Quick Sort: Frequently used for its efficiency and speed, with an average time complexity of O(n log n). However, its worst-case complexity is O(n²), which can be mitigated by using optimizations like choosing a good pivot point.

    Choosing the right sorting algorithm depends on factors such as the size of the dataset, memory constraints, and whether the dataset is already partially sorted. Understanding these different sorting algorithms enables more efficient data processing and improved application performance.

  • Understanding the SQL Update Statement

    Understanding the SQL Update Statement

    The SQL Update Statement is a powerful tool for modifying existing records within a database table. It enables users to change field values based on specified conditions, making it essential for maintaining and manipulating data efficiently. Understanding the syntax and application of the SQL Update command is crucial for effective database management and ensuring data consistency.

    What is the SQL Update Statement?

    The SQL Update Statement is a Data Manipulation Language (DML) command used to alter existing records in a table. By specifying which records to modify, users can update one or more columns in a single execution. This versatility makes it a fundamental component of SQL queries in data management tasks.

    An example of the basic syntax for an SQL Update Statement is as follows:

    UPDATE table_name
    SET column1 = value1, column2 = value2, ...
    WHERE condition;

    In this example, table_name specifies the table to update. The SET clause determines the columns and their new values, while the WHERE clause indicates which rows should be updated. Without a WHERE clause, all records in the table will be updated, which is rarely the desired outcome.

    How to Use the Update Query in SQL

    Using the update query in SQL involves understanding its syntax and applying it to specific scenarios. To ensure accuracy, it is important to specify the correct table and target columns clearly. Here are the steps to using an update query effectively:

    1. Identify the table containing the data you want to update.
    2. Specify the new values for the columns using the SET clause.
    3. Determine which records should be updated using the WHERE clause.
    4. Execute the update query to apply changes.

    For example, to increase the salary of employees in the “employees” table by 10% for those in the “Sales” department, the following query would be used:

    UPDATE employees
    SET salary = salary * 1.10
    WHERE department = 'Sales';

    This query updates the salary column for all employees where the department is “Sales”.

    Examples of Updating a Table in SQL

    Let’s explore more examples to understand the diverse applications of the SQL Update command:

    • Updating a single column for specific records:
    • UPDATE products
      SET price = price * 0.9
      WHERE category = 'Electronics';
    • Changing multiple columns in a single update:
    • UPDATE customers
      SET email = '[email protected]', phone = '1234567890'
      WHERE customer_id = 5;
    • Updating all records in a table (exercise caution with this approach):
    • UPDATE employees
      SET status = 'Inactive';

    Best Practices for Using the SQL Update Command

    Effective use of the SQL Update command requires adherence to best practices to prevent unintended data modifications:

    • Always use the WHERE clause: To avoid updating all records unintentionally, ensure the WHERE clause is appropriately used to target specific rows.
    • Test queries on a backup: Before executing update queries on critical data, test them on a sample dataset or backup to verify the results.
    • Use transactions: For complex updates, wrap queries in transactions to allow rollback in case of errors.
    • Backup data regularly: Maintain regular backups to safeguard against accidental data loss or corruption during updates.

    By following these practices, users can efficiently manage and update table data while minimizing risks associated with data manipulation.