Category: Data & Systems

  • Sequential Search: How Linear Search Scans a Collection

    Sequential Search: How Linear Search Scans a Collection

    Sequential search scans a collection from left to right, comparing the target with one item at a time. It returns the index as soon as it finds a match. If it reaches the end without a match, it returns a not-found result such as -1.

    The method is useful when a collection is small, unsorted, or stored in a structure that does not support fast random lookup. Its running time depends on how many items the scan must compare.

    How Does Sequential Search Scan a Collection?

    Linear search begins at index 0 and examines each item in its existing order. For every position, it performs one equality comparison between the current item and the target.

    1. Start at the first item.
    2. Compare the current item with the target.
    3. If they match, stop and return the current index.
    4. If they do not match, move to the next item.
    5. If no items remain, return the not-found result.

    The scan stops early when the target appears near the beginning. It must inspect more of the collection when the target appears later or is absent. A sequential search does not rearrange the collection, so the order remains unchanged.

    Linear Search Example: Found and Not Found

    Consider this list, where indexes begin at zero:

    [14, 3, 27, 8, 19]

    To find 8, linear search makes these comparisons:

    1. Index 0: compare 14 with 8 — no match.
    2. Index 1: compare 3 with 8 — no match.
    3. Index 2: compare 27 with 8 — no match.
    4. Index 3: compare 8 with 8 — match.

    The search returns index 3 after four comparisons.

    To find 25, the search compares 25 with 14, 3, 27, 8, and 19. None matches, so the search returns -1 after five comparisons. This is a not-found result because every item was checked.

    If the target were 14, the first item would match immediately. That found case would require only one comparison.

    Linear Search Pseudocode: Return an Index or Not Found

    The following pseudocode returns the first matching index. It returns -1 when the target is missing, including when the collection is empty.

    linearSearch(items, target)

    1. For index from 0 through the last index in items:
    2. Compare items[index] with target.
    3. If they are equal, return index.
    4. After the loop finishes, return -1.

    Returning as soon as a match appears makes the result the first occurrence when duplicate values exist. For example, searching [5, 2, 5] for 5 returns index 0 rather than continuing to index 2.

    What Is Linear Search Time Complexity?

    Linear search time complexity describes how the number of comparisons grows with the collection size, represented by n.

    • Best case: O(1). The target is the first item, so the algorithm performs one comparison.
    • Average case: O(n). If a present target is equally likely to occur at any position, the scan makes an average of (n + 1) / 2 comparisons. This simplifies to O(n).
    • Worst case: O(n). The target is the final item or is not present, so the algorithm checks all n items.

    The exact comparison count follows the trace: position i requires i + 1 comparisons, while an absent target requires n. The algorithm uses O(1) auxiliary space because it stores only the current index and target-related variables; it does not create another collection.
  • Union-Find Algorithm: Path Compression and Union by Rank

    Union-Find Algorithm: Path Compression and Union by Rank

    The union-find algorithm maintains a changing collection of non-overlapping sets. Its core operations are make-set, which creates a singleton set; find, which returns a set’s representative; and union, which merges two sets. It supports connectivity tests without storing every member relationship explicitly.

    The same technique, called disjoint set union, represents each set with a parent forest. The implementation below starts with that forest, then adds path compression and union by rank so repeated operations stay near-constant in amortized time.

    How does the union-find algorithm represent sets?

    A set is a component: a group of elements connected through previous union operations. Each element is a node with one parent pointer. A root points to itself, so parent[x] = x identifies the root. That root is the component’s representative.

    make-set(x) creates a new component containing only x. It sets parent[x] = x and initializes a rank or size value. Initially, every item is its own representative. When two components merge, one root becomes a child of the other root. The resulting parent forest encodes membership: following parent links eventually reaches the representative.

    To test whether two elements belong to the same component, compare their representatives. If find(a) = find(b), they are connected according to the unions performed so far. This structure tracks connectivity efficiently; it is not intended to enumerate the full route between two vertices.

    How do you implement a union-find data structure with make-set, find, and union?

    Store parent and rank in arrays or maps. The following pseudocode includes both standard optimizations:

    make-set(x): Set parent[x] = x and rank[x] = 0.

    find(x): If parent[x] is not x, replace parent[x] with find(parent[x]). Return parent[x].

    union(a, b): Compute rootA = find(a) and rootB = find(b). If the roots match, stop. Otherwise, attach the lower-rank root below the higher-rank root. If the ranks match, choose either root as the parent and increase its rank by one.

    For elements A through E, initialization produces:

    • Initial: parent = {A:A, B:B, C:C, D:D, E:E}; rank = {A:0, B:0, C:0, D:0, E:0}.
    • union(A, B): attach B to A; parent[B] = A and rank[A] = 1.
    • union(C, D): attach D to C; parent[D] = C and rank[C] = 1.
    • union(A, C): both roots have rank 1, so attach C to A and raise rank[A] = 2. D still points to C.
    • union(D, E): finding D reaches A through C, then compresses D to point directly to A. E attaches to A.

    The final parent array is {A:A, B:A, C:A, D:A, E:A}, with A as representative and rank A equal to 2. Calling find(D) now returns A immediately.

    How do path compression and union by rank work?

    Path compression changes every node visited by find to point directly to the root. In the example, D initially points to C, and C points to A. After find(D), D points to A. The operation may traverse several links once, but later searches from D skip those intermediate nodes.

    Union by rank controls how roots are linked. Rank estimates a tree’s height: attach the smaller-rank tree beneath the larger-rank tree, and increase rank only when equal ranks merge. This avoids creating long chains. A size array can replace rank by attaching the smaller component to the larger one.

    How does disjoint set union achieve near-constant amortized time?

    Without either optimization, repeated unions can form a chain, making find take O(n) time. Union by rank limits tree height to O(log n), while path compression flattens the portions of trees that searches actually visit. Used together, a sequence of m operations on n elements takes O(m α(n)) amortized time, where α is the inverse Ackermann function and grows so slowly that it is effectively constant for practical input sizes. Each make-set is O(1), and the arrays require O(n) space.

  • Bogosort and Bogobogosort Explained

    Bogosort and Bogobogosort Explained

    Bogosort sorts by repeatedly randomizing a list until the list happens to be in ascending order. Its stopping condition is simple—stop when an ordered scan finds no inversion—but its expected work is impractical: for n distinct items, one successful permutation appears only once in n! equally likely permutations on average.

    Bogobogosort is a separate recursive variant, not another spelling for bogosort. It adds nested sorting and retry stages, making its expected behavior even less practical.

    How Bogosort Works: Stopping Condition, Pseudocode, and a Tiny Trace

    Assume the input contains distinct values and should be sorted in ascending order. Bogosort tests the current order, then randomly shuffles the entire list when the test fails. It stops only after isSorted(A) returns true.

    Pseudocode:

    1. If isSorted(A) is true, return A.
    2. Shuffle A uniformly at random.
    3. Repeat steps 1 and 2 until the list is sorted.

    For the tiny input [2, 1, 3], the first check fails because 2 precedes 1. A possible shuffle produces [1, 3, 2], which also fails. Another shuffle might produce [3, 2, 1], followed by [1, 2, 3]. The algorithm stops at that point. A random shuffle can repeat an earlier arrangement, so this trace is only one possible path.

    Why Does Bogosort’s Expected Runtime Grow Factorially?

    With n distinct values, there are n! possible permutations. Under a uniform shuffle, exactly one is sorted, giving each attempt a success probability of 1/n!. The geometric-distribution intuition is therefore straightforward: the expected number of attempts is n!.

    That count grows quickly: five items have 120 possible orders, while ten items have 3,628,800. Each attempt also needs an order check, which takes O(n) time. Bogosort consequently has an expected running time commonly expressed as O(n · n!), assuming uniform shuffling and distinct elements.

    Its randomized worst case has no finite upper bound. The shuffling process could, in principle, avoid the sorted permutation indefinitely, even though the probability of eventual success is one under standard independent randomization.

    How Bogobogosort Differs: A Separate Recursive Variant

    Classic bogobogosort uses recursion to make the retry process more deeply nested:

    1. Recursively apply bogobogosort to the first n − 1 items.
    2. When that prefix is sorted, check the entire list.
    3. If the full list is not sorted, shuffle all n items and restart the process.

    The one-item case is already sorted and serves as the base case. The defining difference is that an outer attempt can invoke a complete recursive attempt on a shorter prefix before it gets another chance to test the full list. Ordinary bogosort simply shuffles until the whole list is sorted; bogobogosort builds recursive retries into that loop.

    Its expected complexity depends on the precise implementation and shuffle model. Informal analyses of the classic variant often describe growth on the order of O((n!)n!), or otherwise use superfactorial-style estimates. The exact label matters less than the structure: its expected runtime is vastly worse than bogosort’s factorial behavior, and its randomized worst case is likewise unbounded.

    Why Are These Algorithms Still Discussed?

    Bogosort and bogobogosort are useful cautionary examples rather than practical sorting tools. They make probability concrete, show why factorial search spaces become unmanageable, and demonstrate how a recursive retry can amplify an already poor algorithm. They also help separate expected runtime from worst-case guarantees: a process can be almost certain to finish eventually while still requiring an absurd expected amount of work.

  • AVL Tree Balance Factor: Calculate and Fix Rotations

    AVL Tree Balance Factor: Calculate and Fix Rotations

    The AVL tree balance factor shows whether a node’s left and right subtrees remain close in height. After each insertion, calculate this value while moving from the new node toward the root. A value outside the range -1 to 1 identifies the ancestor that needs a rotation.

    These AVL tree examples use one height convention and one sign convention throughout, so each LL, RR, LR, or RL case follows directly from the observed values.

    What Is the AVL Tree Balance Factor? Set Height and Sign Convention First

    Set the height of an empty child to 0 and the height of a leaf to 1. For every node:

    height(node) = 1 + max(height(left), height(right))

    Using left height minus right height, the balance factor formula is:

    balance factor = height(left subtree) − height(right subtree)

    • +1: the left subtree is one level taller.
    • 0: both subtrees have equal height.
    • -1: the right subtree is one level taller.

    An AVL node is height-balanced when its factor is -1, 0, or +1. A factor of +2 means left-heavy imbalance; -2 means right-heavy imbalance. The sign convention matters: reversing the subtraction would reverse the case labels.

    How Do You Calculate the Balance Factor in an AVL Tree and Find the First Unbalanced Ancestor?

    After inserting a key as in an ordinary binary search tree, start at that new leaf and move upward. At each node, update its height first, then calculate its balance factor. The first unbalanced ancestor is the first node encountered with a factor of +2 or -2. Because the search proceeds upward, this is the lowest unbalanced ancestor and normally the point where you apply the rotation.

    1. Insert the key according to binary-search-tree ordering.
    2. Recompute each ancestor’s height using the larger child height.
    3. Calculate left height minus right height.
    4. Use the heavy child and the inserted key’s direction to identify LL, RR, LR, or RL.
    5. Rotate, then recompute heights from the lowest changed node upward.

    Which AVL Tree Examples Show LL and RR Rotations With Updated Heights?

    LL case: Insert 30, then 20, then 10. The path leans left twice:

    30(+2)
    ↙ 20(+1)
    ↙ 10(0)

    Node 30 is the first unbalanced ancestor. Apply one right rotation at 30. Node 20 becomes the root, with 10 as its left child and 30 as its right child. Each leaf has height 1; node 20 has height 2 and balance factor 0. The rotation changes structure first, so calculate the lower node’s height before the new root’s height.

    RR case: Insert 10, then 20, then 30. The path leans right twice. Node 10 has factor -2, so apply one left rotation at 10. Node 20 becomes the root, with 10 on the left and 30 on the right. Both leaves have height 1, and node 20 has height 2 with factor 0.

    How Does AVL Tree Balancing Resolve LR and RL Cases With Updated Heights?

    LR case: Insert 30, then 10, then 20. Node 30 has factor +2, but its left child, 10, has factor -1. This is a left-right bend, so use two rotations:

    1. Rotate left at 10. The subtree becomes 20 with 10 as its left child.
    2. Rotate right at 30. Node 20 becomes the subtree root, with 10 and 30 as children.

    After the structural changes, 10 and 30 each have height 1. Node 20 receives height 2 and factor 0.

    RL case: Insert 10, then 30, then 20. Node 10 has factor -2, while its right child, 30, has factor +1. Apply the mirror sequence:

    1. Rotate right at 30, making 20 the root of that subtree with 30 on the right.
    2. Rotate left at 10, making 20 the subtree root with 10 on the left.

    Again, the two leaves have height 1, and the new subtree root 20 has height 2 and factor 0. This is the practical rule for AVL tree balancing: single-direction growth uses one rotation; a bend uses the child rotation first, followed by the opposite rotation at the unbalanced ancestor.

  • Big O graph: Complexity Chart and Sorting Reference

    Big O graph: Complexity Chart and Sorting Reference

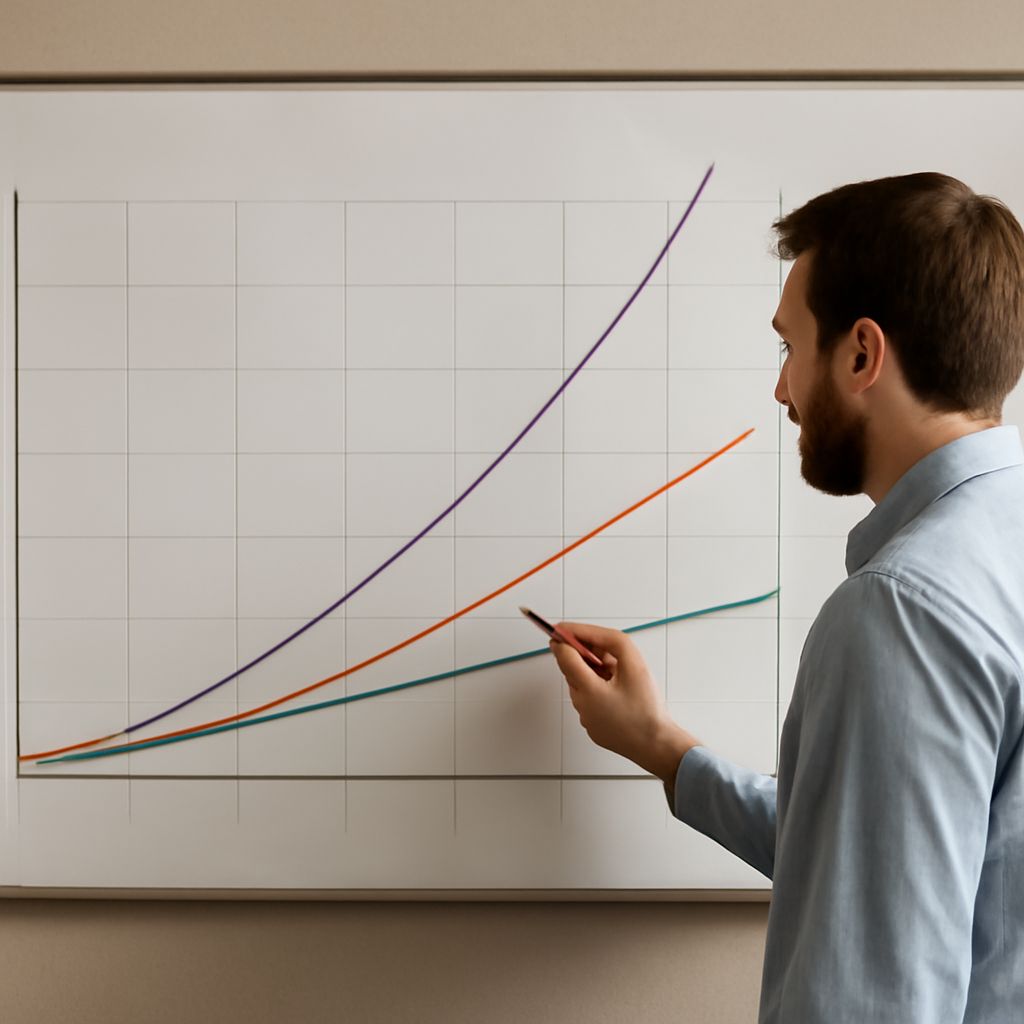
    Big O graph comparisons show how an algorithm’s work grows as the input size, n, increases. The most useful order is O(1), O(log n), O(n), O(n log n), O(n²), O(2ⁿ), and O(n!). Curves that look similar at small inputs separate sharply at larger ones.

    Big O describes growth, not exact wall-clock time. Hardware, implementation, constants, and input patterns affect measured time, while Big O helps compare how algorithms scale.

    Big O graph: How growth rates diverge

    This growth-rate chart orders common complexity classes from slowest-growing to fastest-growing:

    1. O(1), constant: The work stays roughly the same regardless of n, such as reading an array item by index.
    2. O(log n), logarithmic: Each step removes a fraction of the remaining input. Binary search is the standard example.
    3. O(n), linear: Work increases in direct proportion to the input, such as scanning every item once.
    4. O(n log n), linearithmic: Common in efficient comparison sorting, including merge sort and average-case quicksort.
    5. O(n²), quadratic: Two input-sized loops can compare many pairs, as in basic comparison sorts.
    6. O(2ⁿ), exponential: Each added input item can double the work, often appearing in exhaustive subset searches.
    7. O(n!), factorial: Work grows by trying every permutation, making it impractical quickly.

    Big O time complexity from constant to factorial

    Concrete scale examples make the divergence easier to judge. At n = 1,000, a linear algorithm performs roughly 1,000 units of work, while a quadratic one can reach about 1,000,000. At n = 1,000,000, O(n) is about 1,000,000 units and O(n²) is about 1,000,000,000,000.

    • O(1): About 1 operation remains about 1 operation at every input size.
    • O(log n): Binary search needs about 20 halvings for 1,000,000 items because log₂(1,000,000) is close to 20.
    • O(n log n): At 1,000,000 items, a rough comparison count is 1,000,000 × 20, before constants and lower-order work.
    • O(2ⁿ): At n = 20, there are 1,048,576 possible branches; at 40, there are more than 1 trillion.
    • O(n!): 10! equals 3,628,800 arrangements, while 13! exceeds 6 billion.

    These are operation-count intuitions, not timing promises. A highly optimized O(n²) routine can beat an O(n log n) routine for a small input, but the growth-rate advantage usually dominates as n expands.

    Big O cheat sheet for sorting algorithms

    Use this Big O sorting reference to compare the usual best, average, and worst runtimes. Auxiliary space excludes the input array itself.

    • Bubble sort: Best O(n) with early-exit detection; average O(n²); worst O(n²); auxiliary space O(1).
    • Insertion sort: Best O(n) on an already sorted or nearly sorted list; average O(n²); worst O(n²); auxiliary space O(1).
    • Selection sort: Best, average, and worst O(n²); auxiliary space O(1).
    • Merge sort: Best, average, and worst O(n log n); auxiliary space O(n) for the usual array implementation.
    • Quicksort: Best O(n log n); average O(n log n); worst O(n²) with poor pivot choices; auxiliary space averages O(log n) for the recursion stack and can reach O(n).
    • Heap sort: Best, average, and worst O(n log n); auxiliary space O(1).
    • Counting sort: Best, average, and worst O(n + k), where k is the value range; auxiliary space O(n + k).

    How to read Big O runtime in best, average, and worst cases

    Big O runtime labels describe how an algorithm behaves under a selected input condition. Best case is the most favorable arrangement, average case represents typical assumptions, and worst case is the slowest permitted arrangement.

    For example, insertion sort is O(n) when data is already ordered because each item moves little, but O(n²) when data is reverse-ordered. Quicksort is usually O(n log n), yet an unfavorable pivot sequence can produce O(n²). Merge sort gives the most consistent comparison-sort bound—O(n log n) in all three cases—but uses extra memory. For nearly sorted, small inputs, insertion sort’s low overhead can be preferable; for predictable large-input performance, merge sort or heap sort offers a stronger worst-case guarantee.

  • Stack vs Queue: Operations and Use Cases

    Stack vs Queue: Operations and Use Cases

    Stack vs queue comes down to the required access pattern. A stack uses LIFO (last in, first out), so the newest item leaves first. A queue uses FIFO (first in, first out), so the oldest item leaves first. Choose a stack for nested work, undo behavior, or backtracking; choose a queue for arrival-order processing and fair turn-taking.

    The difference between stack and queue behavior becomes clear when both structures receive the same items. Their operation names, implementations, and use cases follow from that ordering rule.

    Stack vs queue: LIFO or FIFO, and what order do items leave?

    Insert the items A, B, and C in that order.

    • Stack: A is placed first, then B, then C. Removing items returns C, B, and A.
    • Queue: A is placed first, then B, then C. Removing items returns A, B, and C.

    In a stack, the insertion and removal point is the top. Each new item covers the previous one, like a pile of plates. The most recently added item is therefore immediately available.

    In a queue, insertion occurs at the rear and removal occurs at the front. Items remain in their arrival order, like people waiting in a line. A standard queue removes the oldest waiting item rather than the newest one.

    Queue vs stack: How do their operations differ?

    Stack operations focus on one accessible end:

    • Push: adds an item to the top.
    • Pop: removes and returns the top item.
    • Peek or top: reads the top item without removing it.

    Queue operations separate the entry and exit ends:

    • Enqueue: adds an item at the rear.
    • Dequeue: removes and returns the item at the front.
    • Front or peek: reads the next item without removing it.

    With a suitable implementation, push, pop, enqueue, dequeue, and peek are expected O(1) operations. That means the operation takes constant time on average or by design, regardless of how many items are stored. A queue implemented by repeatedly removing index zero from a basic array can become O(n), because every remaining item may need to shift. A circular buffer or linked queue avoids that cost.

    What is the difference between stack and queue implementations?

    An array or dynamic array is a natural stack implementation. Adding and removing at the array’s end usually takes O(1) amortized time, while accessing the top is direct. A linked-list stack can also provide O(1) push and pop when the head represents the top. It uses extra memory for links but does not require contiguous storage.

    Queues are commonly implemented with a circular array, a linked list, or a double-ended queue (deque). A circular array keeps front and rear positions moving through a fixed or resizable buffer, so it does not shift every remaining item after dequeue. A linked queue maintains references to both the front and rear nodes, providing O(1) enqueue and dequeue.

    Both structures typically use O(n) space for n items. The practical choice depends on memory layout, resizing behavior, concurrency requirements, and whether the program needs access at one end or two. Neither structure normally supports efficient arbitrary-position removal; that requirement may call for a different data structure.

    When should you use stacks and queues?

    Use stacks for problems where the latest unfinished task must be handled first:

    • Function calls and recursion: call frames form a stack, with the newest active call completed first.
    • Parsing nested syntax: parentheses, brackets, and HTML-like tags can be matched against recently opened elements.
    • Undo and redo: actions are stored so the most recent change can be reversed first.
    • Depth-first search and backtracking: the algorithm follows one path, then returns to the latest decision point when that path fails.

    Use queues when work should be processed in arrival order:

    • Breadth-first search: nodes are visited level by level, with earlier discoveries handled first.
    • Task pipelines: jobs wait in sequence for a worker or service to process them.
    • Event handling: incoming events can be processed in the order they were received.
    • Request scheduling: a basic service queue gives earlier requests an opportunity before later ones.

    In short, stacks and queues solve opposite ordering problems: choose the stack’s newest-first behavior for nesting and backtracking, and the queue’s oldest-first behavior for orderly flow through a system.

  • Adjacency List: How Graphs Store Edges

    Adjacency List: How Graphs Store Edges

    An adjacency list stores each vertex with its neighboring vertices, rather than placing every possible pair in a grid. It is usually the most efficient representation for a sparse graph, where the number of edges is much smaller than the square of the number of vertices.

    An adjacency list is not an ordered path through a graph. Each entry records local connections; a traversal algorithm chooses the next vertex separately.

    What is an adjacency list?

    An adjacency list maps every vertex to a collection of adjacent vertices. In an adjacency list graph, the outer structure is commonly an array or map, and each value is a dynamic list. An array works well when vertices have numeric indexes. A map is useful when labels such as “A” or “Airport 12” identify vertices.

    For a vertex v, its list contains the vertices reachable by one edge from v. The number of entries is its degree in an undirected graph or its out-degree in a directed graph. Isolated vertices still receive an empty list so that the representation includes every vertex.

    How do you build a graph adjacency list from edge data?

    Start with the vertices, create an empty list for each one, and then process each edge. Consider this undirected edge data:

    • A-B
    • A-C
    • B-D
    • C-D

    The matching adjacency-list representation is:

    • A: B, C
    • B: A, D
    • C: A, D
    • D: B, C

    Each undirected edge appears twice. The edge A-B is recorded in A’s list and B’s list, allowing neighbor lookup from either endpoint. A simple construction procedure is:

    1. Initialize an empty list for every vertex.
    2. For an edge between u and v, append v to u’s list.
    3. Because the edge is undirected, append u to v’s list as well.

    If the input can contain parallel edges, append each occurrence unless the application requires duplicate removal. A set can enforce unique neighbors, but it changes the storage structure and may add overhead.

    How does an adjacency list represent directed and weighted edges?

    Direction determines which list receives an edge. For directed edges A→B, A→C, and C→B, the list is:

    • A: B, C
    • B: empty
    • C: B

    The reverse connection is not implied. If an algorithm must find incoming neighbors, it can maintain a second reverse adjacency list or scan all lists.

    Weighted edges store a neighbor together with its weight. For example, the weighted edge data A→B with cost 5 and A→C with cost 2 becomes:

    • A: (B, 5), (C, 2)
    • B: empty
    • C: empty

    The weight can represent distance, price, capacity, or another application-specific value. Adding weights changes the value stored beside each neighbor, not the basic adjacency-list structure or its usual asymptotic costs.

    When is an adjacency list for a graph better than an adjacency matrix?

    For V vertices and E edges, an adjacency list uses O(V + E) space when each edge is stored once in a directed graph or twice in an undirected graph. This is efficient for sparse graphs because it stores actual connections instead of all possible connections.

    • Iterating neighbors: O(degree(v)) for vertex v. The algorithm visits only listed neighbors.
    • Testing a specific edge: usually O(degree(v)) when scanning the list for the target. A hash-based neighbor set provides O(1) average lookup, with additional memory overhead.
    • Adding an edge: commonly O(1) when appending to a list, unless duplicate checking is required.

    An adjacency matrix uses O(V²) space and provides O(1) edge testing by checking one cell. However, finding all neighbors of a vertex requires scanning its entire row, which costs O(V), including cells for absent edges. Choose an adjacency list when neighbor traversal and compact storage matter, especially for sparse networks. Choose a matrix when the graph is dense or constant-time edge tests are more important than memory use.

  • Binary XOR: How to Compare Bits and Hex Digits

    Binary XOR: How to Compare Bits and Hex Digits

    Binary XOR compares corresponding bits and returns 1 when the bits differ, or 0 when they match. To calculate it correctly, align both operands to the same width, apply the one-bit rule from left to right, and read the resulting bit string.

    The same method works with hexadecimal values. Each hexadecimal digit represents a four-bit group, called a nibble, so hexadecimal XOR lets you process four aligned bits at a time.

    The One-Bit Binary XOR Rule

    The XOR, or exclusive OR, rule has four possible inputs:

    • 0 XOR 0 = 0
    • 0 XOR 1 = 1
    • 1 XOR 0 = 1
    • 1 XOR 1 = 0

    In short, XOR produces 1 only when exactly one input bit is 1. Matching bits produce 0. This is a comparison operation, not ordinary addition: do not carry a 1 into the next position when both bits are 1.

    How to Calculate XOR in Binary

    Align operands to equal width

    Write the operands in rows with their least significant bits, the rightmost bits, aligned. If one value has fewer bits, add leading zeros until both values have the same width. Leading zeros preserve the value while making each position comparable.

    1. Write both binary values at equal width.
    2. Compare the bits in each column.
    3. Write 1 for different bits and 0 for matching bits.
    4. Read the resulting row as the XOR result.

    Worked example: 101101 XOR 011011

    Both operands already contain six bits:

    101101
    011011

    Compare each aligned position:

    • 1 XOR 0 = 1
    • 0 XOR 1 = 1
    • 1 XOR 1 = 0
    • 1 XOR 0 = 1
    • 0 XOR 1 = 1
    • 1 XOR 1 = 0

    Therefore, 101101 XOR 011011 = 110110. Each output bit comes only from the two bits in the same column; there is no carry between columns.

    How to Calculate XOR in Hexadecimal

    Treat each hexadecimal digit as a four-bit nibble

    Hexadecimal is shorthand for binary. The digits 0 through F represent four-bit patterns from 0000 through 1111. For example, 5 is 0101, A is 1010, 3 is 0011, and C is 1100.

    To perform hexadecimal XOR, align the hexadecimal digits by position and XOR each pair of digits independently. You can expand each pair into four bits, apply the one-bit rule, then convert the four-bit result back to one hex digit. There is no carry between adjacent nibbles.

    Worked example: 5A XOR 3C

    Expand the two values into nibbles:

    5A = 0101 1010
    3C = 0011 1100

    Process each nibble separately:

    • 5 XOR 3: 0101 XOR 0011 = 0110, which is 6.
    • A XOR C: 1010 XOR 1100 = 0110, which is 6.

    Thus, 5A XOR 3C = 66. Hexadecimal XOR is the same bitwise operation as XOR in binary, written in a shorter form.

    How to Check and Reverse an XOR Result

    Apply the same mask twice to recover the original

    XOR is reversible because applying the same value twice cancels its effect. For any value X and mask M:

    (X XOR M) XOR M = X

    Using the binary example, the result can be checked by applying the mask again:

    110110 XOR 011011 = 101101

    The original value returns because each bit follows this rule: a bit XORed with 0 stays unchanged, while a bit XORed with 1 flips once and flips back when XORed with 1 again.

  • Binary Bits Explained: From 0 and 1 to Number Patterns

    Binary Bits Explained: From 0 and 1 to Number Patterns

    Binary bits are the smallest standard units of digital information. A binary bit has two possible symbolic values, 0 and 1. When several bits are placed together, their positions carry powers-of-two values, allowing the group to represent numbers, flags, characters, and other encoded data.

    The key rule is simple: one bit creates 2 possible patterns, while n bits create 2n possible patterns. The pattern count is separate from the numeric range, which depends on whether the bits are interpreted as unsigned, signed, or another data type.

    Binary Bits: What Is a Bit?

    A bit is a binary digit and the smallest abstract unit of information in digital computing. At the logical level, it records one of two states: 0 or 1. These symbols are convenient labels for alternatives such as off/on, false/true, or low/high.

    Why 0 and 1 are symbolic, not universal voltage levels

    In software and data formats, 0 and 1 describe logical states rather than literal physical voltage levels. Hardware can represent those states using different electrical, magnetic, optical, or electronic mechanisms. Even electrical systems can use different voltage ranges and signaling conventions. Therefore, a bit always has two logical alternatives, but every physical bit is not implemented with the same electrical states.

    A Binary Bit Has Two Possible Values

    One bit can hold either 0 or 1 at a given time. It cannot represent a third distinct binary value without adding another bit or changing the encoding system.

    With two bits, the available patterns are 00, 01, 10, and 11. The order matters when the bits form a number. The rightmost position is the least significant bit, and the leftmost position is the most significant bit in the usual notation.

    Bit Values in Binary Place Values

    Each position in a binary number has a place value based on a power of two. Starting at the right, the values are 20 = 1, 21 = 2, 22 = 4, 23 = 8, and so on. A 1 includes its position’s value; a 0 contributes nothing.

    Reading 1011 with powers of two

    Read 1011 from left to right using the place values 8, 4, 2, and 1:

    • 1 × 8 = 8
    • 0 × 4 = 0
    • 1 × 2 = 2
    • 1 × 1 = 1

    Adding the included values gives 8 + 2 + 1 = 11. The same four binary positions can produce any unsigned value from 0 through 15.

    How Many Patterns Can n Bits Represent?

    The number of possible patterns doubles whenever one bit is added. The formula is 2n, where n is the number of bits. For example, 3 bits provide 23 = 8 patterns, and 8 bits provide 28 = 256 patterns.

    Patterns versus unsigned and signed numeric ranges

    Pattern count does not by itself specify the numbers represented. For n unsigned bits, the range is 0 through 2n − 1, using all patterns for nonnegative values. Thus, four unsigned bits represent 16 patterns and the values 0–15.

    A common signed format, two’s complement, uses the same 2n patterns for a range from −2n−1 through 2n−1 − 1. Four signed bits therefore represent −8 through 7. Other encodings can assign different meanings to the same patterns.

    Bits Inside Bytes and Machine Values

    A byte conventionally contains 8 bits, so it has 256 possible patterns. As an unsigned integer, a byte represents 0–255. In common two’s-complement form, it represents −128–127.

    Machine values may use bits as more than whole numbers. Individual bits can act as Boolean flags, while groups of bits can encode an instruction field, character, color component, or measurement. The surrounding format determines how the bit values should be interpreted.

  • Bit vs Byte: The Difference Explained

    Bit vs Byte: The Difference Explained

    In bit vs byte comparisons, a bit is one binary digit, while a byte is conventionally a group of eight bits. The practical difference between them is scale: bits are the smallest units used to represent data, while bytes bundle those units into a more usable measure for storage and memory. Their symbols are not interchangeable: lowercase b means bit, and uppercase B means byte.

    A reliable reading of a speed or capacity depends on both the unit and the prefix. An internet rate of 100 Mbps means 100 megabits per second, not 100 megabytes; a file labeled 100 MB contains 100 megabytes. Confusing b with B creates an eightfold error.

    Bit vs byte: What does each unit measure?

    A bit, short for binary digit, has a value of either 0 or 1. Digital systems use these two states to represent conditions such as off and on, or false and true. The lowercase symbol for a bit is b.

    A byte is conventionally eight bits grouped together. Eight binary positions can represent 256 possible combinations, from 00000000 through 11111111. The uppercase symbol for a byte is B. Modern computers commonly use bytes to describe memory, file sizes, and other addressable data quantities.

    • Bit (b): One binary digit, used often for communication rates and individual data states.
    • Byte (B): Eight bits, used often for storage, memory, and file sizes.

    The relationship is fixed for ordinary modern usage: 1 B = 8 b. This relationship does not make the symbols interchangeable. A capital B always describes a byte, while a lowercase b describes a bit.

    Byte vs bit: How do their symbols and uses differ?

    The byte vs bit distinction matters because different industries measure different things. Network equipment and internet service plans commonly use bits per second, written as bps. File systems, operating systems, applications, and storage manufacturers commonly report capacities in bytes, written as B.

    • Network rate: 500 Mbps means 500 megabits transferred per second.
    • File size: 500 MB means 500 megabytes of stored data.
    • Memory capacity: 16 GB describes a byte-based capacity.

    Prefixes follow the same case-sensitive rule. Mb means megabit, while MB means megabyte. Likewise, Gb is gigabit and GB is gigabyte. Reading the prefix and the unit together prevents incorrect comparisons.

    What is the difference between bit and byte in network and storage figures?

    Understanding the difference between bit and byte is especially useful when comparing an advertised network speed with the size of a download. Providers often quote network rates in bits because communication systems transmit streams of individual binary signals. Storage is usually described in bytes because files and memory are organized into byte-based quantities.

    For example, a 100 Mbps connection has a theoretical raw rate of 12.5 MB per second:

    100 megabits ÷ 8 = 12.5 megabytes

    Actual transfer speeds can be lower because of protocol overhead, congestion, wireless conditions, or server performance. Those factors do not change the conversion between bits and bytes.

    Decimal prefixes such as megabit and megabyte commonly represent 1,000,000 units. Binary prefixes such as mebibit and mebibyte represent 1,048,576 units. Whichever prefix system is used, eight bits still equal one byte.

    How do you convert bits and bytes?

    Use the basic relationship and keep the unit symbols visible during the calculation:

    1. Bits to bytes: Divide by 8. For example, 80 Mb ÷ 8 = 10 MB when the prefixes match.
    2. Bytes to bits: Multiply by 8. For example, 5 MB × 8 = 40 Mb.
    3. Single units: 1 b = 0.125 B, and 1 B = 8 b.

    When converting a network speed into an estimated byte-based download rate, divide the numerical rate by eight. When converting a file size into an equivalent bit quantity, multiply by eight. Preserve b and B in labels, calculations, and specifications.