Category: Algorithms

  • How to Merge Two Sorted Lists Efficiently

    How to Merge Two Sorted Lists Efficiently

    Merging two sorted lists is a fundamental operation in computer science, particularly useful in data processing and algorithm optimization. By combining two ordered sequences into a single sorted sequence, you enhance efficiency in searching and data manipulation tasks. This article will guide you through the process of merging sorted lists, highlight common pitfalls, and explore its practical applications.

    What is the Purpose of Merging Sorted Lists?

    The primary purpose of merging sorted lists is to create a new sorted list from two pre-sorted lists. This operation is essential in algorithms like merge sort, where it helps maintain order while combining sorted sublists. Merging simplifies data handling, allowing for efficient search operations and easier data analysis, making it a cornerstone of algorithm design.

    How to Merge Two Sorted Lists: Step-by-Step Guide

    Here’s a straightforward method to merge two sorted lists in Python using a two-pointer technique:

    1. Initialize Pointers: Start with two pointers, each pointing to the beginning of the respective lists.
    2. Compare Elements: Compare the elements pointed by the two pointers. Append the smaller element to the result list and move the corresponding pointer forward.
    3. Advance Pointers: If one list is exhausted before the other, append the remaining elements of the non-exhausted list to the result.
    4. Return the Result: Once both lists are fully traversed, return the merged list.

    Here’s a Python code example:

    def merge_two_sorted_lists(list1, list2):
        merged_list = []
        i, j = 0, 0
        
        while i < len(list1) and j < len(list2):
            if list1[i] < list2[j]:
                merged_list.append(list1[i])
                i += 1
            else:
                merged_list.append(list2[j])
                j += 1
                
        while i < len(list1):
            merged_list.append(list1[i])
            i += 1
            
        while j < len(list2):
            merged_list.append(list2[j])
            j += 1
            
        return merged_list
    

    What are Common Mistakes to Avoid?

    • Ignoring Edge Cases: Always handle cases where one or both lists are empty. This avoids index errors and ensures the function's robustness.
    • Incorrect Pointer Management: Ensure pointers are correctly incremented after appending elements to avoid infinite loops or skipped elements.
    • Assuming Lists are Sorted: Double-check that input lists are sorted. Otherwise, the merge result will not be correctly ordered.

    What are Some Practical Applications?

    • Data Analysis: Merging sorted lists is crucial in data analysis tasks that involve combining datasets while preserving order, enhancing data readability and processing efficiency.
    • Database Management: In databases, merging operations optimize query performance by consolidating sorted query results efficiently.
    • Algorithm Design: This operation is integral to many algorithms, such as merge sort, which uses it to combine sorted subarrays, improving the overall sorting process.
    • Real-time Systems: Efficient list merging is critical in environments requiring real-time data processing, where speed and order are paramount.
  • Understanding Regex Special Characters

    Understanding Regex Special Characters

    Regex, or regular expressions, are powerful tools used in programming and data processing to match patterns within text. At the heart of regex are special characters that serve as the building blocks for crafting complex search patterns. Understanding these characters is essential for anyone looking to enhance their algorithmic skills, particularly in data-driven environments.

    What Are Regex Special Characters?

    Regex special characters are symbols that carry special meanings in pattern matching tasks. Unlike regular characters, these symbols allow users to perform more precise searches and manipulations within strings. Some of the most commonly used special characters include:

    • Dot (.): Matches any character except a newline.
    • Asterisk (*): Matches zero or more occurrences of the preceding element.
    • Plus (+): Matches one or more occurrences of the preceding element.
    • Question Mark (?): Matches zero or one occurrence of the preceding element.
    • Brackets ([]): Matches any one character enclosed within the brackets.
    • Backslash (\\): Escapes a special character, making it a literal.

    How to Use Regex Special Characters

    Using regex special characters involves understanding the context of your search and constructing patterns accordingly. Start by defining the element you wish to match and then refine your search with special characters:

    • To match any character, use the dot symbol. For example, “a.c” matches “abc”, “a2c”, and “a-c”.
    • To find multiple occurrences, apply the asterisk or plus. “go*” finds “g”, “go”, and “goo”, while “go+” requires at least one “o”.
    • To create optional patterns, the question mark is utilized. “colou?r” finds both “color” and “colour”.
    • Use brackets to specify a set of possible characters. “[abc]” matches “a”, “b”, or “c”.
    • The backslash is essential for handling reserved characters. To match a literal dot, use “\\.”

    Common Examples in Algorithms

    Regex is extensively used in algorithms for tasks such as input validation, data parsing, and search optimization. Here are a few examples:

    • Email Validation: A common regex pattern checks the structure of an email. This typically includes matching alphanumeric characters, the “@” symbol, and a domain. Example: ^[a-zA-Z0-9_.+-]+@[a-zA-Z0-9-]+\.[a-zA-Z0-9-.]+$.
    • URL Parsing: Regex helps in extracting parts of a URL such as protocol, domain, and path. Example: ^(https?:\/\/)?([\da-z.-]+)\.([a-z.]{2,6})([/\w .-]*)*\/?$.
    • Text Search and Replace: Finding and replacing patterns within text files using regex can automate large-scale text edits efficiently.

    Tips for Effective Regex Implementation

    Implementing regex effectively requires practice and an understanding of both the problem at hand and regex syntax. Here are some tips:

    • Test Regularly: Use online tools or integrated development environment (IDE) plugins to test your regex patterns in real-time.
    • Keep It Simple: Start with simple patterns and gradually build complexity. Over-complicated regex can become difficult to understand and maintain.
    • Document Your Patterns: Comment on your regex patterns within your codebase to explain their purpose, making future maintenance easier.
    • Consider Performance: Regex can impact processing speed, especially with large datasets. Optimize patterns to reduce unnecessary complexity.

    Understanding regex special characters and their applications in algorithms can unlock powerful data processing capabilities. Mastering these tools opens new avenues for efficient and precise text manipulation.

  • Understanding Support Vector Machines (SVMs)

    Understanding Support Vector Machines (SVMs)

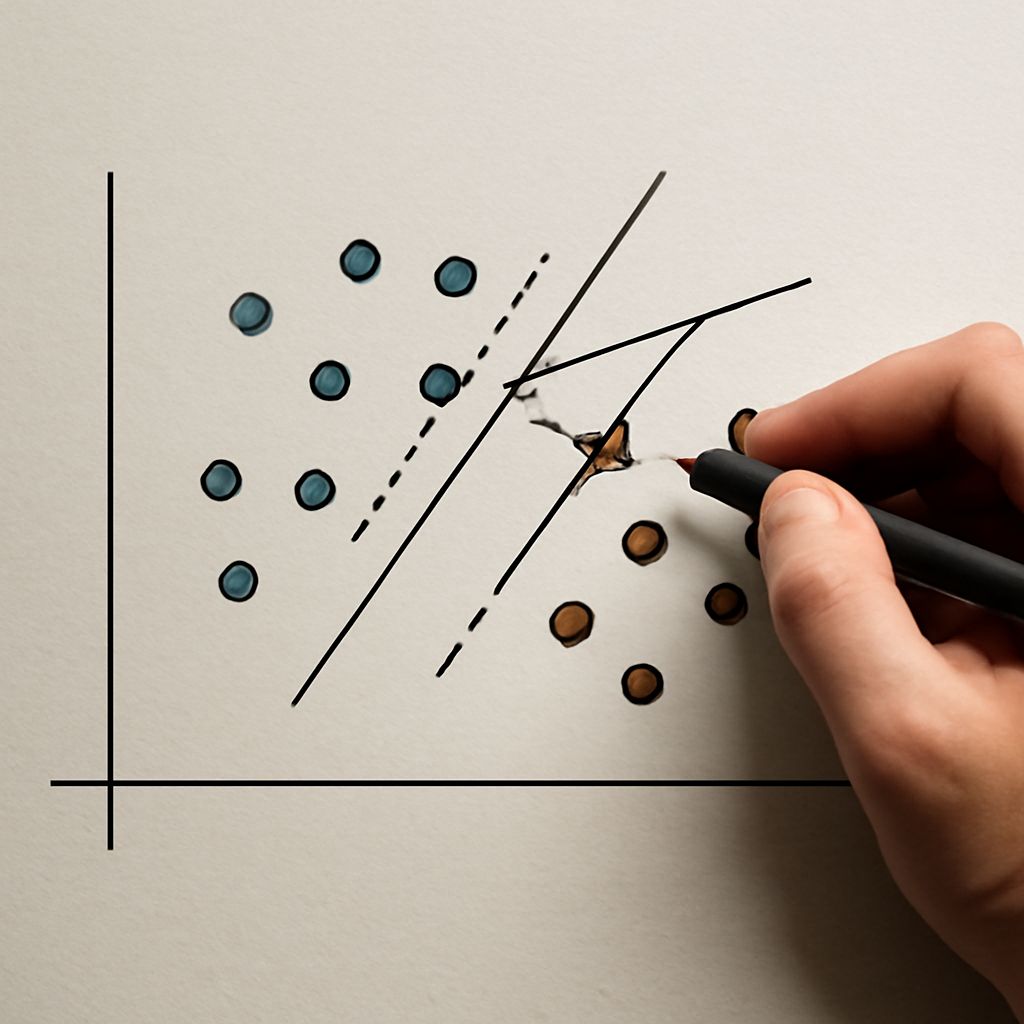
    Support Vector Machines (SVMs) are a powerful tool in the field of machine learning used for classification and regression tasks. They are particularly effective in high-dimensional spaces and are known for their ability to manage both linear and non-linear data. By finding the optimal hyperplane that separates classes, SVMs ensure robust data classification. This article delves into the workings of SVMs, their applications, and the benefits they offer in machine learning.

    What are Support Vector Machines?

    Support Vector Machines are supervised learning models used for classification and regression analysis. They operate by identifying a decision boundary—or hyperplane—that best separates data into different classes. In essence, SVMs aim to create a boundary with the maximum margin between classes, which enhances the model’s accuracy and generalization ability.

    How Do SVMs Work?

    SVMs work by transforming the input data into a high-dimensional space where a linear separation is feasible. The process involves identifying support vectors, which are the data points closest to the hyperplane and are crucial in defining the position and orientation of the hyperplane. By using kernel functions, SVMs can handle non-linear data transformation, making them versatile for a variety of datasets. The common kernels include linear, polynomial, radial basis function (RBF), and sigmoid.

    Applications of SVMs in Machine Learning

    SVMs have a wide range of applications in machine learning. In the field of text categorization, SVMs are employed to classify documents into predefined categories, such as spam detection in emails. Image recognition is another area where SVMs excel, particularly in facial recognition systems where they help differentiate between various facial features. Additionally, SVMs are used in bioinformatics for tasks like protein classification and cancer diagnosis, where they analyze complex biological data.

    Benefits of Using SVMs

    The benefits of using SVMs are numerous. They are effective in high-dimensional spaces, making them suitable for applications where the number of dimensions exceeds the number of samples. SVMs are also memory efficient, as they use a subset of training points to form the decision function. They provide versatility through different kernel functions, allowing them to adapt to linear and non-linear data. Moreover, SVMs offer robust performance with clear margins of classification, enhancing prediction accuracy.

  • Understanding Merge Sort Pseudocode

    Understanding Merge Sort Pseudocode

    Merge sort is a powerful and efficient sorting algorithm commonly used in computer science. It breaks down a list into smaller sublists until each sublist contains only one element, then merges those sublists to produce a sorted list. The beauty of merge sort lies in its efficiency, especially for large datasets.

    What is Merge Sort?

    Merge sort is a divide-and-conquer algorithm that splits a list into halves, sorts each half, and then merges the sorted halves back together. This process is repeated recursively until the entire list is sorted. The algorithm is known for its stability and efficiency, particularly with larger lists, as it consistently performs in O(n log n) time complexity.

    How Does Merge Sort Work?

    The merge sort algorithm involves two main steps: dividing the unsorted list and merging the sublists. Initially, the list is divided into two halves. These halves are then further divided recursively until single-element sublists are formed, which are inherently sorted. The merging process then begins, where two sorted sublists are combined into a single sorted list. This is done by comparing the smallest elements of each sublist and adding the smallest element to the new list, repeating the process until one sublist is exhausted, and then appending the remaining elements from the other sublist.

    Step-by-Step Guide to Merge Sort Pseudocode

    Understanding the pseudocode for merge sort is crucial for implementing this sorting algorithm. Below is a simple step-by-step guide:

    1. Function Call: Start by calling the merge sort function with the list to be sorted.
    2. Base Case: If the list has one or zero elements, return it as it is already sorted.
    3. Divide: Split the list into two halves.
    4. Recursive Sort: Recursively sort each half by calling the merge sort function on them.
    5. Merge: Merge the two halves back into a single sorted list using the merge function.

    Pseudocode example:

    
    function mergeSort(list):
      if length of list <= 1:
        return list
    
      mid = length of list / 2
      leftHalf = mergeSort(list[0:mid])
      rightHalf = mergeSort(list[mid:])
    
      return merge(leftHalf, rightHalf)
    
    function merge(left, right):
      result = empty list
      while left is not empty and right is not empty:
        if left[0] <= right[0]:
          append left[0] to result
          left = left[1:]
        else:
          append right[0] to result
          right = right[1:]
    
      append remaining elements of left to result
      append remaining elements of right to result
      
      return result
    

    Common Applications of Merge Sort

    Merge sort is widely used in various applications due to its predictable performance and stability. It's particularly useful in scenarios where large datasets need sorting, as it handles large amounts of data efficiently. Some common applications include:

    • External Sorting: Useful for sorting large files stored on disk that don't fit into memory.
    • Inversion Count Problem: Used to count the number of inversions in an array, which can help in determining how far an array is from being sorted.
    • Linked Lists: Efficiently sorts linked lists as it doesn't require random access to elements, unlike quicksort.

    By understanding and implementing merge sort, you can enhance your algorithm toolkit and tackle complex sorting problems with ease.

  • Understanding the Number of Islands Algorithm

    Understanding the Number of Islands Algorithm

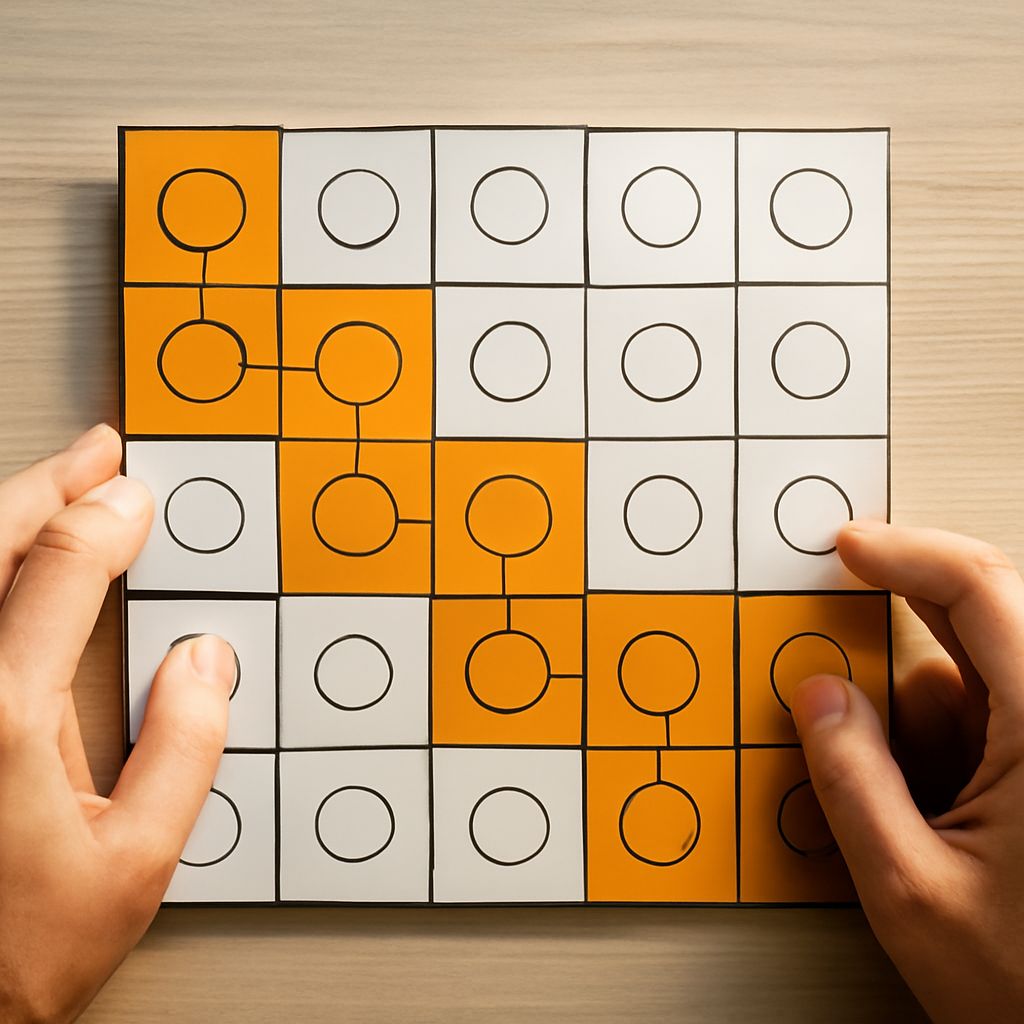
    The number of islands algorithm is a fascinating computer science problem that involves determining the count of separate islands in a 2D grid map. Each island is formed by contiguous blocks of land, represented as 1s, surrounded by water, depicted as 0s. This algorithm is widely used in various applications, from game development to geographical mapping and data analysis.

    What is the Number of Islands Algorithm?

    The number of islands algorithm seeks to identify and count distinct land masses within a given grid. This grid consists of cells marked by 1s and 0s, representing land and water, respectively. The algorithm’s goal is to traverse the grid and count how many separate islands exist, where islands are groups of adjacent land cells connected vertically or horizontally.

    How Does the Algorithm Work?

    Step-by-Step Explanation

    The algorithm typically employs a depth-first search (DFS) or breadth-first search (BFS) approach to explore all connected parts of an island. Here’s a step-by-step overview of the process:

    1. Initialize a count: Begin with a count of zero to track the number of islands.
    2. Traverse the grid: Loop through each cell in the grid.
    3. Identify new land: When a land cell (1) is encountered that hasn’t been visited, it signifies a new island. Increment the island count.
    4. Explore the island: Use DFS or BFS to mark all connected land cells as visited, ensuring each cell of the identified island is processed.
    5. Continue traversal: Move to the next unvisited cell in the grid and repeat the process until the entire grid is covered.

    Applications of the Number of Islands Algorithm

    This algorithm is pivotal in various fields, offering solutions to problems involving segmentation and counting of distinct entities. In game development, it helps in creating maps with distinct terrain features. Geographic information systems (GIS) utilize this algorithm for mapping land and water bodies. Moreover, in image processing, it assists in object detection and recognition by counting distinct pixel clusters.

    Implementing the Algorithm in Code

    Example Code and Explanation

    Below is a simplified implementation of the number of islands algorithm using a DFS approach:

    def num_islands(grid):
        if not grid:
            return 0
    
        def dfs(x, y):
            if x < 0 or x >= len(grid) or y < 0 or y >= len(grid[0]) or grid[x][y] == '0':
                return
            grid[x][y] = '0'
            dfs(x + 1, y)
            dfs(x - 1, y)
            dfs(x, y + 1)
            dfs(x, y - 1)
    
        count = 0
        for i in range(len(grid)):
            for j in range(len(grid[0])):
                if grid[i][j] == '1':
                    dfs(i, j)
                    count += 1
    
        return count
    

    This function starts by defining a depth-first search to explore the islands. It checks for boundaries and water cells to avoid revisiting. The main loop iterates through the grid, using DFS to mark visited land cells, ensuring each island is counted once, and returns the total count.

  • Understanding the Logarithm Function: logn

    Understanding the Logarithm Function: logn

    The logarithm function, commonly expressed as logn, plays a pivotal role in mathematics and computer science. It is widely used to simplify complex multiplicative tasks and is integral to understanding algorithm efficiency. This article delves into the essence of the logarithm function, its properties in algorithmic contexts, and its practical applications across various fields.

    What is the logn Function?

    The logn function represents the logarithm of a number n to a specified base. In most computer science contexts, the base is typically 2, noted as log2n. The logarithm of a number is the exponent to which the base must be raised to produce that number. For example, log28 equals 3 because 23 = 8. This function is instrumental in converting multiplicative processes into additive ones, simplifying complex calculations.

    Properties of logn in Algorithms

    The logn function is crucial in algorithm analysis, especially in evaluating time complexity. Algorithms with logarithmic time complexity, denoted as O(logn), are highly efficient as they significantly reduce the number of operations needed to process data.

    One primary property is its ability to break down problems through repeated halving. Binary search algorithms, for instance, leverage this property to efficiently search sorted data by dividing the dataset in half repeatedly until the target is found. This results in a time complexity of O(logn), demonstrating optimal performance compared to linear or quadratic approaches.

    Another important property is its additive nature in the context of multiplied numbers. If two numbers are multiplied, their logarithms add up. This property is beneficial when dealing with large datasets, as it simplifies multiplicative operations to additions, which are computationally less expensive.

    Practical Applications of logn

    The logarithm function, logn, finds practical use in several areas:

    • Data Structures: Logarithms optimize operations in data structures such as balanced trees. For instance, search, insert, and delete operations in balanced binary search trees, like AVL or Red-Black trees, operate with O(logn) complexity, ensuring efficiency even with large datasets.
    • Algorithm Design: Divide and conquer algorithms frequently use logarithmic concepts. QuickSort and MergeSort, for instance, utilize these principles to achieve a time complexity of O(n logn), which is optimal for sorting large datasets.
    • Information Theory: Logarithms help quantify information. The concept of information entropy uses logn to measure the uncertainty or surprise associated with random variables, crucial in fields like cryptography and data compression.
    • Complexity Analysis: Logarithms aid in evaluating complexity beyond just time. Space complexity, particularly in recursive algorithms, often involves logarithmic calculations to determine memory usage efficiency.

    In sum, the logn function is indispensable in optimizing and analyzing complex systems. Its properties and applications underscore its importance in computational efficiency and practical problem-solving across multiple domains.

  • What is Hashing in Data & Systems?

    What is Hashing in Data & Systems?

    Hashing is a fundamental concept in computer science and data systems, serving as a cornerstone for efficient data retrieval and storage. By transforming input data into a fixed-size value or hash code, hashing simplifies data management across various applications. Its utility extends from database systems to digital security, making it a crucial component of modern computing environments.

    What is Hashing?

    At its core, hashing is a technique used to convert data of arbitrary size into a fixed-size string of characters, which is typically a hash code. This transformation process is executed by a hash function, which takes input data, processes it, and outputs a consistent hash value. Importantly, hashing functions are designed to produce unique hash codes for unique data inputs, ensuring each piece of data can be distinctly identified.

    How Does Hashing Work?

    Hashing employs a hash function that processes input data to generate a hash code. A well-designed hash function will ensure that even minor changes in the input data result in drastically different hash codes, minimizing the chances of collisions—when two different inputs produce the same hash code. A common example of a hash function is the SHA-256 algorithm, which outputs a 256-bit hash value irrespective of the input size.

    Hash functions are integral to data structures like hash tables, where they expedite data retrieval by allowing instant access to data values via their associated hash codes. In practice, when searching for a piece of data, the hash function computes the hash code, which is then used to quickly locate the desired data, significantly boosting retrieval speeds compared to linear search methods.

    Applications of Hashing

    Hashing finds applications across numerous domains, enhancing both functionality and security. In database management, hashing accelerates data retrieval, as hash tables allow for constant time complexity access under ideal conditions. This efficiency is especially beneficial in environments handling large datasets, such as cloud databases and big data systems.

    In cybersecurity, hashing plays a vital role in integrity verification and password storage. Hash functions are used to encrypt passwords, ensuring that even if a database is compromised, the actual passwords remain safe, as reverse-engineering the hash code to retrieve the original password is computationally challenging. Moreover, hashing is used in digital signatures to ensure that data has not been altered in transit, maintaining data integrity.

    Why is Hashing Important?

    Hashing’s importance lies in its ability to manage and secure data efficiently. By facilitating quick data access, hashing optimizes system performance and user experience, particularly in applications requiring frequent data lookups. Its robustness against data tampering and security breaches makes it indispensable in protecting sensitive information across digital platforms.

    Hashing also supports other complex operations, such as data verification and integrity checks, which are critical in maintaining reliable systems. In areas like blockchain technology, hashing ensures the immutability of transactions, providing a secure and transparent ledger system.

    Overall, hashing is a versatile tool in the digital age, underpinning much of the reliability and security that modern computing demands. Its capabilities in fast data management and robust security measures continue to drive its adoption in innovative technologies and applications.

  • Understanding Depth-First Search (DFS) Algorithm

    Understanding Depth-First Search (DFS) Algorithm

    Depth-First Search (DFS) is a fundamental algorithm used for traversing or searching tree or graph data structures. The algorithm starts at the root node and explores as far as possible along each branch before backtracking. This approach allows it to efficiently handle problems that require exhaustive searches of all nodes and paths in a network.

    What is Depth-First Search (DFS)?

    Depth-First Search (DFS) is a graph traversal technique that explores nodes and edges of a graph deeply, moving forward until it reaches a node with no unvisited adjacent nodes. At this point, it backtracks and continues to explore other branches. This methodology of exploring as deeply as possible along each branch before backtracking makes DFS a powerful tool in various computational applications.

    How Does the DFS Algorithm Work?

    The DFS algorithm works by utilizing a stack data structure, either implicitly via function recursion or explicitly by maintaining a stack of nodes. The basic steps of the DFS algorithm are as follows:

    1. Start at the root node (or any arbitrary node in the case of a graph).
    2. Mark the starting node as visited and push it onto the stack.
    3. While the stack is not empty, pop the top node from the stack.
    4. For each adjacent node of the node popped from the stack, check if it has been visited:
      • If not visited, mark it as visited and push it onto the stack.
    5. Repeat the process until all nodes are visited and the stack is empty.

    This process ensures that each vertex is explored fully before moving on to the next one, allowing DFS to effectively search through graphs and trees.

    Applications of Depth-First Search

    DFS is used in numerous applications due to its methodical approach to graph traversal. Some of the key applications include:

    • Pathfinding: DFS can determine a path between two nodes in a graph, useful in network routing and puzzle solving.
    • Topological Sorting: In directed graphs, DFS helps in ordering nodes linearly based on dependencies, commonly used in scheduling tasks.
    • Detecting Cycles: DFS can detect cycles in graphs, which is crucial for applications like deadlock detection in operating systems.
    • Finding Connected Components: In an undirected graph, DFS can identify all connected components, grouping nodes based on connectivity.

    DFS vs. Breadth-First Search: Key Differences

    While both DFS and Breadth-First Search (BFS) are graph traversal algorithms, they differ in their approach and use cases. Here are some key differences:

    • Traversal Method: DFS uses a stack and explores as deeply as possible along a branch, whereas BFS uses a queue and explores all neighbors of a node before moving to the next level.
    • Space Complexity: DFS has a lower space complexity compared to BFS, particularly in dense graphs, because DFS only needs to store a single path whereas BFS stores all nodes at the current level.
    • Use Cases: DFS is preferred for scenarios requiring exploration of all possible paths, such as puzzles or maze-solving, whereas BFS is ideal for finding the shortest path in unweighted graphs.
    • Cycle Detection: DFS can easily detect cycles using backtracking, which is not as straightforward in BFS.

    Understanding these differences helps in selecting the right algorithm for specific problems, ensuring efficient and effective graph traversal and problem-solving.

  • Understanding the Union-Find Algorithm

    Understanding the Union-Find Algorithm

    The union-find algorithm, also known as the disjoint-set data structure, is a crucial component in the field of computer science, particularly in the realm of network connectivity. This algorithm efficiently handles the dynamic connectivity problem, which involves determining whether two elements are in the same connected component and merging components when needed. Its efficiency stems from an elegant combination of operations that ensure union and find operations can be executed in nearly constant time.

    What is the Union-Find Algorithm?

    The union-find algorithm is a data structure that keeps track of a partition of a set into disjoint subsets. It provides two primary operations: find and union. The find operation identifies the subset a particular element is part of, while the union operation merges two subsets into a single subset. This algorithm is particularly renowned for its ability to manage these operations efficiently, even as the number of elements grows large.

    The algorithm is often implemented using trees, where each subset is represented by a tree and each element points to a parent. The root node of each tree serves as the representative of the subset. In practice, the algorithm supports a technique called path compression, where the find operation flattens the structure of the tree whenever it is executed, ensuring that future operations are faster. Another optimization is the union by rank, which attaches the shorter tree under the root of the taller tree, minimizing the height of the trees involved.

    How Does the Union-Find Data Structure Work?

    The workings of the union-find data structure can be broken down into two primary operations: find and union.

    • Find Operation: The find operation determines the root of the tree containing a specific element. Using path compression, it traverses up the tree to find the root and makes each node on the path point directly to the root. This operation ensures that trees remain shallow, thus speeding up subsequent operations.
    • Union Operation: The union operation merges two different sets. This is accomplished by linking the roots of the two trees. The union by rank ensures that the tree remains balanced by always attaching the shorter tree to the taller tree. This approach reduces the maximum depth of the trees, leading to more efficient find operations.

    By combining path compression and union by rank, the union-find algorithm achieves a time complexity of nearly O(1) for both union and find operations, making it highly efficient for large datasets.

    Real-World Applications of the Union-Find Algorithm

    The union-find algorithm finds numerous applications across various domains due to its efficiency in managing dynamic connectivity. Some of the notable applications include:

    • Network Connectivity: In computer networks, the algorithm is used to manage dynamic connections between nodes, determining whether two nodes are in the same network or need to be connected.
    • MST (Minimum Spanning Tree) Algorithms: The algorithm is integral to Kruskal’s algorithm for finding the minimum spanning tree of a graph. It helps efficiently determine whether adding an edge will form a cycle in the growing spanning tree.
    • Image Processing: In image segmentation, the union-find algorithm helps in identifying and merging connected components within an image, which is crucial for object detection and recognition.
    • Social Network Analysis: It is used to find communities or clusters within social networks, identifying groups of individuals that are all connected to each other.

    These applications highlight the versatility of the union-find algorithm, underscoring its importance in solving complex problems involving connectivity and component merging.

  • Recursion vs Iteration: Choosing the Right Approach

    Recursion vs Iteration: Choosing the Right Approach

    In the realm of computer science, understanding the concepts of recursion and iteration is crucial for devising efficient algorithms. These approaches, while functionally aimed at solving problems, differ significantly in their execution and application. A closer examination reveals when and why one method might be preferred over the other, offering clarity for developers aiming to optimize their code.

    What are recursion and iteration?

    Recursion is a method where a function calls itself as a subroutine. This technique involves breaking down a problem into smaller instances of the same problem, until reaching a base case that can be solved directly. Recursion is often used for tasks like navigating hierarchical data structures or implementing complex algorithms such as quicksort.

    Iteration, on the other hand, involves using loops to repeat a block of code until a specified condition is met. Commonly implemented with structures like for, while, or do-while loops, iteration is particularly effective in scenarios where the number of repetitions is known, such as processing data arrays or performing repeated calculations.

    How do recursion and iteration differ?

    The primary difference between recursion and iteration lies in their approach to repetition. Recursion handles repetition through repeated function calls, leading to a more expressive and cleaner code for inherently recursive problems, like traversing tree structures. However, recursion can lead to increased memory usage due to function call overhead and stack depth limitations.

    Iteration, in contrast, maintains state through variables and control structures, which can make it more efficient in terms of memory use. Iterative solutions generally use less overhead, as they do not involve the call stack, making them faster for problems with a large number of repetitions.

    When should you use recursion?

    Recursion is advantageous when dealing with problems that can be naturally divided into similar subproblems. For instance, in algorithms like the Fibonacci sequence or factorial calculations, recursion provides a straightforward solution. Additionally, it is useful in scenarios involving tree traversal or backtracking algorithms, where the problem’s solution involves exploring various paths or branches of a data structure.

    Recursion shines when code readability and simplicity are prioritized, especially in problems that are inherently recursive and where performance constraints are not a concern. It allows for a more elegant implementation, often closely resembling the mathematical definition of the problem.

    When is iteration the better choice?

    Iteration is often preferred in cases where performance and memory efficiency are critical. For example, when processing large datasets or performing operations that require constant updating of a data structure, iteration is more practical due to its lower overhead and reduced memory consumption.

    Tasks like sorting large arrays, iterating over lists, or performing repeated calculations benefit from the efficiency of iteration. Its straightforward implementation using loops makes it a robust choice for problems where the number of iterations is predetermined or easily calculated.

    In conclusion, the choice between recursion and iteration depends on the problem at hand, desired efficiency, and the importance of code readability. Understanding these differences helps developers make informed decisions, optimizing their code for both performance and clarity.