Support Vector Machines (SVMs) are a powerful tool in the field of machine learning used for classification and regression tasks. They are particularly effective in high-dimensional spaces and are known for their ability to manage both linear and non-linear data. By finding the optimal hyperplane that separates classes, SVMs ensure robust data classification. This article delves into the workings of SVMs, their applications, and the benefits they offer in machine learning.
What are Support Vector Machines?
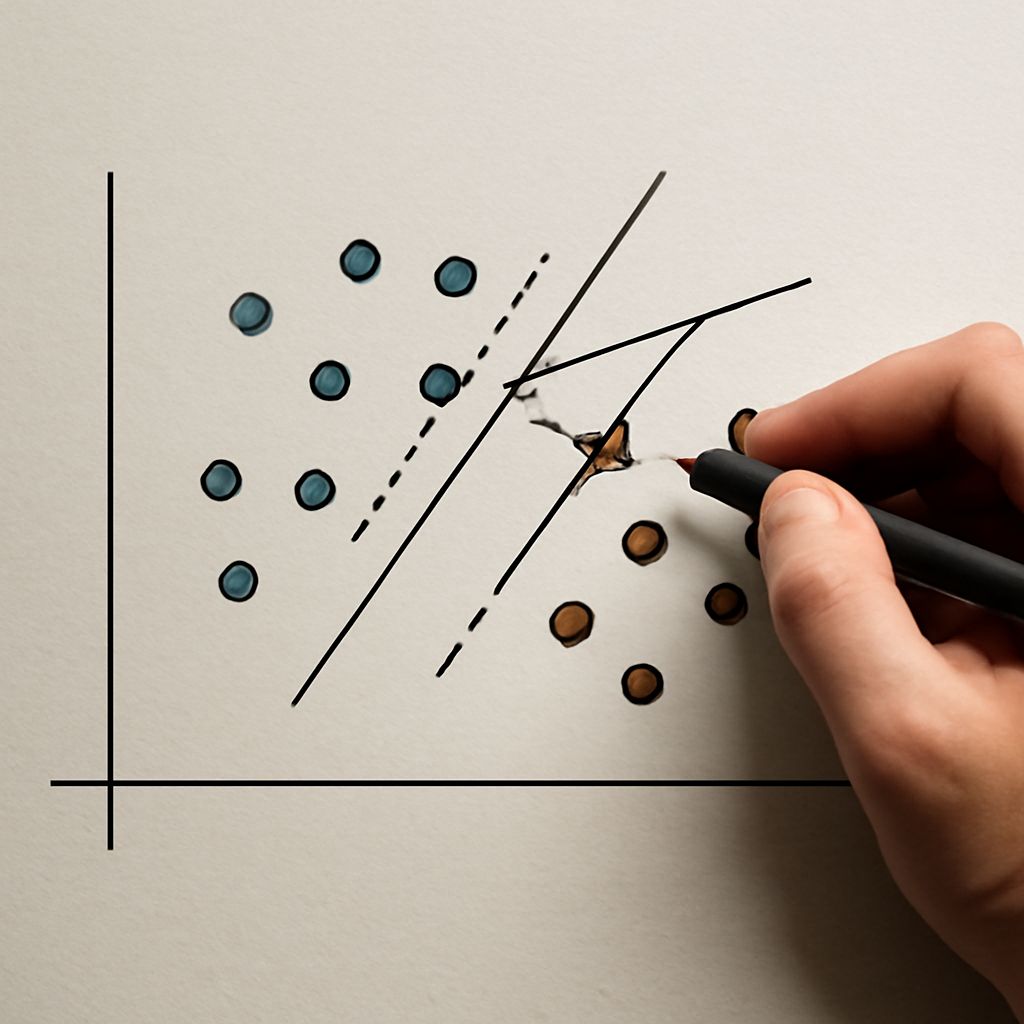
Support Vector Machines are supervised learning models used for classification and regression analysis. They operate by identifying a decision boundary—or hyperplane—that best separates data into different classes. In essence, SVMs aim to create a boundary with the maximum margin between classes, which enhances the model’s accuracy and generalization ability.
How Do SVMs Work?
SVMs work by transforming the input data into a high-dimensional space where a linear separation is feasible. The process involves identifying support vectors, which are the data points closest to the hyperplane and are crucial in defining the position and orientation of the hyperplane. By using kernel functions, SVMs can handle non-linear data transformation, making them versatile for a variety of datasets. The common kernels include linear, polynomial, radial basis function (RBF), and sigmoid.
Applications of SVMs in Machine Learning
SVMs have a wide range of applications in machine learning. In the field of text categorization, SVMs are employed to classify documents into predefined categories, such as spam detection in emails. Image recognition is another area where SVMs excel, particularly in facial recognition systems where they help differentiate between various facial features. Additionally, SVMs are used in bioinformatics for tasks like protein classification and cancer diagnosis, where they analyze complex biological data.
Benefits of Using SVMs
The benefits of using SVMs are numerous. They are effective in high-dimensional spaces, making them suitable for applications where the number of dimensions exceeds the number of samples. SVMs are also memory efficient, as they use a subset of training points to form the decision function. They provide versatility through different kernel functions, allowing them to adapt to linear and non-linear data. Moreover, SVMs offer robust performance with clear margins of classification, enhancing prediction accuracy.