Author: Amber Colvin

  • How to Read a JSON File in Python

    How to Read a JSON File in Python

    JSON, or JavaScript Object Notation, is a lightweight data interchange format widely used for its simplicity and readability. In this guide, you’ll learn how to read a JSON file using Python, a powerful and versatile programming language. By following these steps, you can efficiently handle and utilize JSON data in your projects.

    What is a JSON File?

    A JSON file is a text file containing data in a structured format. It uses key-value pairs organized within braces and supports complex nested data structures. JSON is language-independent, making it a popular choice for data exchange between servers and web applications.

    Setting Up Your Python Environment

    Before reading a JSON file, ensure your Python environment is set up correctly. Install Python from the official website and verify the installation by running python --version in your terminal or command prompt. Additionally, ensure you have the json module, which comes with Python’s standard library.

    Reading a JSON File with Python

    To read a JSON file in Python, follow these steps:

    1. Open the JSON File: Use Python’s built-in open() function to open your JSON file. For example:
      with open('data.json', 'r') as file:
    2. Load the JSON Data: Use the json.load() method from the json module to parse the file content. For example:
      data = json.load(file)
    3. Access the Data: Once loaded, access the data using standard Python data types. JSON objects translate to Python dictionaries, and JSON arrays become lists.
      print(data['key'])

    Practical Examples and Use Cases

    Understanding how to read a JSON file opens up numerous possibilities in handling data-driven tasks. Here are some practical examples and use cases:

    • Data Analysis: Use JSON data in Python to perform complex data analysis. Libraries like pandas can read JSON files directly, allowing for extensive data manipulation.
    • Web Development: JSON is often used in web development to transmit data between a server and web applications. Parsing JSON files in Python helps create dynamic content and APIs.
    • Configuration Files: Many applications use JSON files for configuration. Python scripts can read these files to customize application behavior based on user preferences.
    • Machine Learning: JSON can store training data and model parameters. Python’s compatibility with JSON helps streamline the workflow in machine learning projects.

    By mastering how to read a JSON file in Python, you enhance your ability to work with data more efficiently and effectively across various applications.

  • Common Programming Problems and Solutions

    Common Programming Problems and Solutions

    Programming is a rewarding yet challenging field. Navigating programming problems efficiently can enhance your coding skills and boost productivity. This article delves into common programming problems, strategies to overcome them, and real-world examples for practical understanding.

    What are common programming problems?

    Common programming problems often include syntax errors, runtime errors, logic errors, and performance issues. Syntax errors occur when code violates the rules of the programming language. Runtime errors happen during code execution, leading to unexpected crashes. Logic errors produce incorrect outcomes despite the code running without interruption. Performance issues involve inefficient algorithms or resource-heavy processes leading to slow execution times.

    How can I identify the root cause of a programming problem?

    Identifying the root cause of a programming problem begins with thorough debugging. Utilize debugging tools to trace code execution line by line. Analyze error messages for clues about the issue. Test the code with various input values to pinpoint where it fails. Reviewing the documentation and understanding the problem context can also provide insights into potential causes.

    What are effective strategies for solving programming problems?

    Effective problem-solving strategies include breaking down the problem into smaller parts, using pseudocode, and adopting a test-driven development approach. Breaking the problem into smaller components makes it easier to understand and manage. Writing pseudocode helps in visualizing the logic before implementation. Test-driven development ensures code correctness by writing tests prior to coding the solution itself. Furthermore, leveraging version control systems, such as Git, aids in tracking changes and reverting to previous states if necessary.

    Can you provide examples of programming problems and their solutions?

    Consider a common problem: sorting an array of numbers. A simple and effective solution is the quicksort algorithm, which efficiently sorts data by partitioning the array and recursively sorting the partitions. Another example is dealing with file input/output operations. Ensuring proper error handling and resource management prevents issues like file corruption. Additionally, solving recursive problems, such as calculating Fibonacci numbers, can be achieved by using memoization to enhance performance by caching previously computed results.

    By understanding common programming problems and applying structured strategies, programmers can enhance their problem-solving skills and create more efficient and robust code.

  • Front End vs Back End Developer: Key Differences Explained

    Front End vs Back End Developer: Key Differences Explained

    In web development, understanding the roles of front end and back end developers is crucial. Each role plays a vital part in creating websites and applications but focuses on different aspects. This article explores the main differences between these two roles, their responsibilities, and how they collaborate to deliver seamless digital experiences.

    What Does a Front End Developer Do?

    Front end developers are responsible for the user-facing side of applications. They focus on creating the visual elements that users interact with directly. This includes layout, design, and interactivity using technologies like HTML, CSS, and JavaScript. Their work ensures the website looks appealing and functions smoothly across different devices and browsers.

    Key skills for front end developers include proficiency in responsive design, understanding user experience (UX) principles, and familiarity with frameworks like React or Angular. These skills enable them to build engaging interfaces that enhance user satisfaction.

    What Are the Responsibilities of a Back End Developer?

    Back end developers handle the server side of applications. They focus on database interactions, server logic, and application architecture. Their role is to ensure that all the behind-the-scenes components work together effectively to deliver data and functionality to the front end.

    Key technologies used by back end developers include server languages like Python, Ruby, Java, and PHP, as well as database management systems such as MySQL or MongoDB. They also work with APIs to enable communication between different parts of the application.

    Strong problem-solving skills and understanding complex algorithms are essential for back end developers, as they often deal with data processing, storage, and security.

    How Do Front End and Back End Developers Collaborate?

    Collaboration between front end and back end developers is crucial for building efficient and functional web applications. Both roles need to communicate effectively to align the technical requirements and user needs.

    • API Integration: Back end developers create APIs that front end developers use to fetch data and display it to users. Proper documentation and clear communication ensure seamless integration.
    • Design Alignment: Front end developers need to understand the data structure and logic provided by the back end. This helps them to implement designs that accurately reflect the application’s functionality.
    • Testing and Debugging: Both teams work together to test the application for bugs and performance issues. Collaborative testing ensures that any issues are resolved quickly and efficiently.

    Effective collaboration results in a cohesive product that meets user expectations and performs reliably, highlighting the importance of both front end and back end developers in the web development process.

  • Understanding Regex Special Characters

    Understanding Regex Special Characters

    Regex, or regular expressions, are powerful tools used in programming and data processing to match patterns within text. At the heart of regex are special characters that serve as the building blocks for crafting complex search patterns. Understanding these characters is essential for anyone looking to enhance their algorithmic skills, particularly in data-driven environments.

    What Are Regex Special Characters?

    Regex special characters are symbols that carry special meanings in pattern matching tasks. Unlike regular characters, these symbols allow users to perform more precise searches and manipulations within strings. Some of the most commonly used special characters include:

    • Dot (.): Matches any character except a newline.
    • Asterisk (*): Matches zero or more occurrences of the preceding element.
    • Plus (+): Matches one or more occurrences of the preceding element.
    • Question Mark (?): Matches zero or one occurrence of the preceding element.
    • Brackets ([]): Matches any one character enclosed within the brackets.
    • Backslash (\\): Escapes a special character, making it a literal.

    How to Use Regex Special Characters

    Using regex special characters involves understanding the context of your search and constructing patterns accordingly. Start by defining the element you wish to match and then refine your search with special characters:

    • To match any character, use the dot symbol. For example, “a.c” matches “abc”, “a2c”, and “a-c”.
    • To find multiple occurrences, apply the asterisk or plus. “go*” finds “g”, “go”, and “goo”, while “go+” requires at least one “o”.
    • To create optional patterns, the question mark is utilized. “colou?r” finds both “color” and “colour”.
    • Use brackets to specify a set of possible characters. “[abc]” matches “a”, “b”, or “c”.
    • The backslash is essential for handling reserved characters. To match a literal dot, use “\\.”

    Common Examples in Algorithms

    Regex is extensively used in algorithms for tasks such as input validation, data parsing, and search optimization. Here are a few examples:

    • Email Validation: A common regex pattern checks the structure of an email. This typically includes matching alphanumeric characters, the “@” symbol, and a domain. Example: ^[a-zA-Z0-9_.+-]+@[a-zA-Z0-9-]+\.[a-zA-Z0-9-.]+$.
    • URL Parsing: Regex helps in extracting parts of a URL such as protocol, domain, and path. Example: ^(https?:\/\/)?([\da-z.-]+)\.([a-z.]{2,6})([/\w .-]*)*\/?$.
    • Text Search and Replace: Finding and replacing patterns within text files using regex can automate large-scale text edits efficiently.

    Tips for Effective Regex Implementation

    Implementing regex effectively requires practice and an understanding of both the problem at hand and regex syntax. Here are some tips:

    • Test Regularly: Use online tools or integrated development environment (IDE) plugins to test your regex patterns in real-time.
    • Keep It Simple: Start with simple patterns and gradually build complexity. Over-complicated regex can become difficult to understand and maintain.
    • Document Your Patterns: Comment on your regex patterns within your codebase to explain their purpose, making future maintenance easier.
    • Consider Performance: Regex can impact processing speed, especially with large datasets. Optimize patterns to reduce unnecessary complexity.

    Understanding regex special characters and their applications in algorithms can unlock powerful data processing capabilities. Mastering these tools opens new avenues for efficient and precise text manipulation.

  • Tic Tac Toe Code for a Complete Two-Player Game

    Tic Tac Toe Code for a Complete Two-Player Game

    Build the game around a nine-cell array, a current player, and a result. Each valid move updates the array, checks for a winning line or draw, and then changes the player if play continues. The code for tic tac toe below keeps those rules separate from the browser display, so you can test the JavaScript game by playing it or by calling the rule functions directly.

    Tic Tac Toe JavaScript: A Complete Example

    Save the following as index.html and open it in a browser. Two people take turns on the same device; X always starts. Each square is a button, so it works with a keyboard as well as a pointer. The status line announces whose turn it is and reports the outcome.

    <!doctype html>
    <html lang="en">
    <head>
      <meta charset="utf-8">
      <meta name="viewport" content="width=device-width, initial-scale=1">
      <title>Tic tac toe</title>
      <style>
        body { font-family: sans-serif; margin: 2rem; }
        #board { display: grid; grid-template-columns: repeat(3, 4rem); gap: .25rem; }
        #board button { width: 4rem; height: 4rem; font-size: 2rem; }
        #restart { margin-top: 1rem; }
      </style>
    </head>
    <body>
      <h1>Tic tac toe</h1>
      <p id="status" aria-live="polite"></p>
      <div id="board" aria-label="Game board"></div>
      <button id="restart" type="button">Restart</button>
      <script>
        const lines = [
          [0, 1, 2], [3, 4, 5], [6, 7, 8],
          [0, 3, 6], [1, 4, 7], [2, 5, 8],
          [0, 4, 8], [2, 4, 6]
        ];
    
        function newGame() {
          return { board: Array(9).fill(""), player: "X", result: "" };
        }
    
        function outcome(board) {
          for (const [a, b, c] of lines) {
            if (board[a] && board[a] === board[b] && board[a] === board[c]) {
              return board[a];
            }
          }
          return board.every(cell => cell !== "") ? "draw" : "";
        }
    
        function move(game, index) {
          if (game.result || !Number.isInteger(index) || index < 0 ||
              index > 8 || game.board[index] !== "") return game;
          const board = [...game.board];
          board[index] = game.player;
          const result = outcome(board);
          return {
            board,
            player: result ? game.player : (game.player === "X" ? "O" : "X"),
            result
          };
        }
    
        const boardElement = document.querySelector("#board");
        const status = document.querySelector("#status");
        let game = newGame();
        const buttons = Array.from({ length: 9 }, (_, index) => {
          const button = document.createElement("button");
          button.type = "button";
          button.addEventListener("click", () => {
            game = move(game, index);
            render();
          });
          boardElement.append(button);
          return button;
        });
    
        function render() {
          buttons.forEach((button, index) => {
            const mark = game.board[index];
            button.textContent = mark;
            button.setAttribute("aria-label", `Square ${index + 1}: ${mark || "empty"}`);
          });
          status.textContent = game.result === "draw" ? "Draw!" :
            game.result ? `${game.result} wins!` : `${game.player}'s turn`;
        }
    
        document.querySelector("#restart").addEventListener("click", () => {
          game = newGame();
          render();
        });
        render();
      </script>
    </body>
    </html>
    

    The tic tac toe code creates nine buttons once, then updates their labels from the current state. Pressing an occupied square leaves the board and player unchanged. After a win or draw, later clicks also leave the result intact until Restart creates a fresh game.

    Model the board and the turns

    The array stores the board in reading order: indexes 0, 1, and 2 are the top row, and 6, 7, and 8 are the bottom row. An empty string means a square is available. X and O are ordinary strings, so the display can use the same values as the rules.

    In this tic tac toe javascript example, newGame() returns a new array, sets X as the first player, and clears the result. Keeping the result in state matters: an apparently empty square can remain after a win, but it is no longer a legal move. A separate flag is unnecessary because a nonempty result already tells the move function that the round has ended.

    The tic tac toe code checks an index before modifying anything. It rejects a finished game, a non-integer or out-of-range index, and an occupied square. When a move is valid, it copies the array before placing the mark. Returning a new state makes it easier to compare the old and new positions while testing. In the tic tac toe code, an invalid move returns the original state, including the current player. That makes a second click on the same square a no-op instead of secretly consuming a turn. The browser handler can render after either case because the state remains the single source of truth.

    Check all eight lines

    There are three rows, three columns, and two diagonals. The lines array lists their indexes. For each line, outcome() first requires a nonempty starting cell and then compares all three cells. This prevents three empty squares from being mistaken for a win.

    The tic tac toe javascript rules check a win before checking for a full board. That order matters on the ninth move: the final mark can both fill the board and complete a line. If no line wins and every cell is filled, the result is draw. Otherwise an empty result means the game continues, and move() switches the player.

    The tic tac toe code represents a win with the winning mark, so the interface can announce either X wins! or O wins!. It keeps the final player unchanged after an outcome, though the display uses the result rather than the player to name the winner. For a larger project you could return richer result data, including the indexes of the winning line.

    Keep the display separate from the rules

    The game logic does not read a button’s text or write to the page. It receives state and an index, then returns state. render() does the opposite job: it reads state and updates the DOM. This separation lets the same rules support another interface and makes a JavaScript tic tac toe game easier to debug when the display and the board disagree.

    The buttons stay focusable, including occupied squares, but the rule function ignores invalid moves. Their accessible labels identify the square and mark, and the live status reports changes. The Restart button replaces all state, then renders the empty board and X’s turn. It does not need to create nine more buttons or attach the listeners again.

    Test a win, a draw, and a repeated move

    Number the squares from one to nine in reading order for these manual checks. Restart between sequences; the players alternate automatically.

    • Win: select 1, 4, 2, 5, 3. X completes the top row. The status should report X as the winner, and a later click should change nothing.
    • Draw: select 1, 2, 3, 5, 4, 6, 8, 7, 9. The board fills without a line; the status should say Draw!.
    • Repeated move: select 1 twice. The second selection must leave X in that square and keep O as the next player. Then choose another square and confirm O appears.

    For a JavaScript version of tic tac toe, also test a column and a diagonal win, then restart after each result. These paths exercise the same line table from different directions. For a direct test of the JavaScript tic tac toe logic, open the browser console and call outcome(["X", "", "O", "X", "O", "", "X", "", ""]). It should return "X" for the first column. An empty array of nine empty strings should return an empty result; use Array(9).fill("") to create it. Try Tab and Enter to confirm that each button can be reached and activated without a mouse.

    This tic tac toe game code has no computer opponent or network state; its two players share the same page. Adding either feature would require deciding how those moves reach the same validation function and how the interface handles a delayed or unavailable opponent.

    Keep this checklist nearby

    • Store nine cells, the active mark, and the result; reset all three for a new round.
    • Reject occupied, invalid, and post-game moves before changing state.
    • Check eight winning lines before declaring a full board a draw.
    • Render from state, announce the result, and test the code for tic tac toe with wins, a draw, and a repeated square.
  • Mastering CSS Transform Origin

    Mastering CSS Transform Origin

    CSS transform origin is a crucial property in web design that allows developers to control the point around which a transformation is applied to an element. Mastering this property can significantly enhance the dynamic and visual appeal of a webpage, giving designers precise control over animations and transformations.

    What is CSS Transform Origin?

    The CSS transform origin property defines the point of origin for a transformation. By default, transformations like rotate, scale, and skew occur around the element’s center. The transform origin property allows developers to set this origin point to any desired position, such as the top-left corner, bottom-right corner, or even a specific pixel or percentage point. This flexibility is vital for creating complex animations and achieving precise alignment in responsive design.

    How to Use CSS Transform Origin

    Using CSS transform origin involves specifying values for the x-axis and y-axis. This can be done using keywords like center, top, bottom, left, and right, or using length values such as px or percentages.

    • Keyword Values: Use keywords for quick alignment. For instance, transform-origin: top left; positions the origin at the top-left corner.
    • Length Values: Specify exact positions with pixels or percentages. For example, transform-origin: 50% 50%; sets the origin to the center (default), while transform-origin: 100px 200px; places it precisely 100 pixels from the left and 200 pixels from the top.

    Practical Examples of CSS Transform Origin

    Consider a rotating image. By changing the transform origin, you can control the pivot point of the rotation:

    
    .image {
      transform: rotate(45deg);
      transform-origin: bottom right;
    }
    

    In this example, the image will rotate around its bottom-right corner, creating a different visual effect compared to using the default center origin.

    Another example is scaling an element, such as a button:

    
    .button {
      transform: scale(1.2);
      transform-origin: top left;
    }
    

    Here, the button scales up from the top-left corner, making it appear to grow outward from that point.

    Common Mistakes and How to Avoid Them

    One common mistake is not setting the transform origin at all, leading to unexpected animation behavior. Always specify an origin when precise control is required, especially in complex animations.

    Another pitfall is using percentages without understanding their relative positioning. Remember that percentages are relative to the element’s size. Misjudging this can cause transformations to appear misaligned or off-center.

    Finally, when using multiple transformations, the order of operations matters. Ensure you’ve considered how transform origin affects each transformation, especially when combined with translate, rotate, or scale in a single transform property.

    By understanding and correctly applying the CSS transform origin, you can achieve professional and visually appealing web designs that behave as expected across various devices and contexts.

  • Understanding Support Vector Machines (SVMs)

    Understanding Support Vector Machines (SVMs)

    Support Vector Machines (SVMs) are a powerful tool in the field of machine learning used for classification and regression tasks. They are particularly effective in high-dimensional spaces and are known for their ability to manage both linear and non-linear data. By finding the optimal hyperplane that separates classes, SVMs ensure robust data classification. This article delves into the workings of SVMs, their applications, and the benefits they offer in machine learning.

    What are Support Vector Machines?

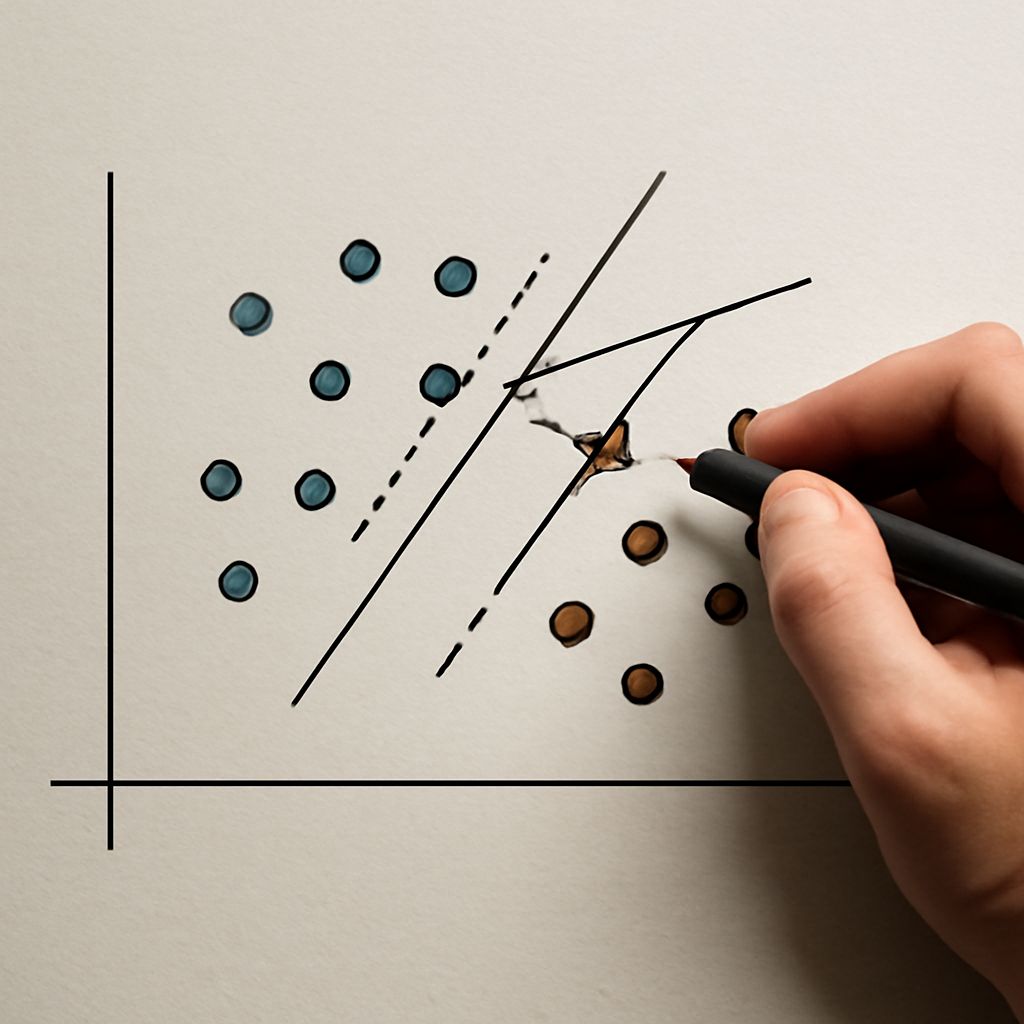
    Support Vector Machines are supervised learning models used for classification and regression analysis. They operate by identifying a decision boundary—or hyperplane—that best separates data into different classes. In essence, SVMs aim to create a boundary with the maximum margin between classes, which enhances the model’s accuracy and generalization ability.

    How Do SVMs Work?

    SVMs work by transforming the input data into a high-dimensional space where a linear separation is feasible. The process involves identifying support vectors, which are the data points closest to the hyperplane and are crucial in defining the position and orientation of the hyperplane. By using kernel functions, SVMs can handle non-linear data transformation, making them versatile for a variety of datasets. The common kernels include linear, polynomial, radial basis function (RBF), and sigmoid.

    Applications of SVMs in Machine Learning

    SVMs have a wide range of applications in machine learning. In the field of text categorization, SVMs are employed to classify documents into predefined categories, such as spam detection in emails. Image recognition is another area where SVMs excel, particularly in facial recognition systems where they help differentiate between various facial features. Additionally, SVMs are used in bioinformatics for tasks like protein classification and cancer diagnosis, where they analyze complex biological data.

    Benefits of Using SVMs

    The benefits of using SVMs are numerous. They are effective in high-dimensional spaces, making them suitable for applications where the number of dimensions exceeds the number of samples. SVMs are also memory efficient, as they use a subset of training points to form the decision function. They provide versatility through different kernel functions, allowing them to adapt to linear and non-linear data. Moreover, SVMs offer robust performance with clear margins of classification, enhancing prediction accuracy.

  • Understanding Merge Sort Pseudocode

    Understanding Merge Sort Pseudocode

    Merge sort is a powerful and efficient sorting algorithm commonly used in computer science. It breaks down a list into smaller sublists until each sublist contains only one element, then merges those sublists to produce a sorted list. The beauty of merge sort lies in its efficiency, especially for large datasets.

    What is Merge Sort?

    Merge sort is a divide-and-conquer algorithm that splits a list into halves, sorts each half, and then merges the sorted halves back together. This process is repeated recursively until the entire list is sorted. The algorithm is known for its stability and efficiency, particularly with larger lists, as it consistently performs in O(n log n) time complexity.

    How Does Merge Sort Work?

    The merge sort algorithm involves two main steps: dividing the unsorted list and merging the sublists. Initially, the list is divided into two halves. These halves are then further divided recursively until single-element sublists are formed, which are inherently sorted. The merging process then begins, where two sorted sublists are combined into a single sorted list. This is done by comparing the smallest elements of each sublist and adding the smallest element to the new list, repeating the process until one sublist is exhausted, and then appending the remaining elements from the other sublist.

    Step-by-Step Guide to Merge Sort Pseudocode

    Understanding the pseudocode for merge sort is crucial for implementing this sorting algorithm. Below is a simple step-by-step guide:

    1. Function Call: Start by calling the merge sort function with the list to be sorted.
    2. Base Case: If the list has one or zero elements, return it as it is already sorted.
    3. Divide: Split the list into two halves.
    4. Recursive Sort: Recursively sort each half by calling the merge sort function on them.
    5. Merge: Merge the two halves back into a single sorted list using the merge function.

    Pseudocode example:

    
    function mergeSort(list):
      if length of list <= 1:
        return list
    
      mid = length of list / 2
      leftHalf = mergeSort(list[0:mid])
      rightHalf = mergeSort(list[mid:])
    
      return merge(leftHalf, rightHalf)
    
    function merge(left, right):
      result = empty list
      while left is not empty and right is not empty:
        if left[0] <= right[0]:
          append left[0] to result
          left = left[1:]
        else:
          append right[0] to result
          right = right[1:]
    
      append remaining elements of left to result
      append remaining elements of right to result
      
      return result
    

    Common Applications of Merge Sort

    Merge sort is widely used in various applications due to its predictable performance and stability. It's particularly useful in scenarios where large datasets need sorting, as it handles large amounts of data efficiently. Some common applications include:

    • External Sorting: Useful for sorting large files stored on disk that don't fit into memory.
    • Inversion Count Problem: Used to count the number of inversions in an array, which can help in determining how far an array is from being sorted.
    • Linked Lists: Efficiently sorts linked lists as it doesn't require random access to elements, unlike quicksort.

    By understanding and implementing merge sort, you can enhance your algorithm toolkit and tackle complex sorting problems with ease.

  • Master Python Quizzes to Test Your Skills

    Master Python Quizzes to Test Your Skills

    Engaging with a Python quiz is an excellent way to test and enhance your programming skills. Whether you’re a beginner or an experienced coder, taking quizzes can help solidify your understanding and reveal areas that need improvement. Here’s how Python quizzes can be a valuable part of your learning journey.

    What Are Python Quizzes?

    Python quizzes are structured assessments designed to evaluate your knowledge of the Python programming language. They typically consist of multiple-choice questions, code snippets, and problem-solving exercises that cover various Python topics, such as syntax, data structures, algorithms, and libraries. These quizzes can be tailored to different skill levels, making them suitable for anyone from novices to seasoned developers.

    How to Prepare for a Python Quiz

    Preparation is key to excelling in a Python quiz. Start by reviewing Python basics such as data types, control structures, functions, and object-oriented programming. Practice writing code to solve common problems and work on small projects to apply your knowledge in real-world scenarios. Utilize online resources and documentation to deepen your understanding of more complex concepts. Regularly solving coding challenges can also sharpen your problem-solving skills.

    Where Can You Find Python Quizzes Online?

    Several online platforms offer Python quizzes, catering to different levels of expertise:

    • Codecademy: Offers interactive quizzes as part of their Python courses, allowing you to test your knowledge immediately after learning new concepts.
    • LeetCode: Provides coding challenges that can serve as quizzes to test your Python programming skills, focusing on algorithms and data structures.
    • HackerRank: Features a variety of Python quizzes that range from basic syntax to advanced topics, with a competitive edge.
    • W3Schools: Provides a straightforward quiz feature that covers the essentials of Python programming.

    These platforms offer a range of quizzes that can help you gauge your proficiency and identify areas for improvement.

    Benefits of Taking Python Quizzes

    Taking Python quizzes offers multiple benefits that contribute to your programming growth:

    • Reinforcement of Learning: Quizzes help reinforce what you’ve learned, ensuring that key concepts remain fresh in your mind.
    • Identification of Knowledge Gaps: By taking quizzes, you can pinpoint areas where your understanding is lacking, allowing you to focus your study efforts on those weaknesses.
    • Development of Problem-Solving Skills: Many Python quizzes include practical coding challenges that enhance your analytical and problem-solving abilities.
    • Increased Confidence: Regularly testing yourself builds confidence in your Python skills, preparing you for real-world programming tasks and job interviews.

    Incorporating Python quizzes into your learning routine can significantly enhance your proficiency and confidence in programming.

  • SQL INSERT INTO: Add Rows With Clear Examples

    SQL INSERT INTO: Add Rows With Clear Examples

    A new row can fail to insert when its values do not match the table’s columns. To insert data into a SQL table, name the columns and provide a value for each one in the same order. An INSERT statement in SQL can add one row or several, while omitted columns can receive defaults.

    The following examples use PostgreSQL and build on one another. Run them in order against a fresh practice database. Other databases support the general idea, but identity columns, default syntax, and ways to return generated IDs differ by dialect.

    Insert Statement SQL Examples: Start With a Table

    Create a small table for tasks:

    CREATE TABLE tasks (
      id integer GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
      title varchar(100) NOT NULL,
      priority integer NOT NULL DEFAULT 1,
      note text
    );
    

    Each row has a generated id, a required title, a required priority that defaults to 1, and an optional note. GENERATED ALWAYS AS IDENTITY is PostgreSQL syntax for an identity column; PostgreSQL generates the ID when it is omitted. A primary key requires unique, non-null values. For the expected IDs below, use this newly created table and run the inserts once in the order shown.

    The SQL INSERT syntax places the target table and columns before VALUES. Each parenthesized group after it supplies the corresponding values. Begin with this SQL INSERT example:

    INSERT INTO tasks (title, priority, note)
    VALUES ('Write tests', 2, 'Cover login');
    

    The result is one row: id 1, title Write tests, priority 2, and note Cover login. Text literals use single quotes; 2 is a number. The database assigns the ID because it is not in the column list. This SQL INSERT INTO statement makes the mapping explicit: first title, then priority, then note.

    Insert more than one row

    A single insert query in SQL can supply several value groups separated by commas:

    INSERT INTO tasks (title, priority, note)
    VALUES
      ('Review logs', 1, 'Check errors'),
      ('Update docs', 3, NULL);
    

    The first group creates ID 2 with priority 1 and the note Check errors. The second creates ID 3 with priority 3 and a missing note. Each group must have the same number of values as the column list and use its order. SQL INSERT INTO VALUES syntax can express a batch in one statement, while still mapping each row independently.

    To inspect the rows after these inserts, run:

    SELECT id, title, priority, note
    FROM tasks
    ORDER BY id;
    

    The query returns IDs 1 through 3 in order. The SQL INSERT row count reported by the client tells you how many rows the command added; compare it with the number you intended to create. Without ORDER BY, row order is not guaranteed. An SQL INSERT command changes the table; the SELECT reads it so you can verify the outcome. Check the actual values as well as the count, because a statement can succeed even when compatible values were supplied in the wrong order. To insert rows into a table with SQL safely, use a small test batch and inspect its result before running a larger one.

    In SQL, add to the table a row specifying only the columns you intend to supply; the next example lets the database fill the rest. A SQL statement that inserts a row can therefore be shorter while still producing a complete record.

    Use defaults and NULL deliberately

    Leave a column out when its defined default is the value you want:

    INSERT INTO tasks (title)
    VALUES ('Plan release');
    

    The resulting row has ID 4, priority 1, and a NULL note. The identity supplies id; the declared default supplies priority. Since note has no explicit default, its default is NULL. Omission and explicit NULL are different choices: a default is used on omission, while explicitly supplying NULL requests a missing value.

    In PostgreSQL, you can also request the default explicitly in an insert statement:

    INSERT INTO tasks (title, priority, note)
    VALUES ('Fix alerts', DEFAULT, NULL);
    

    This creates ID 5 with priority 1 and a NULL note. If you write NULL for priority instead, the insert fails because that column is NOT NULL; NULL does not trigger its default. The insert statement SQL examples here use PostgreSQL’s DEFAULT in the values list, so check your database’s documentation before transferring that form to another dialect.

    A SQL query that inserts data can also provide an explicit value equal to the default, but that hard-codes today’s default into the query. Omitting the column lets the database use its current definition. This difference matters if the schema default later changes.

    Retrieve a generated ID

    In PostgreSQL, append RETURNING when your application needs the generated ID immediately:

    INSERT INTO tasks (title, priority)
    VALUES ('Ship release', 2)
    RETURNING id, title;
    

    On the fresh example table, the result contains ID 6 and title Ship release; the new row also has priority 2 and a NULL note. RETURNING is a PostgreSQL feature whose equivalent differs across database systems. Do not infer an ID by adding one to the previous result: sequences can have gaps, including after failed or rolled-back operations. Ask the database for the value it generated.

    This operation supplies only the data the application owns. The database supplies the identity, and the returned row links the application to the record it just created. If an application accepts user input, use its database driver’s parameterized statements rather than joining input into SQL text.

    Put the insert in a repeatable script

    To reproduce setup in another environment, insert a SQL statement into a migration file managed by your project. A migration containing sample data should have a clear purpose and run after table creation. If the script is run twice, the rows may be duplicated or a constraint may reject the second run; choose a project-specific strategy for repeat execution.

    For a small manual test, insert a SQL query into a script and run it against a practice database. Save the SELECT that checks the result alongside the insert. Keep the SQL statement used for insertion in version control so its intent and changes can be reviewed. An insert query written in SQL is easier to review when the target columns and expected values are visible together. If you add a query that inserts data in SQL to an application, bind external values as parameters through the driver.

    Check the mapping when an insert fails

    The most common mistake is a mismatch between the number or order of columns and values. For example, (title, priority) VALUES ('Audit') has two columns but only one value, so the database reports a count error. Add the missing priority or omit that column to use its default. If the counts match but the database reports a type error, compare each value with the type of its corresponding column.

    Finally, check constraints and quoting. A missing title violates NOT NULL; duplicate explicit primary keys violate uniqueness; text needs single quotes. Read the database’s error, locate the named column or constraint, correct the input, and rerun the insert. When you insert data into a table using SQL, follow it with a SELECT to confirm that the stored values are the ones you intended.