Category: Data & Systems

  • Understanding Bit Masking and Its Applications

    Understanding Bit Masking and Its Applications

    Bit masking is a powerful technique used in computing for manipulating individual bits within a binary number. This method is essential for tasks such as setting, clearing, toggling, and testing bits, and is widely applied in fields like data compression, encryption, and network processing. Understanding bit masking helps in performing efficient and precise operations on data at the bit level.

    What is Bit Masking?

    Bit masking involves using a bitmask, which is a binary number that serves as a template to identify or manipulate specific bits in another binary number. A bitmask can perform operations on data by using bitwise operators such as AND, OR, XOR, and NOT. By applying these operations, you can control which bits are affected by the masking process.

    How Does a Bitmask Work?

    A bitmask works by aligning its bits with the bits of the target data. The chosen bitwise operation determines the effect. For example, using the AND operator with a bitmask can clear certain bits, while the OR operator can set bits. Here’s a simple breakdown of the main operations:

    • AND Operation: Used to clear bits. The bits in the bitmask are set to 1 for the bits you want to preserve in the target number. All other bits are cleared.
    • OR Operation: Used to set bits. The bits in the bitmask are set to 1 for the positions you want to set to 1 in the target number, leaving other bits unchanged.
    • XOR Operation: Used to toggle bits. The bits in the bitmask are set to 1 where you want to flip the corresponding bits in the target number.
    • NOT Operation: Used to invert bits. Each bit in the target number is flipped, but this operator is unary and doesn’t directly use a bitmask.

    Practical Examples of Bit Masking

    Bit masking finds its utility in numerous practical applications. Here are a few examples:

    • Permissions Management: In operating systems, file permissions are often managed using bit masking. Each permission is represented by a bit, and a bitmask can be used to check or alter these permissions efficiently.
    • Data Compression: Bit masking is used to manipulate and compress data by selecting specific bits from larger data structures, thus saving space.
    • Error Detection: In networking, bit masking helps in error detection by isolating and checking specific bits that represent critical information, like checksums.
    • Graphics Programming: In graphics, bit masking can be used for color manipulation and to blend images by targeting specific color bits in pixel data.

    Benefits and Limitations of Bit Masking

    Bit masking offers several advantages, such as speed and efficiency. Operations using bit masks are typically executed very quickly by processors, as they require minimal computational resources. This makes it ideal for applications where performance is crucial, like gaming and real-time systems.

    However, bit masking also has limitations. It requires a good understanding of binary operations and bitwise logic, which can be a barrier for beginners. Moreover, incorrect application can lead to data corruption or unintended behavior in programs. Therefore, careful planning and testing are crucial when implementing bit masking in software development.

    Overall, mastering bit masking can significantly enhance your ability to manipulate data at a low level, providing precision and efficiency in various computing tasks.
  • SQL INTERSECT: Find the Rows Two Queries Share

    SQL INTERSECT: Find the Rows Two Queries Share

    To find values present in both results, put INTERSECT between two SELECT statements. The intersection of SQL query results contains the rows that appear on both sides; start with a small example and inspect each input separately.

    INTERSECT SQL results with a working example

    Imagine two lists of customer IDs: people who attended a workshop and people who downloaded its materials. To intersect SQL results, select the same kind of value from each list. This PostgreSQL example is self-contained, so you can paste it into a query console without creating tables:

    WITH attendees(customer_id) AS (
      VALUES (1), (2), (2), (3)
    ),
    downloaders(customer_id) AS (
      VALUES (2), (2), (2), (4)
    )
    SELECT customer_id FROM attendees
    INTERSECT
    SELECT customer_id FROM downloaders
    ORDER BY customer_id;
    

    The result is one row, 2. Both inputs contain that ID, while 1, 3, and 4 occur on only one side. The repeated 2 still appears once because the SQL INTERSECT operator removes duplicate result rows. The final ORDER BY makes display order explicit; without it, do not rely on the order in which rows appear.

    Replace the CTEs with your own tables once the example makes sense. Run each SELECT alone first, including its filters. Then combine them and compare the shared values with the output. This makes an SQL query intersection easier to debug because you can see whether a missing value was excluded before the set operation ever ran.

    To intersect results in SQL accurately, apply the intended date and status filters to each source before comparing them.

    Match columns by position

    Each input must return the same number of columns, and corresponding positions must have compatible types. The database compares the first selected value on the left with the first on the right, the second with the second, and so on. Names do not establish the pairing. PostgreSQL calls this requirement union compatibility.

    For example, selecting (customer_id, region) on both sides asks for an entire pair to appear in both results. A customer in West on one side and East on the other produces no matching pair, even if the ID is identical. Selecting only the ID changes the question to whether that customer appears in both lists.

    SQL’s INTERSECT operator therefore answers a question about the chosen combination of values. Add a column only when it belongs in the definition of a match.

    When you intersect SQL outputs, check units and meaning as well as data types. An integer customer ID and an integer order ID may be type-compatible but represent different things. If corresponding types differ, use an explicit CAST where it expresses the intended comparison; inspect the converted values before trusting the result. The SQL INTERSECT operator compares the projected rows, not every column in the underlying tables.

    Duplicates and NULL values

    Plain INTERSECT returns distinct shared rows. PostgreSQL also supports INTERSECT ALL: if a row occurs m times on the left and n times on the right, it appears min(m, n) times in the result, as described in the PostgreSQL SELECT reference. Change the operator in the example to INTERSECT ALL and the result contains two rows with 2. There are two copies among attendees and three among downloaders, so two pairs can be accounted for.

    Use the SQL intersection with ALL when repeated occurrences carry meaning, such as matching quantities in two lists. Use the default form when the question is simply which distinct values are shared. For multiple columns, duplication applies to the complete selected row: (2, 'West') and (2, 'East') are different rows.

    NULL deserves a separate test. In SQL Server, the set operator rules treat two NULL values as equal when determining distinct rows. Thus, if both inputs contain a single-column NULL, plain INTERSECT can return one NULL. This differs from an ordinary join condition such as a.id = b.id, where NULL values do not match each other. To exclude unknown IDs from an intersection in SQL, add WHERE customer_id IS NOT NULL to both inputs.

    When a join is the better tool

    Choose the SQL INTERSECT operator for a distinct list of complete rows common to both inputs. Choose INTERSECT ALL where your engine supports it and shared multiplicity matters. Choose a join when you need to bring together columns from both tables, or when the match condition involves a range or another relationship rather than equality of the projected rows.

    For example, a join can pair an attendee with every matching download record and return each download date. That changes the number of rows: two attendee records and three matching download records can produce six combinations. SELECT DISTINCT can collapse projected duplicates, but it does not automatically reproduce the NULL behavior or the multiplicity of INTERSECT ALL. Decide which result you want before replacing SQL’s INTERSECT operator with a join.

    To test an intersection between SQL queries, include a repeated ID and a NULL in your fixture, then compare the output with the intended rules.

    Check the database dialect

    PostgreSQL supports both forms; its reference specifies their duplicate behavior. MySQL supports INTERSECT and INTERSECT ALL beginning with version 8.0.31, according to the MySQL set operations manual. SQL Server documents INTERSECT without an ALL option in its syntax. Check the engine and version before relying on the variant that retains duplicates.

    To intersect SQL query results across dialects, also check type conversion and collation rules. For instance, SQL Server requires comparable types and applies collation precedence to character comparisons. Differences in case sensitivity can affect whether text values match. Parenthesize mixed set operations when the intended grouping needs to be clear, and place the final sort on the combined result.

    If the query fails or returns nothing

    The most likely first failure is a mismatch between the two select lists: a different number of columns, incompatible types, or columns in the wrong order. A database error points toward the first two; a valid query with an unexpectedly empty result can reveal the third. Run each side separately, compare the number, position, type, and actual values of its output columns, then align the projections or cast the values deliberately. Rerun the intersection of the SQL results with a small known matching row before restoring the full filters.

  • How Hard Is It to Learn SQL: A Beginner’s Guide

    How Hard Is It to Learn SQL: A Beginner’s Guide

    Structured Query Language, commonly known as SQL, is a fundamental tool for data management and analysis. For those wondering how hard is it to learn SQL, the answer varies depending on your background and experience. However, with the right approach and resources, learning SQL can be a manageable and rewarding endeavor for beginners and professionals alike.

    What Makes SQL Difficult for Beginners?

    SQL difficulty largely stems from its syntax and logical structure, which can be unfamiliar to those new to programming. Beginners often struggle with understanding how different SQL commands interact with databases. The challenge also lies in mastering the various aspects of data manipulation, such as selecting, inserting, updating, and deleting data using SQL queries. For some, the abstract nature of databases and the necessity of thinking in sets rather than single records pose significant hurdles.

    How Can You Simplify Learning SQL?

    What Resources Are Available?

    To simplify the process of learning SQL, numerous resources can be utilized. Online tutorials and coding platforms, such as Codecademy and Khan Academy, offer interactive lessons that guide you through SQL basics at your own pace. Books like “Learning SQL” by Alan Beaulieu provide structured, comprehensive insights into SQL essentials. For those who prefer video content, platforms like Coursera and Udemy host courses taught by experienced instructors.

    Practical Tips for Mastering SQL

    Practical experience is invaluable when learning SQL. Start by working on small projects, such as building a personal database or contributing to open-source projects. Another effective approach is to practice writing queries using real-world datasets found on websites like Kaggle. Consistent practice helps solidify your understanding and boosts your confidence in using SQL. Additionally, joining online forums or study groups can provide support and facilitate knowledge exchange among peers.

    What Are Common Challenges in Learning SQL?

    Common challenges in learning SQL include understanding complex queries, optimizing performance, and managing database security. Beginners often find it difficult to grasp advanced SQL concepts like joins, subqueries, and indexing. Furthermore, ensuring efficient query performance and comprehending database normalization can be daunting tasks. Addressing these challenges requires patience, practice, and a willingness to delve deeper into database design principles.

    How Long Does It Take to Learn SQL?

    The time it takes to learn SQL can vary significantly based on individual circumstances. For someone with a background in programming or data analysis, it might take about two to three weeks of consistent study to become proficient in basic SQL. Beginners with no prior coding experience might require a month or more to grasp fundamental SQL concepts thoroughly. The key is to maintain a regular learning schedule and apply what you learn through hands-on practice.

  • Understanding Function Block Programming in Industrial Automation

    Understanding Function Block Programming in Industrial Automation

    In the realm of industrial automation, function block programming serves as a crucial tool for engineers and technicians alike, enabling efficient system control and process management. This programming method simplifies complex operations by utilizing modular, reusable blocks to execute specific tasks. Coupled with the graphical representation offered by function block diagrams, it provides a clear and intuitive way to design automated systems.

    What is Function Block Programming?

    Function block programming is a method of coding that uses predefined blocks, each with a specific function, to build a control system. These blocks are interconnected, forming a network that dictates the flow of operations within an industrial process. This approach is particularly beneficial for managing repetitive tasks and streamlining workflows, as it allows for easy adjustments and enhancements.

    How Does a Function Block Diagram Work?

    A function block diagram (FBD) is a graphical representation of the functional relationships between inputs, outputs, and the function blocks themselves. It visually maps out how different components interact and communicate within an automated system. Each block in the diagram performs a specific function, such as logical operations, data processing, or control actions. The simplicity of the diagram helps engineers quickly understand system architecture and troubleshoot issues.

    Benefits of Using Function Block Programming in Automation

    Function block programming offers several advantages in industrial automation:

    • Modularity: Function blocks can be reused across different projects, reducing development time.
    • Scalability: Systems can be easily expanded by adding new blocks without overhauling existing code.
    • Flexibility: Engineers can adapt blocks to suit specific needs, facilitating customization.
    • Ease of Maintenance: The clear structure of function block diagrams simplifies system debugging and updates.

    These benefits make function block programming an appealing choice for complex industrial tasks where efficiency and reliability are paramount.

    Key Components of Function Block Diagrams

    Understanding the main elements of function block diagrams is essential for effective implementation:

    • Function Blocks: The core units that perform specific operations, such as computation, control, or data handling.
    • Connections: Lines that link blocks together, defining the data flow between various operations.
    • Inputs and Outputs: The entry and exit points for data within the system, determining how information is received and transmitted.
    • Parameters: Variables within blocks that can be adjusted to alter their behavior or output.

    By mastering these components, engineers can craft efficient and robust automation systems using function block programming. This approach not only accelerates development but also enhances system reliability and adaptability in industrial settings.

  • Recursion vs Iteration: Choosing the Right Approach

    Recursion vs Iteration: Choosing the Right Approach

    In the realm of computer science, understanding the concepts of recursion and iteration is crucial for devising efficient algorithms. These approaches, while functionally aimed at solving problems, differ significantly in their execution and application. A closer examination reveals when and why one method might be preferred over the other, offering clarity for developers aiming to optimize their code.

    What are recursion and iteration?

    Recursion is a method where a function calls itself as a subroutine. This technique involves breaking down a problem into smaller instances of the same problem, until reaching a base case that can be solved directly. Recursion is often used for tasks like navigating hierarchical data structures or implementing complex algorithms such as quicksort.

    Iteration, on the other hand, involves using loops to repeat a block of code until a specified condition is met. Commonly implemented with structures like for, while, or do-while loops, iteration is particularly effective in scenarios where the number of repetitions is known, such as processing data arrays or performing repeated calculations.

    How do recursion and iteration differ?

    The primary difference between recursion and iteration lies in their approach to repetition. Recursion handles repetition through repeated function calls, leading to a more expressive and cleaner code for inherently recursive problems, like traversing tree structures. However, recursion can lead to increased memory usage due to function call overhead and stack depth limitations.

    Iteration, in contrast, maintains state through variables and control structures, which can make it more efficient in terms of memory use. Iterative solutions generally use less overhead, as they do not involve the call stack, making them faster for problems with a large number of repetitions.

    When should you use recursion?

    Recursion is advantageous when dealing with problems that can be naturally divided into similar subproblems. For instance, in algorithms like the Fibonacci sequence or factorial calculations, recursion provides a straightforward solution. Additionally, it is useful in scenarios involving tree traversal or backtracking algorithms, where the problem’s solution involves exploring various paths or branches of a data structure.

    Recursion shines when code readability and simplicity are prioritized, especially in problems that are inherently recursive and where performance constraints are not a concern. It allows for a more elegant implementation, often closely resembling the mathematical definition of the problem.

    When is iteration the better choice?

    Iteration is often preferred in cases where performance and memory efficiency are critical. For example, when processing large datasets or performing operations that require constant updating of a data structure, iteration is more practical due to its lower overhead and reduced memory consumption.

    Tasks like sorting large arrays, iterating over lists, or performing repeated calculations benefit from the efficiency of iteration. Its straightforward implementation using loops makes it a robust choice for problems where the number of iterations is predetermined or easily calculated.

    In conclusion, the choice between recursion and iteration depends on the problem at hand, desired efficiency, and the importance of code readability. Understanding these differences helps developers make informed decisions, optimizing their code for both performance and clarity.

  • Understanding the Flood Fill Algorithm

    Understanding the Flood Fill Algorithm

    The flood fill algorithm is a fundamental concept in computer graphics and image processing. It serves as the backbone for operations that require region filling, such as painting tools in graphic editors and game development. By understanding this algorithm, programmers and developers can effectively manipulate images and design interactive applications.

    What is the Flood Fill Algorithm?

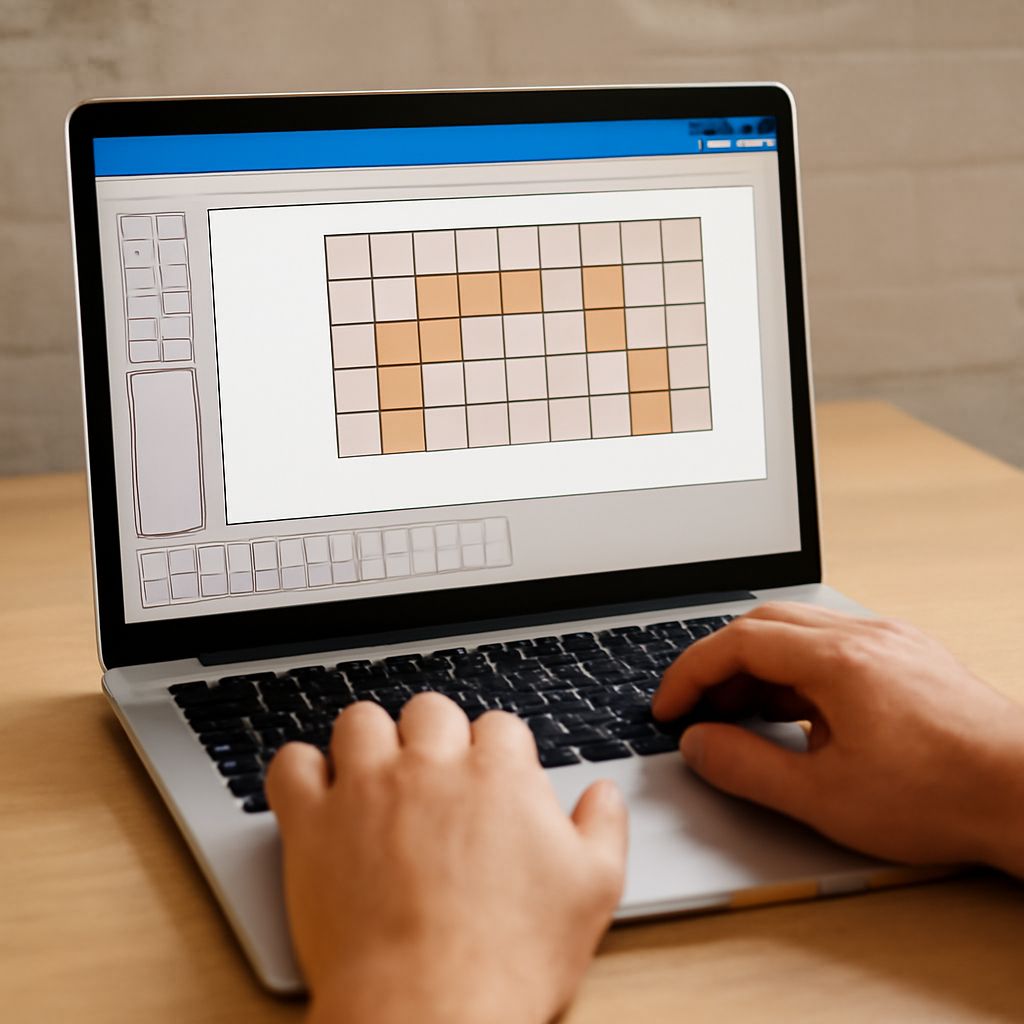
    The flood fill algorithm is a method used to determine and fill contiguous areas of a grid or matrix. It identifies connected pixels or nodes that share the same set of attributes, such as color. Essentially, this algorithm is responsible for changing the attribute of a target area to a new value, uniformly.

    Flood fill is often invoked when there is a need to alter the appearance of a region in an image or to detect boundaries. In simpler terms, it’s what happens when you use a paint bucket tool in a digital painting application to change the color of a whole area.

    How Does the Flood Fill Algorithm Work?

    The workings of the flood fill algorithm can be visualized with a simple analogy: think of it as filling an enclosed area with water. Starting from a seed point, the algorithm spreads to adjacent areas in all possible directions (up, down, left, and right) until it covers the entire connected region.

    There are two main approaches for implementing flood fill:

    • Recursive Approach: This method uses recursion to navigate and fill the grid. It can be easier to implement but may lead to stack overflow issues with large datasets due to deep recursive calls.
    • Iterative Approach: Utilizes a queue or stack to manage the pixels or nodes to visit. This method is more memory-efficient and better handles larger areas without risk of overflow.

    Applications of the Flood Fill Algorithm

    The flood fill algorithm shines in several applications, primarily in the realms of computer graphics and image processing:

    • Paint and Drawing Programs: Used in tools like the paint bucket to fill areas with a specific color.
    • Game Development: Assists in map generation and terrain analysis by filling areas to identify distinct regions or patterns.
    • Image Segmentation: Plays a critical role in dividing an image into regions for analysis or object recognition tasks.
    • Pattern Recognition: Facilitates the identification and isolation of specific patterns in a dataset.

    Implementing the Flood Fill Algorithm

    To implement the flood fill algorithm, the following steps can be followed using either the recursive or iterative method:

    1. Identify the starting point or seed pixel.
    2. Check if the starting pixel is already the target color. If it is, terminate the process.
    3. Use a stack (for iterative) or recursive calls to explore all connected neighbors of the same initial color.
    4. Change the color or attribute of the current pixel or node to the desired new color.
    5. Repeat the process for each neighboring pixel until the entire region is filled.

    Here is a simple pseudo-code for the iterative approach:

    
    function floodFill(image, x, y, newColor):
        initialColor = image[x][y]
        if initialColor == newColor:
            return
        stack = [(x, y)]
        while stack is not empty:
            currentX, currentY = stack.pop()
            if image[currentX][currentY] == initialColor:
                image[currentX][currentY] = newColor
                for each (neighborX, neighborY) in neighbors(currentX, currentY):
                    stack.push((neighborX, neighborY))


    This pseudo-code provides a starting point, ensuring that the flood fill algorithm works efficiently across varied applications. By adapting the flood fill algorithm to suit specific needs, developers can harness its power for numerous tasks in graphics and beyond.

  • Understanding Forward Chaining in Algorithms

    Understanding Forward Chaining in Algorithms

    Forward chaining is a method used in rule-based systems and expert systems to derive conclusions from a set of known facts. It is a data-driven approach that starts with the available data and uses inference rules to extract more data until a goal is reached. This approach is often utilized in artificial intelligence for applications such as automated reasoning and decision-making. In contrast, backward chaining starts with a goal and works backward to determine the facts that support it.

    What is Forward Chaining?

    Forward chaining operates by applying inference rules to known facts to generate new information. The process continues until a specific goal is achieved or no more rules can be applied. It is particularly effective in scenarios where all data is available at the outset, and the goal is to explore the entire implication of that data.

    In the context of algorithms, forward chaining evaluates each rule in sequence. If the conditions of a rule are satisfied by the current data, the rule is triggered, and its consequent is added to the set of known data. This continues iteratively, expanding the set of facts, until the system arrives at a conclusion or exhausts all possibilities.

    Applications of Forward Chaining

    Forward chaining is widely applied in various domains. In artificial intelligence, it is used within expert systems to simulate the decision-making ability of a human expert. For example, in medical diagnosis systems, forward chaining can help determine a diagnosis by applying medical knowledge rules to patient data.

    Other applications include automated control systems where forward chaining is used to decide on actions based on sensory data. Additionally, it finds use in data verification processes, where the method aids in ensuring that data conforms to established rules and standards before being processed further.

    Forward Chaining vs. Backward Chaining

    The primary difference between forward chaining and backward chaining lies in their approach to reaching conclusions. Forward chaining is data-driven, beginning with known facts and applying rules to extract further information. It is advantageous in situations where complete data is present and the goal is to explore the comprehensive implications of that data.

    In contrast, backward chaining is goal-driven. It starts with a hypothesis or a goal and works backward, asking what conditions must be met for the goal to be true. This method is typically used in diagnostic systems where the end goal is known, and the task is to ascertain the conditions or factors that lead to that goal.

    Each method has its strengths depending on the context. Forward chaining is suitable for systems needing to process a large amount of available data to reach various conclusions. Backward chaining is more efficient for problems where the objective is clearly defined, and the main task is to find supporting evidence or conditions.

    Ultimately, the choice between forward chaining and backward chaining depends on the specific requirements of the system being designed and the nature of the problem at hand.

  • Understanding ORA-00904: Invalid Identifier Error in SQL

    Understanding ORA-00904: Invalid Identifier Error in SQL

    The ORA-00904: invalid identifier error in SQL is a common stumbling block for database developers working with Oracle databases. This error arises when an SQL statement refers to an invalid column name or identifier. Understanding the causes and solutions for this error is crucial for ensuring smooth database operations.

    What is ORA-00904: Invalid Identifier?

    The ORA-00904 error signifies that an SQL query is attempting to access a column or identifier that does not exist, or is improperly named in the database schema. This error commonly occurs when there is a typo in the column name, or when the column does not exist in the table. The error message typically specifies which identifier is invalid, helping to narrow down the issue.

    Common Causes of ORA-00904 Error

    Several factors can lead to the ORA-00904 error. Understanding these can help in diagnosing and resolving the issue quickly:

    • Typographical Errors: A simple typo in the column name, such as a missing or extra character, can trigger the ORA-00904 error.
    • Case Sensitivity: Oracle databases are case-sensitive by default. If the column name in the query does not match the case of the column name in the database, this error may occur.
    • Incorrect Quotation Marks: Using incorrect quotation marks around identifier names can lead to this error. For example, using single quotes instead of double quotes for identifiers.
    • Non-Existent Columns: Attempting to access a column that does not exist in the specified table will result in this error.
    • Reserved Words: Using SQL reserved words as column names without proper handling (such as using double quotes) can cause the ORA-00904 error.

    How to Fix ORA-00904: Invalid Identifier

    Resolving the ORA-00904 error involves checking the SQL query and database schema for errors. Here’s how you can fix it:

    • Verify Column Names: Double-check the spelling and case of the column names in your query against the database schema. Ensuring they match exactly is crucial.
    • Correct Quotation Usage: Use double quotes for identifiers if they are case-sensitive or contain special characters. For example, write "EmployeeName" instead of 'EmployeeName'.
    • Check for Reserved Words: If you are using a reserved word as an identifier, ensure it is enclosed in double quotes.
    • Ensure Column Existence: Verify that all referenced columns exist within the specified tables. You can use SQL developer tools or queries to list the columns of a table.
    • Update Database Schema: If necessary, update the database schema to include the missing columns.

    Preventing ORA-00904 Errors in Your SQL Code

    Preventing ORA-00904 errors requires a proactive approach to SQL coding and database management:

    • Use Consistent Naming Conventions: Adopting a consistent naming convention for columns and tables can reduce the risk of typographical errors.
    • Leverage SQL Development Tools: Use tools like SQL Developer or Toad that offer syntax highlighting and auto-complete features to minimize errors in your SQL code.
    • Regularly Review Database Schemas: Keep your database documentation up-to-date and periodically review it to ensure schema integrity.
    • Implement Thorough Testing: Test SQL queries in a development environment before deployment to production to catch errors early.
    • Educate Team Members: Train team members on common SQL pitfalls and how to avoid them, ensuring everyone is aware of best practices.

    By understanding and applying these solutions, you can effectively manage and prevent ORA-00904: invalid identifier errors in your SQL databases, leading to more efficient and error-free database operations.

  • Understanding the OR Symbol in Binary Logic

    Understanding the OR Symbol in Binary Logic

    In the realm of binary logic, the OR symbol plays a crucial role in facilitating decision-making processes within digital systems. This symbol, often represented by a plus sign (+) or a vertical line (|), is integral to understanding how data is processed in computer systems. By examining the OR symbol’s function, one can gain insight into its applications in logic gates and its impact on computing technologies.

    What is the OR Symbol in Binary Logic?

    The OR symbol is a fundamental operator in binary logic used to perform logical disjunctions. In its simplest form, the OR operation takes two binary inputs and yields a true result if at least one of the inputs is true. Represented in binary terms, this means that for inputs A and B, the OR operation outputs a 1 if either A, B, or both are 1. This property makes the OR operator essential in various logic operations, especially in the design and functioning of computer processors and digital circuits.

    How Does the OR Symbol Work in Logic Gates?

    Logic gates are the building blocks of digital circuits, and the OR gate is one of the most fundamental among them. The OR gate functions by outputting a high signal (1) when one or more of its inputs are high. For instance, if an OR gate receives input signals of 0 and 1, it will output a 1, illustrating how the OR operation reflects flexibility in computing operations.

    OR gates are crucial in creating more complex logic circuits, serving as essential components in arithmetic logic units (ALUs) and various digital systems. Their ability to combine multiple conditions into a single logical output makes them invaluable in computational processes, playing a pivotal role in executing logical operations efficiently. By integrating OR gates with other types of gates, such as AND and NOT gates, more intricate operations can be performed, enabling advanced computing functionalities.

    Applications of the OR Sign in Computer Systems

    The OR sign finds numerous applications in computer systems, contributing significantly to their operational efficiency and logic processing capabilities. One common application is in condition checking within programming, where the OR operation determines the truth of compound conditions. This is particularly useful in decision-making processes where multiple conditions may lead to the same outcome.

    In digital electronics, the OR symbol is used in multiplexers, which select data from multiple inputs to a single output line. This capability is crucial in data routing and processing tasks, allowing for more flexible and efficient data management.

    Furthermore, OR operations are extensively utilized in network routing algorithms, where the determination of optimal paths often depends on multi-condition evaluations. The ability to simplify these evaluations into a single logical operation enhances both the speed and accuracy of network communications.

    Overall, the OR symbol and its associated logic operations form the backbone of modern computing, underscoring the importance of understanding its functionality and applications in digital systems. The OR symbol’s simplicity yet powerful application in decision-making processes serves as a cornerstone in the development and evolution of technology.

  • Mastering Python GroupBy for Data Analysis

    Mastering Python GroupBy for Data Analysis

    The Python GroupBy function is a powerful tool in the realm of data analysis, enabling users to segment and summarize data efficiently. Whether you are working with large datasets or need to perform complex operations, mastering GroupBy can significantly enhance your data processing capabilities. This article will guide you through using Python’s GroupBy with practical insights into df.groupby and pd groupby, along with optimization tips.

    What is the Python GroupBy Function?

    Python GroupBy is a method in the Pandas library that allows you to group data based on certain criteria. This function is essential for performing split-apply-combine operations on datasets. When you apply GroupBy, the data is divided into groups based on values of specific keys. Subsequently, you can apply functions to each group, transforming the data into a more meaningful form.

    GroupBy operations can greatly simplify statistical analysis tasks, such as calculating mean, sum, or other aggregations based on groupings. Whether you are filtering, aggregating, or pivoting data, Python GroupBy provides a streamlined approach to managing this process.

    How to Use df.groupby in Pandas?

    The df.groupby function is a cornerstone of data manipulation in Pandas. To utilize this function, first import Pandas and read your dataset into a DataFrame:

    import pandas as pd
    df = pd.read_csv('your_dataset.csv')

    You can then group data using df.groupby(). Here’s a basic example of grouping:

    grouped = df.groupby('column_name')

    This command groups the DataFrame by the values in ‘column_name’. Once grouped, you can apply aggregation functions like mean(), sum(), or count() to the grouped object:

    grouped_agg = grouped.mean()

    This flexibility allows you to derive insights from your data efficiently. By using df.groupby, complex data operations become manageable, enabling you to focus on analyzing the results.

    Practical Examples with pd GroupBy

    To illustrate pd groupby in action, consider a DataFrame containing sales data:

    data = {'Product': ['A', 'B', 'A', 'B'],
            'Sales': [100, 200, 150, 250],
            'Region': ['North', 'South', 'South', 'North']}
    df = pd.DataFrame(data)

    You can group this data by ‘Product’ and calculate the total sales per product:

    product_sales = df.groupby('Product')['Sales'].sum()

    This operation will output the total sales for each product, providing valuable insights into sales performance. Similarly, you can group by ‘Region’ to analyze sales trends across different regions:

    region_sales = df.groupby('Region')['Sales'].sum()

    These examples demonstrate how pd groupby can be leveraged to perform targeted analysis on datasets, extracting specific insights that drive business decisions.

    Tips for Optimizing GroupBy Operations

    While GroupBy is a powerful feature, optimizing its usage can help in managing large datasets more efficiently. Here are some tips:

    • Pre-processing Data: Clean and format your data before applying GroupBy. This can include handling missing values or converting data types.
    • Using Aggregation Functions: Apply aggregation functions directly after grouping to reduce the memory footprint and processing time.
    • Column Selection: Limit the number of columns you group by to streamline operations and reduce complexity.
    • Leveraging MultiIndex: When dealing with hierarchical data, use MultiIndex to structure your DataFrame effectively.

    By following these tips, you can ensure that your GroupBy operations are not only effective but also efficient, optimizing both performance and resource usage in your data analysis tasks.